Lec 28 · GPU Architecture (SIMT, warp, CUDA programming model, shared memory)
정밀 정리 · 검증 2026-09-24 09:49
1개요
1.1Lec20(ca_L20) 전반부 1~36쪽: CPU vs GPU 설계 목표, Summit 사례, heterogeneous computing
1.2warp·SIMT·SPMD, SIMD vs SIMT, warp-level FGMT 로 latency hiding, EPYC vs A100 memory hierarchy
1.3grid/thread block/SM, V100 SM·tensor core, CUDA programming model·block 독립성·memory space·qualifier
1.4vector_add 예제, control flow divergence, shared memory vs cache 와 CUDA variable type (37~82쪽은 29강)
2섹션별 정리 상황·문제 → 원인 → 해결
2.10:16–7:22GPGPU 동기와 CPU vs GPU 설계 목표
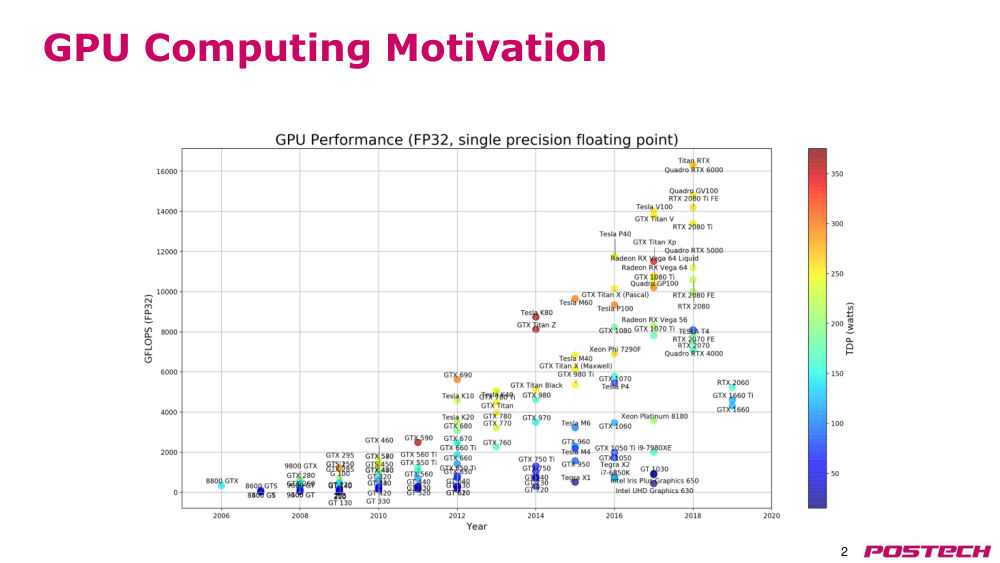
상황·문제CPU 의 throughput 향상은 느리고 GPU 의 FP32 성능은 급증(2쪽 chart) → 목적이 다른 두 설계를 비교
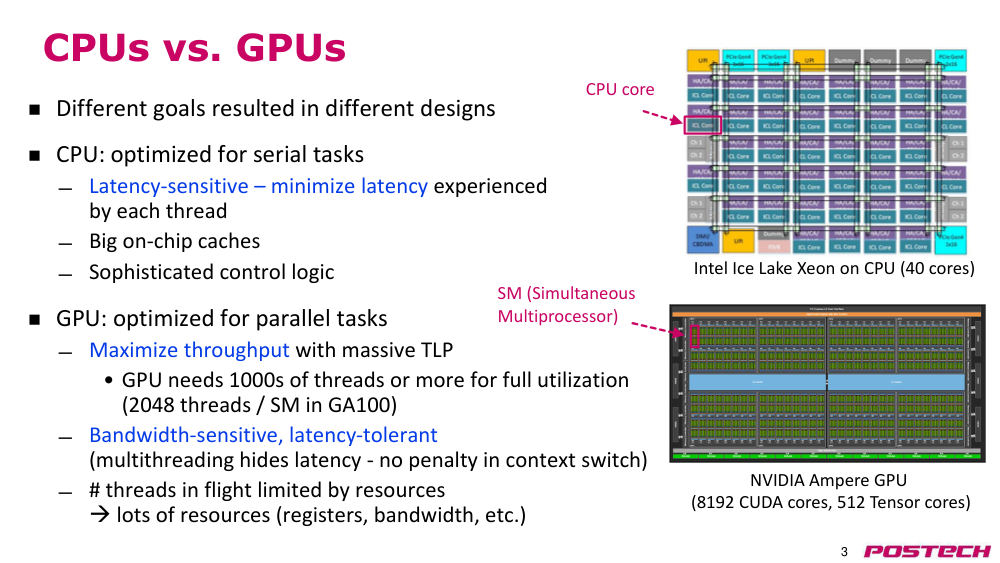
원인CPU 는 single-thread latency 최소화(큰 on-chip cache, OoO·branch predictor), GPU 는 개별 thread 성능을 신경 쓰지 않고 throughput 최대화
해결GPU 는 수만 thread 로 TLP 활용(A100 SM 당 2048 threads, SM ~100개), memory latency 는 다른 thread 로 숨기므로 latency-tolerant·bandwidth-sensitive
- A100: 8192 CUDA cores + 512 tensor cores vs Ice Lake Xeon 40 cores
- 대기 중 thread 에서 다른 thread 로 context switch 가 거의 무비용
- thread 수는 자원에 제한 → 큰 register file, 높은 cache·memory bandwidth
2.1.r.2NVIDIA A100 Tensor Core GPU Architecture whitepaper ↗ · A100 SM 구조, L1/shared 192 KB per SM, L2 cache
2.27:22–11:04대규모 시스템의 GPU 와 heterogeneous computing
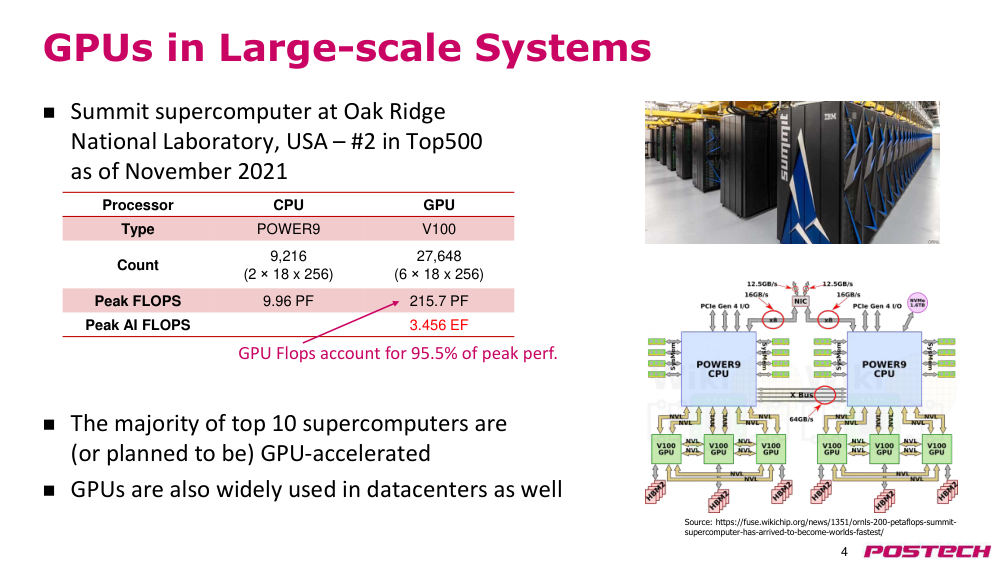
상황·문제Summit(Oak Ridge, 2021.11 Top500 #2) 같은 supercomputer·datacenter 에서 GPU 가 성능 대부분을 담당
원인GPU 수가 CPU 의 3배(27,648 vs 9,216), peak 215.7 PF vs 9.96 PF; 16-bit(AI) FLOPS 는 3.456 EF
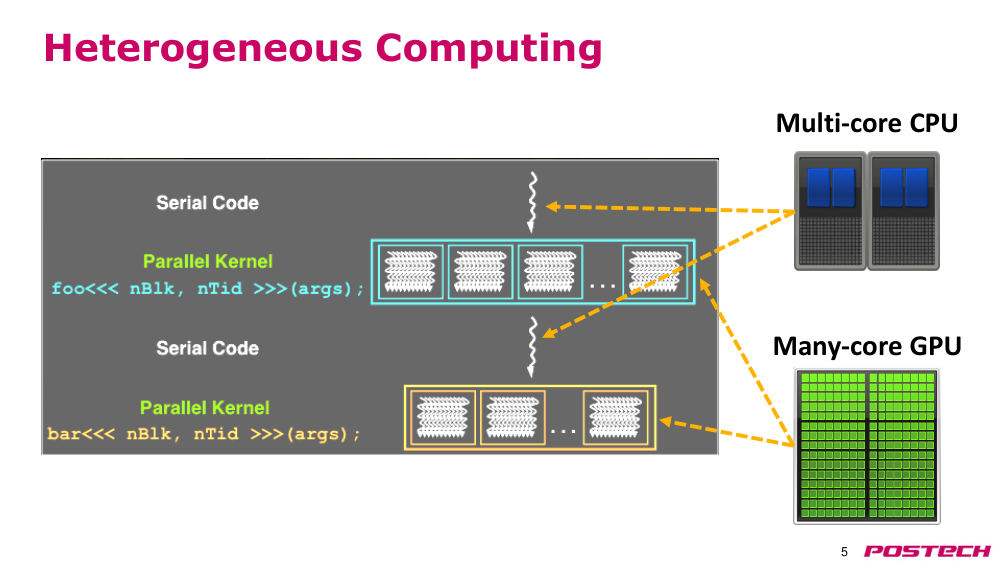
해결CPU 와 GPU 를 한 시스템에 결합: serial 부분은 multi-core CPU, parallel kernel 은 many-core GPU (heterogeneous computing)
- 노드당 POWER9 2개, 각 CPU 에 V100 3개, NVLink 로 GPU-GPU·CPU-GPU 고대역 연결
- top 10 대부분 GPU 가속
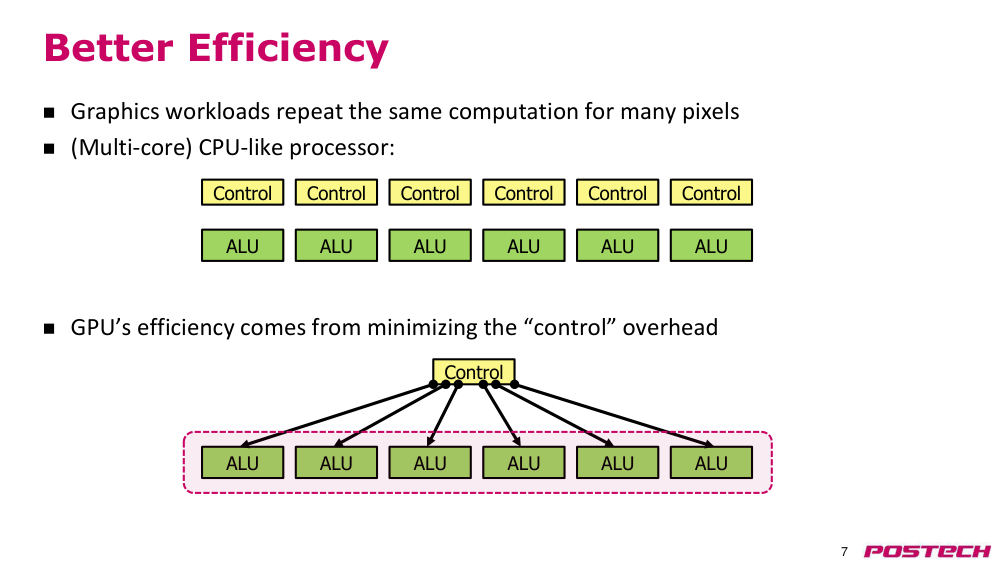
2.311:04–12:58GPU 효율의 원천: control overhead 최소화
상황·문제GPU 는 원래 모니터의 많은 pixel 에 같은 계산을 반복하기 위해 설계
원인CPU 형 processor 는 ALU 마다 control logic overhead 가 붙음; 실제 계산은 ALU 만 수행
해결control logic 을 최소화하고 die area 를 ALU 에 최대한 투자
- control 은 ALU 를 쓰기 위한 overhead
- 한 control 이 여러 ALU 를 구동
2.412:58–16:06warp 와 CUDA/OpenCL 용어
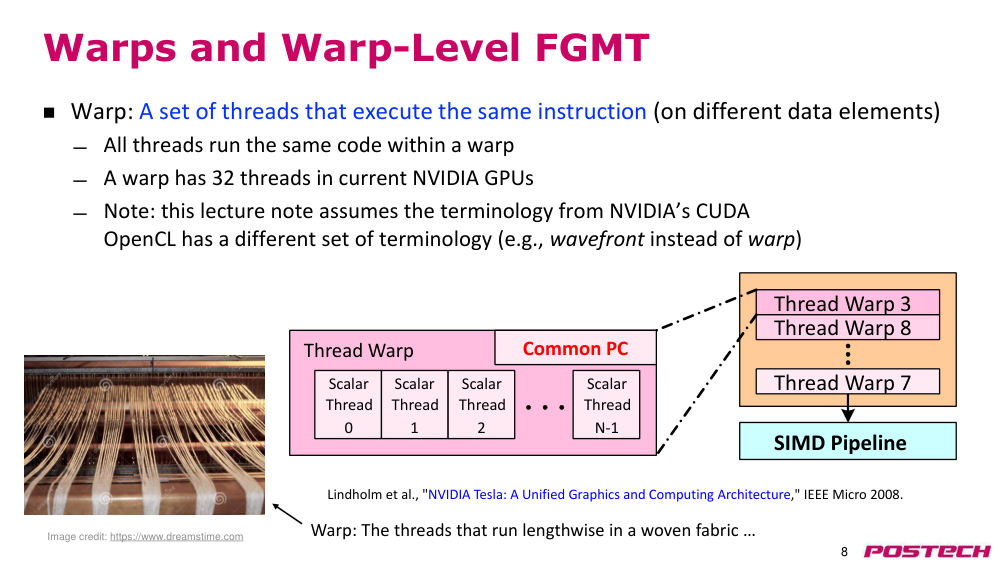
상황·문제control overhead 를 줄이려면 여러 ALU 가 한 instruction 으로 움직여야 함
원인같은 instruction 을 다른 data 에 실행하는 SIMD 방식
해결warp = 같은 instruction 을 실행하는 thread 묶음(현재 NVIDIA 32 threads), warp 내 PC 하나 공유; 여러 warp 를 교대로 SIMD pipeline 에 투입해 latency hiding
- warp 어원: 직물에서 길이 방향으로 달리는 날실
- CUDA 는 proprietary, OpenCL 은 표준(AMD 등), OpenCL 은 warp 대신 wavefront
2.4.r.1Lindholm et al., NVIDIA Tesla: A Unified Graphics and Computing Architecture (IEEE Micro 2008, CMU 강의 사본) ↗ · 8쪽 인용 원 논문, SIMT·warp 용어의 출처
2.4.r.2Wikipedia: Single instruction, multiple threads ↗ · SIMT, 32-thread warp lock-step, branch divergence 의 predicate masking
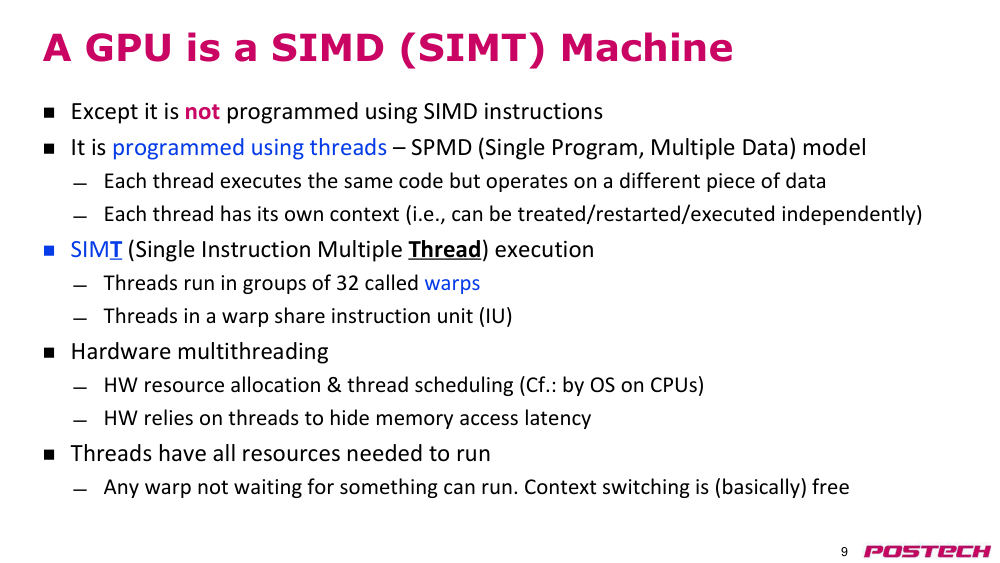
2.516:06–21:06SIMT machine: SPMD 프로그래밍과 HW multithreading
상황·문제GPU 는 SIMD machine 이지만 SIMD instruction 으로 프로그래밍하지 않음
원인vector ISA 는 VADD 처럼 instruction 당 data 개수를 프로그래머가 신경 써야 함
해결SPMD: single thread 코드를 쓰고 thread block 으로 묶어 GPU 에 매핑; 각 thread 는 자기 context 를 가지며 스케줄링·자원 할당은 HW 가 수행
- SIMT 는 NVIDIA 가 만든 용어
- CPU 는 OS(software) 가 context switch, GPU 는 HW → software 개입 비용 제거
- 성능을 위해선 thread 간 상호작용, memory 접근, control divergence 를 고려
2.5.r.1Wikipedia: Single instruction, multiple threads ↗ · SIMT, 32-thread warp lock-step, branch divergence 의 predicate masking
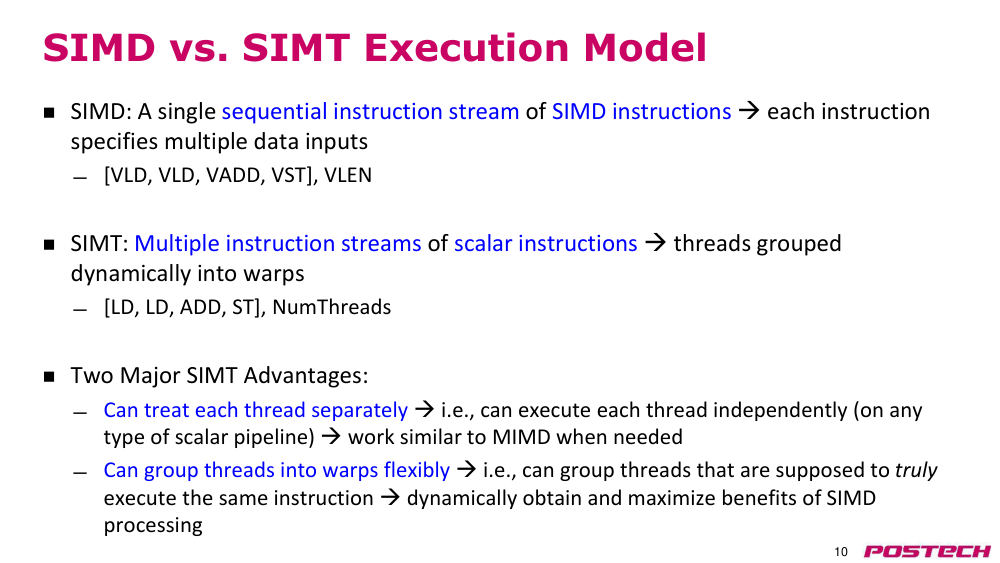
2.621:06–24:05SIMD vs SIMT execution model
상황·문제SIMD 는 SIMD instruction 의 단일 sequential stream(VLD, VADD...)
원인SIMT 는 scalar instruction 을 쓰는 여러 thread stream 을 동적으로 warp 로 묶음
해결SIMT 장점 두 가지: thread 별 control flow divergence 허용(MIMD 유사, 느리지만 가능), warp 를 유연하게 재구성해 SIMD 이점 확보
- divergence 가 적으면 성능 문제 없음
- 다른 warp 의 thread 를 임시로 새 warp 로 묶을 수 있음(뒤 슬라이드)
2.6.r.1Wikipedia: Single instruction, multiple threads ↗ · SIMT, 32-thread warp lock-step, branch divergence 의 predicate masking
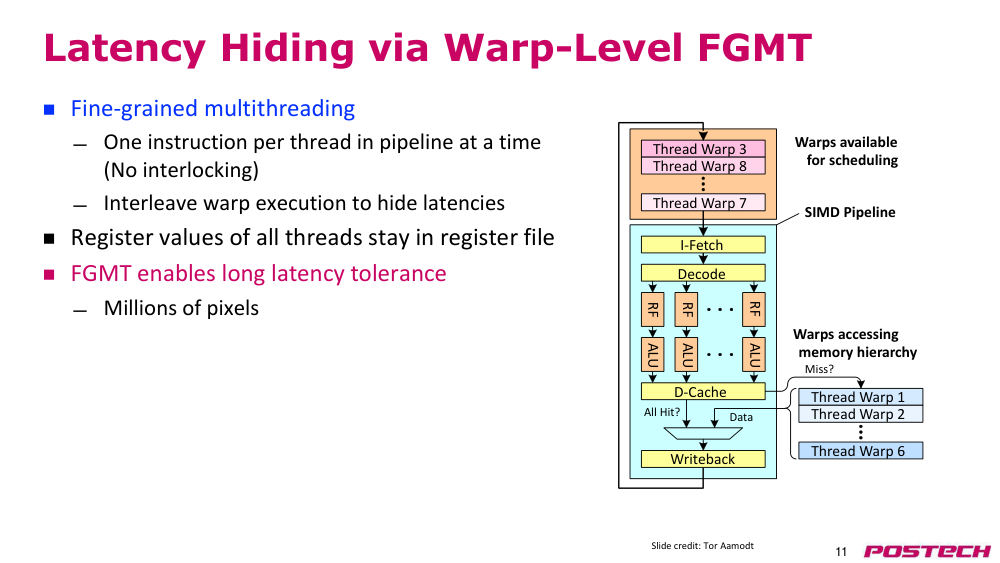
2.724:05–30:24warp-level FGMT 를 통한 latency hiding
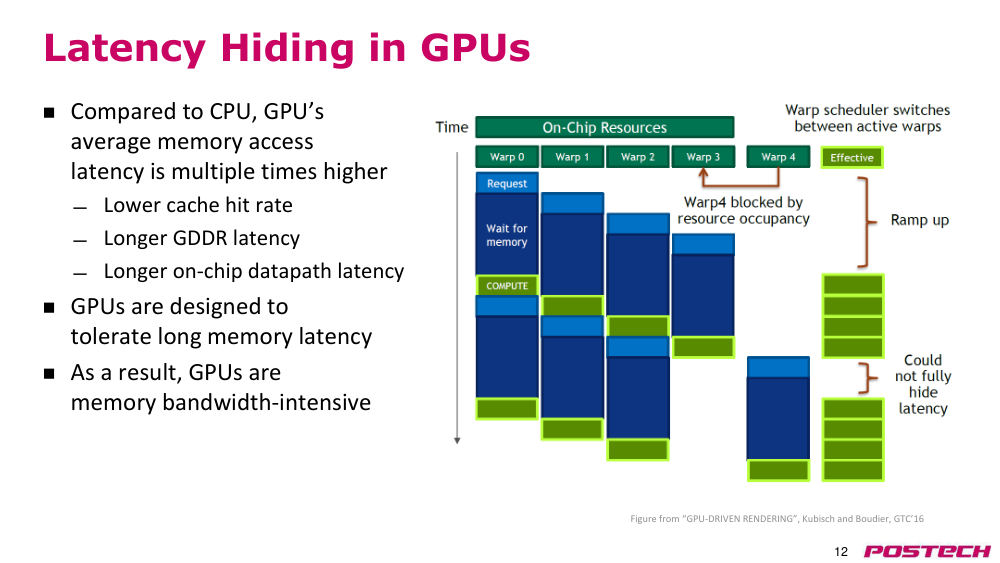
상황·문제GPU 의 memory access latency 는 CPU 의 수 배(낮은 cache hit rate, 긴 GDDR·on-chip datapath latency)
원인GPU 는 latency 가 아닌 throughput 에 최적화, 수백만 pixel 처리 요구
해결5-stage RISC-V 유사 pipeline 에 넓은 register file·다수 FU; cache miss warp 는 대기 queue 로, 다른 warp 실행 → register 값이 모두 RF 에 상주해 context switch penalty 거의 없음
- CPU context switch 는 OS 가 state 를 memory 로 save/restore
- warp 들을 interleave 해 연속 cycle 에 memory 요청
- 결과적으로 GPU 는 memory bandwidth-intensive
2.830:24–33:23chip area 와 memory hierarchy 비교 (EPYC Milan vs A100)
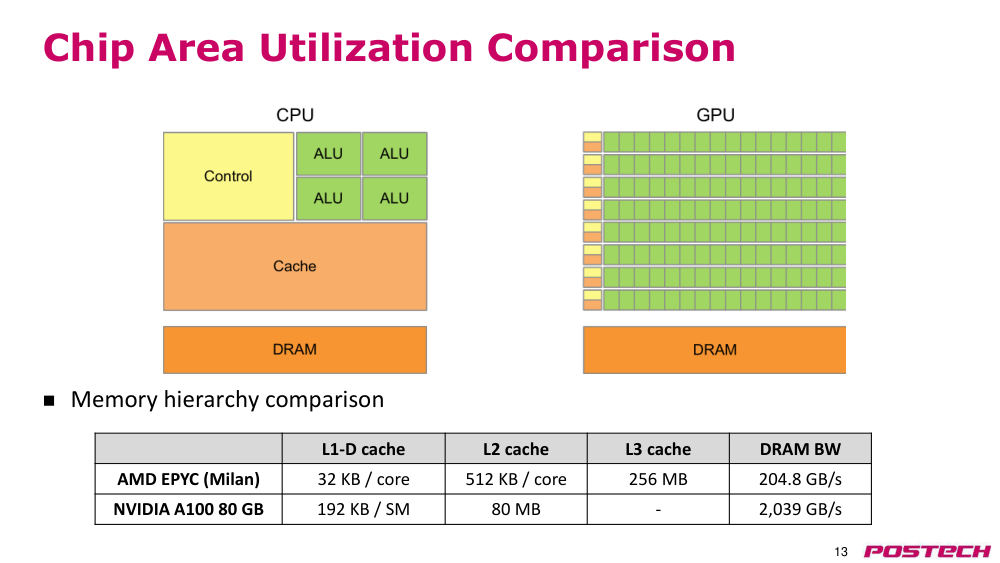
상황·문제CPU 는 큰 control logic·소수의 큰 core·큰 cache, GPU 는 작은 control·작은 cache 로 ALU 면적 극대화
원인A100 L1 은 SM 당 192 KB 로 커 보여도 최대 2048 threads 가 공유 → thread 당 L1 용량은 훨씬 작음
해결대신 DRAM bandwidth 가 약 10배(204.8 vs 2,039 GB/s) → 많은 compute unit 을 먹여 살림
- EPYC Milan: L1D 32 KB/core, L2 512 KB/core, L3 256 MB
- L2: 슬라이드 A100 80GB 80 MB (강의 구두 '8 MB' 는 오기)
2.8.r.1NVIDIA A100 Tensor Core GPU Architecture whitepaper ↗ · A100 SM 구조, L1/shared 192 KB per SM, L2 cache
2.933:23–39:39GPU 구성: grid·thread block·SM 과 V100 SM
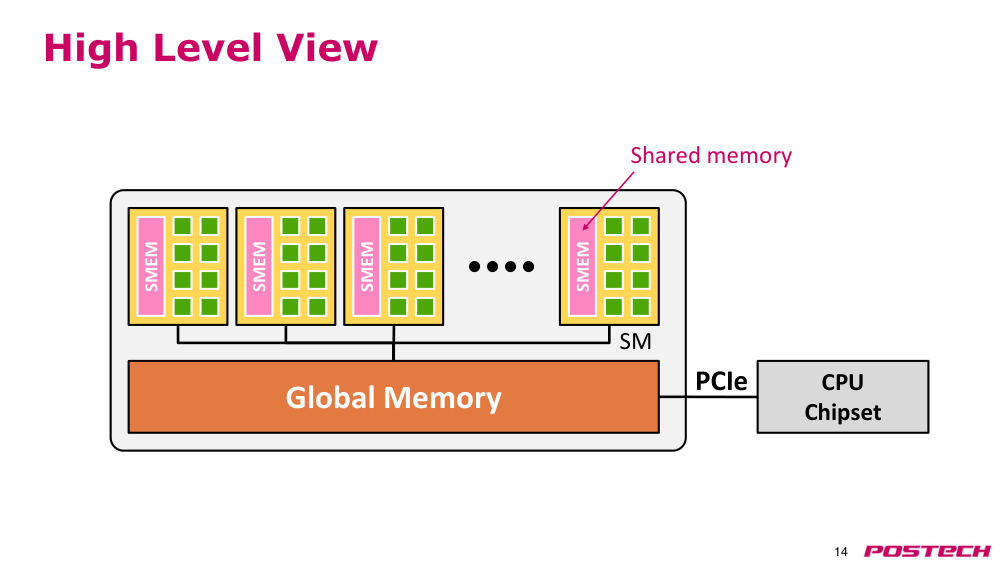
상황·문제GPU 는 여러 SM 이 global memory 를 공유하고 SM 마다 shared memory 를 가짐, CPU 와 PCIe 로 연결
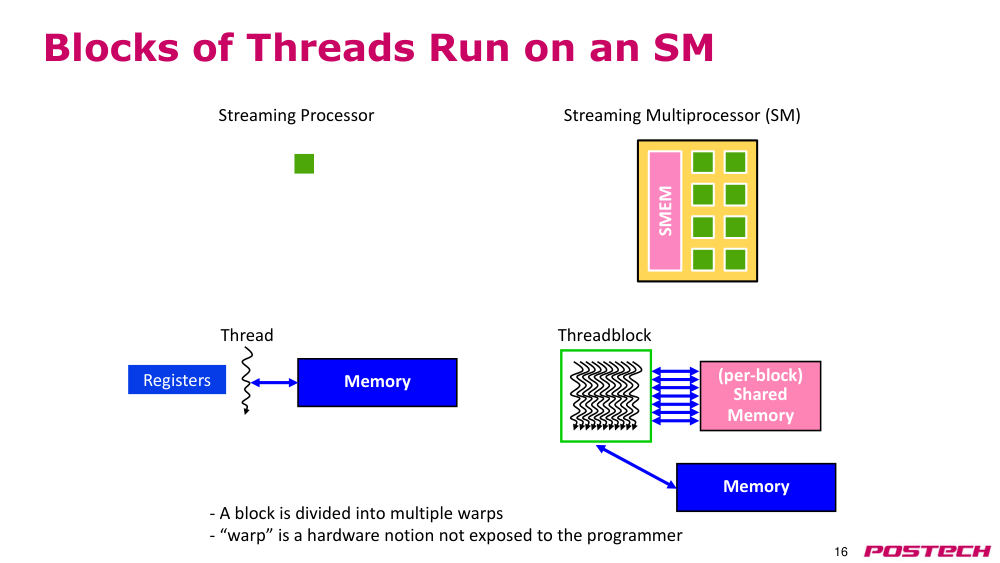
원인kernel launch → grid, grid 는 thread block 들, 각 block 은 한 SM 에 매핑; streaming processor 가 thread 하나 실행
해결block 내 thread 는 per-block shared memory(on-chip, DRAM 보다 고대역) 로 데이터 공유; block 은 warp 로 나뉘지만 warp 는 programmer 에 비노출
- 다른 block 의 shared memory 는 접근 불가
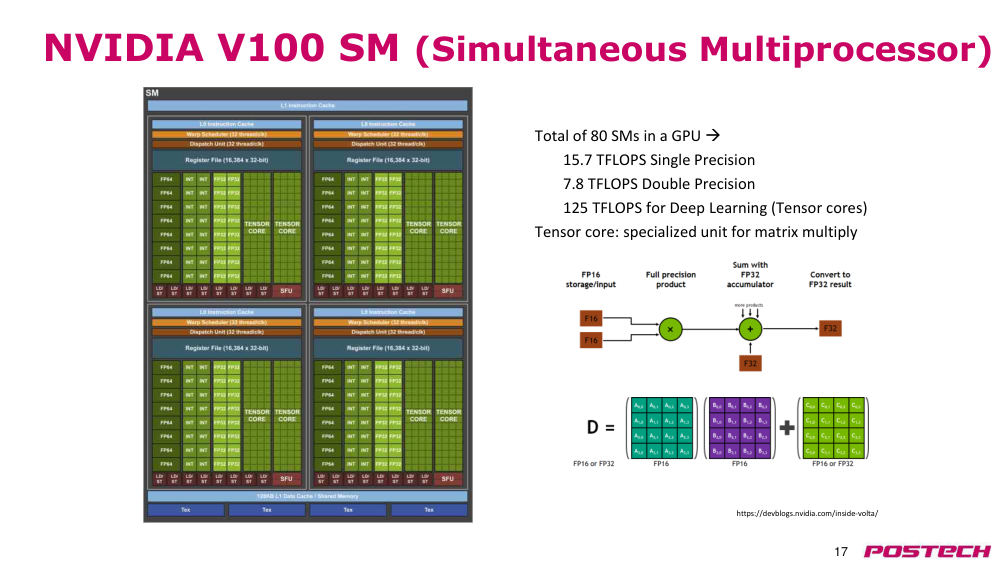
- V100: 80 SMs, FP32 15.7 / FP64 7.8 / Tensor 125 TFLOPS, SM 은 sub-core 로 분할
- tensor core: 4x4 FP16 tile 두 개 곱 + FP16/FP32 tile 누적
2.9.r.1NVIDIA Tesla V100 GPU Architecture whitepaper (2017) ↗ · V100 80 SMs, FP32 15.7 TFLOPS, 125 Tensor TFLOPS, SM 구조·tensor core
2.1039:39–44:27Q&A: SM 을 sub-core 로 나누는 이유
상황·문제학생 질문: 왜 SM 을 여러 sub-core 로 나누는가 (강의자도 공식 용어·이유는 NVIDIA 미공개라고 전제)
원인하나의 큰 sub-core 면 register file·compute unit complex 가 커져 wire 가 길어지고 access latency·동작 frequency 에 불리
해결반대로 작은 SM 여러 개로 쪼개면 L1 I-cache·data cache·texture unit 을 sub-core 들이 공유하지 못함 → 중간 설계로 추정
- 강의자의 추론이며 NVIDIA 공식 설명 아님
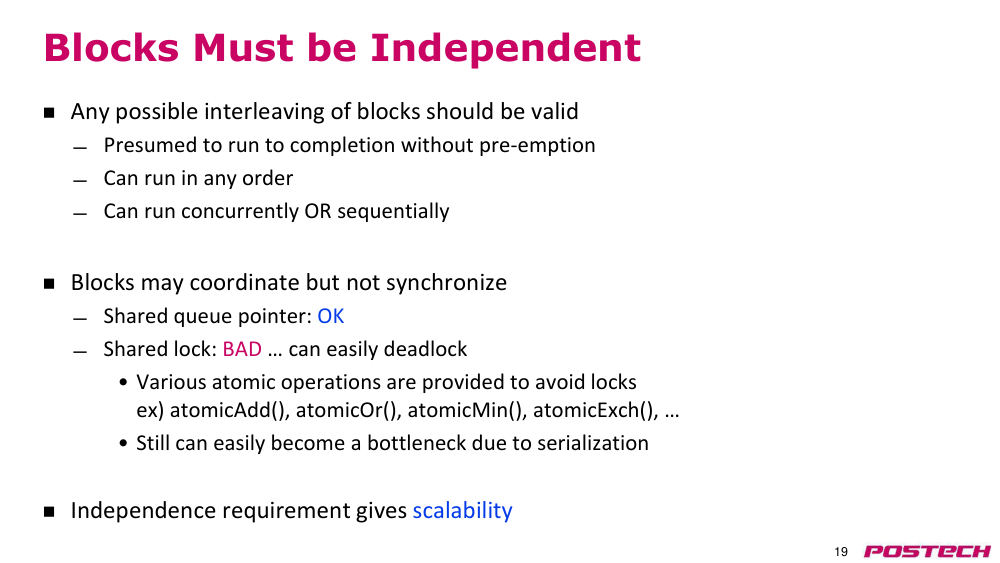
2.1144:27–50:01CUDA programming model 과 block 독립성
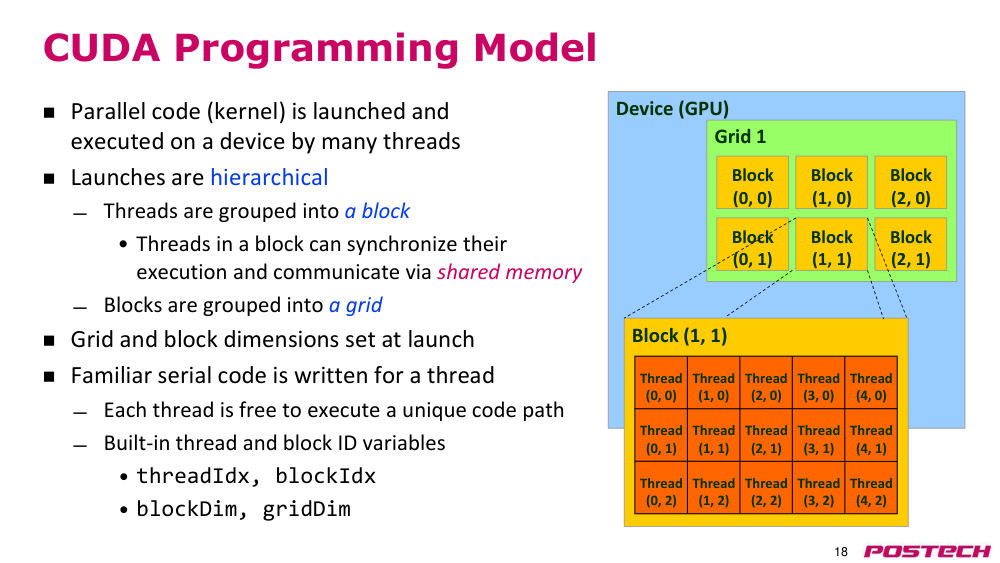
상황·문제CUDA 프로그램은 grid → thread block → thread 계층을 알아야 함 (warp 는 비노출)
원인block 내 thread 는 shared memory 로 통신·synchronize 가능하지만 block 간 동기화 수단은 없음
해결block 은 서로 독립적으로 작성: 어떤 순서·동시/순차 실행도 valid, preemption 없이 완료 가정; 공유 lock 대신 atomic operation 사용(남용 시 병목)
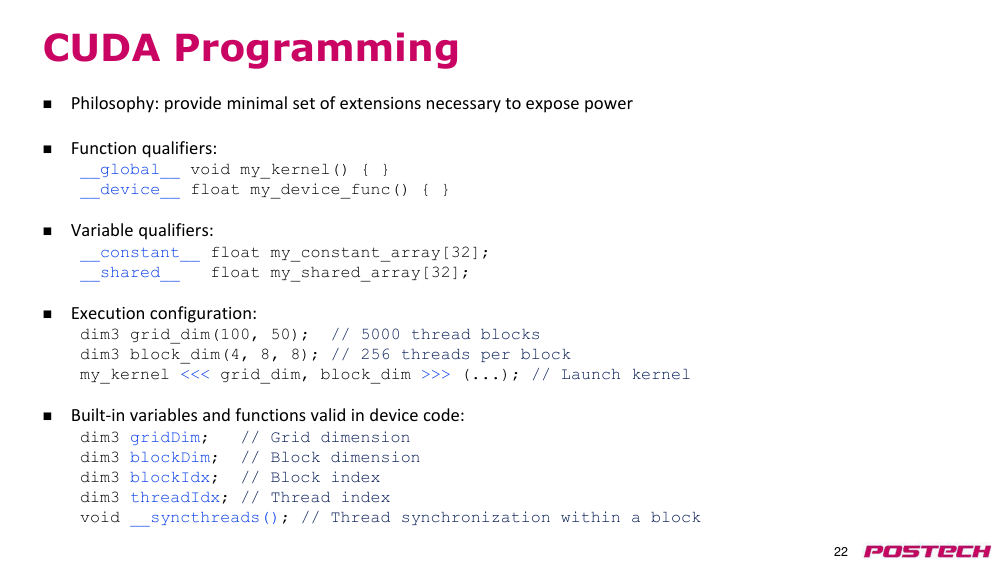
- grid·block dimension 은 host 의 launch 시 지정, threadIdx/blockIdx/blockDim/gridDim 로 담당 data 결정
- shared queue pointer OK, shared lock 은 deadlock 위험
- 독립성 덕분에 block 간 통신 HW 없이 scalability 확보
2.11.r.1NVIDIA CUDA C++ Programming Guide ↗ · thread hierarchy, memory hierarchy, qualifier, SIMT 공식 문서(목차에서 해당 절로 이동)
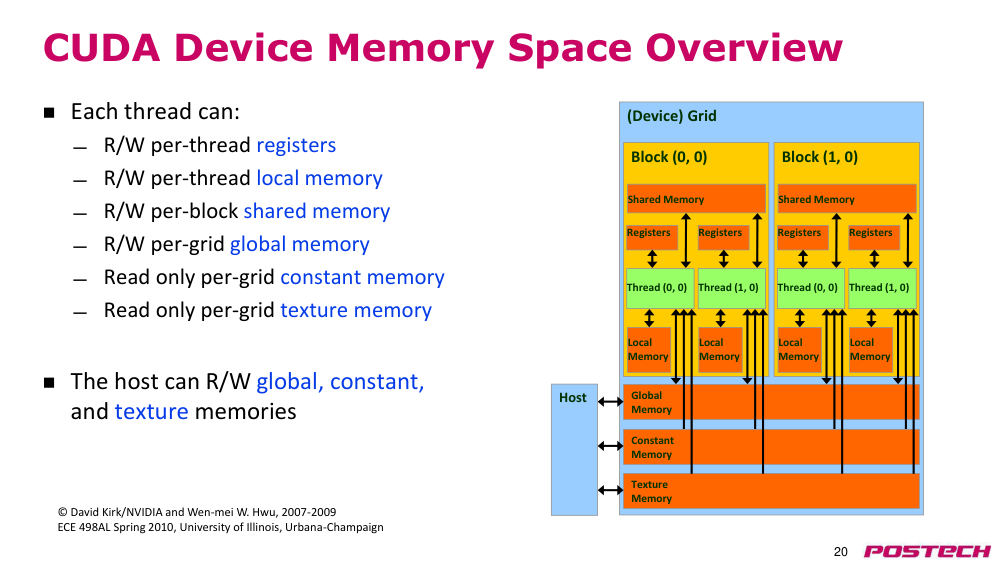
2.1250:01–56:23CUDA memory space 와 qualifier, kernel launch
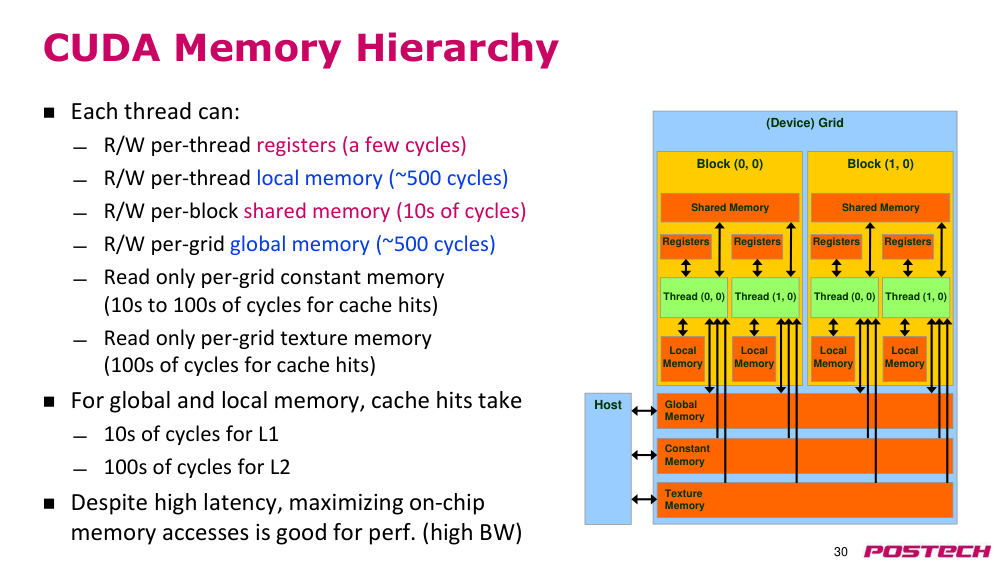
상황·문제thread 는 register·local, block 은 shared, grid 는 global·constant·texture memory 를 가짐
원인local memory 는 이름과 달리 DRAM(scope 만 thread-local), global 도 DRAM; constant 는 GPU 에게만 read-only 로 host 가 쓸 수 있음
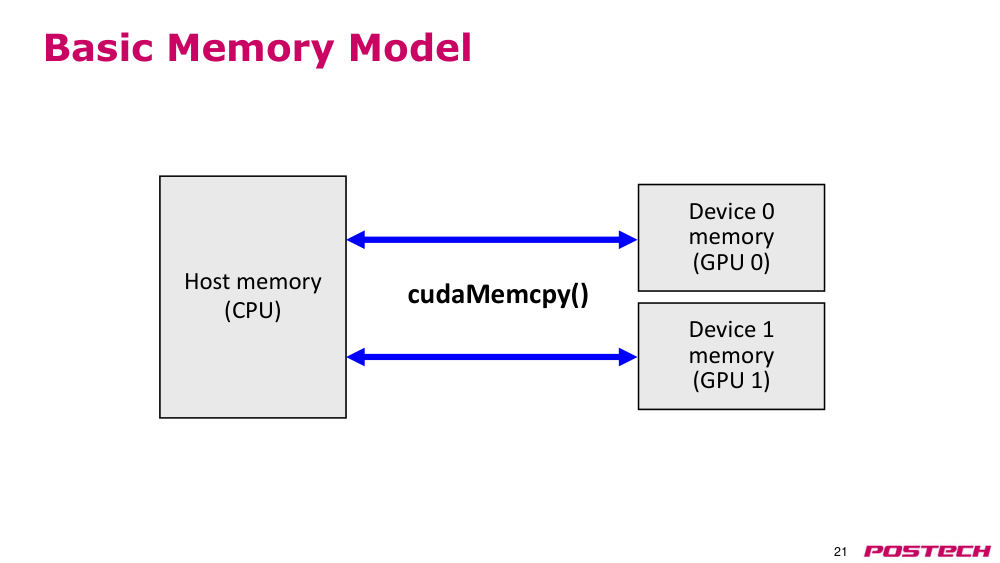
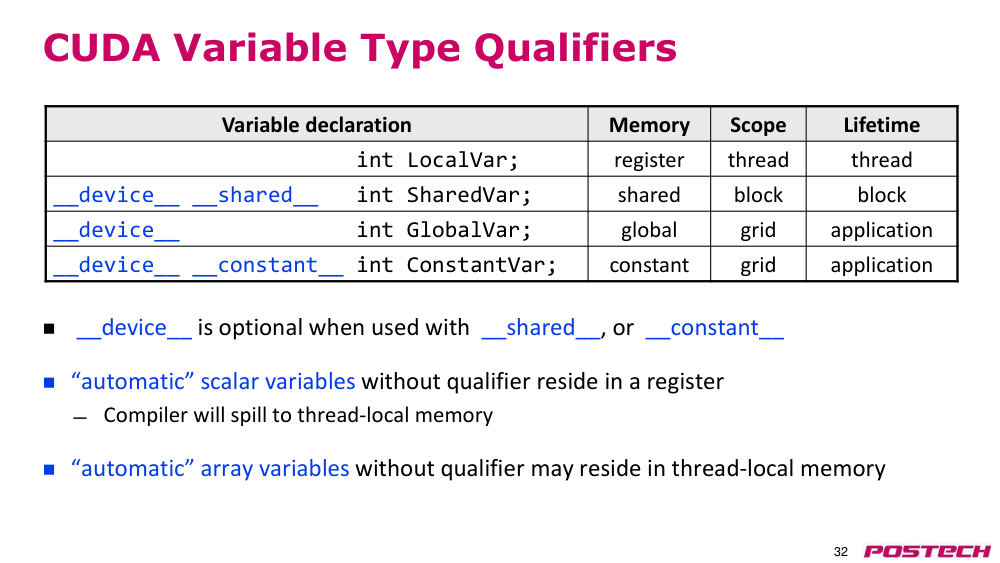
해결host↔device 전송은 cudaMemcpy; __global__(host 가 launch) / __device__(GPU 내부 호출) function qualifier, __shared__·__constant__ variable qualifier; <<<grid, block>>> 으로 launch
- 변수가 많으면 register 대신 local memory 로 감
- dim3 block_dim(4,8,8) → 256 threads/block
- __syncthreads() 로 block 내 동기화
2.12.r.1NVIDIA CUDA C++ Programming Guide ↗ · thread hierarchy, memory hierarchy, qualifier, SIMT 공식 문서(목차에서 해당 절로 이동)
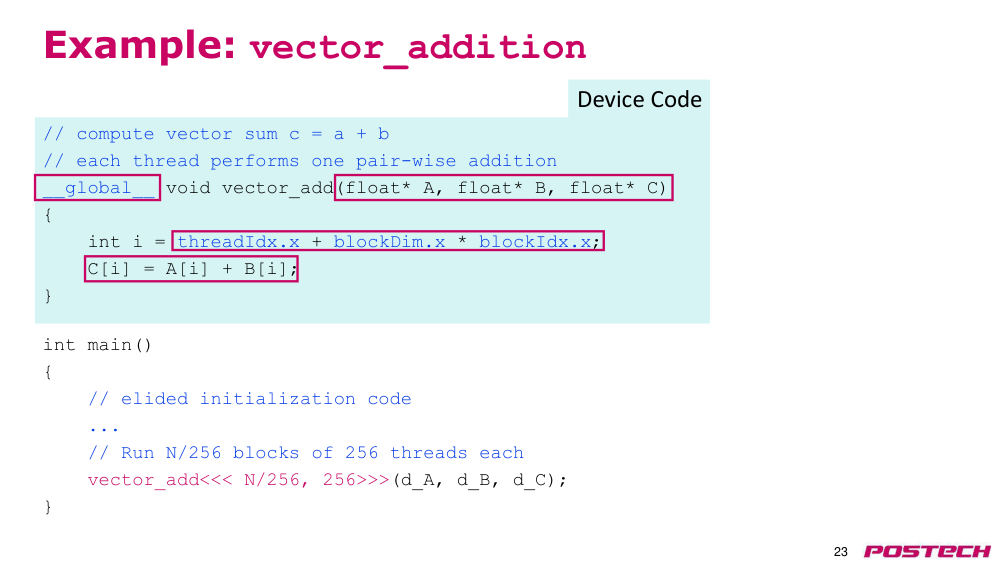
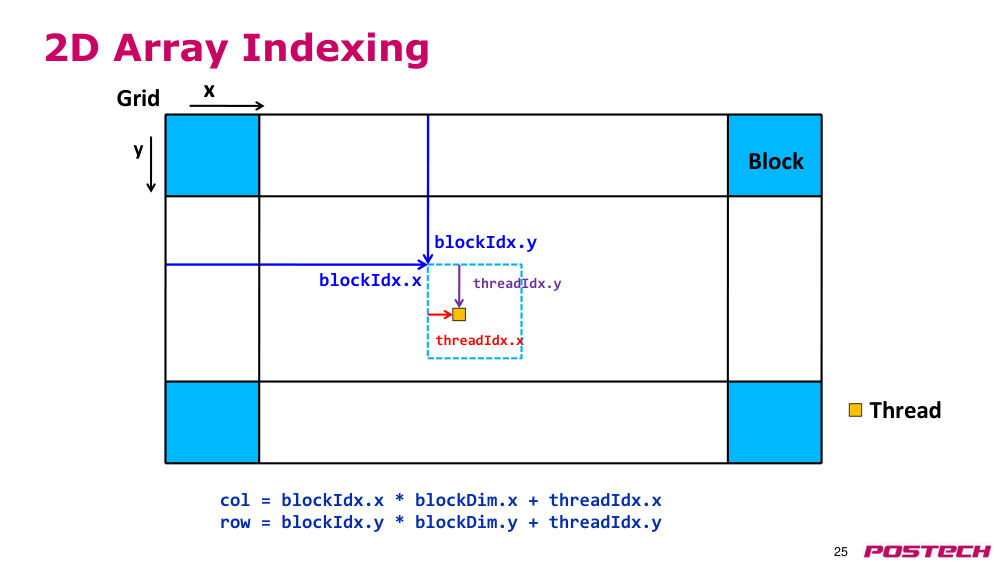
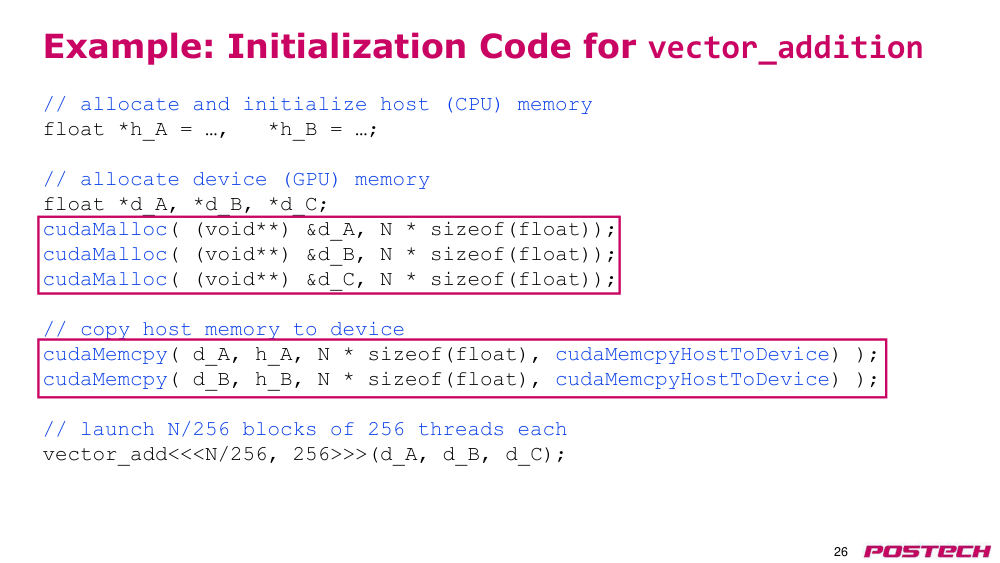
2.1356:23–1:01:50예제: vector_add 와 2D indexing, host 초기화 코드
상황·문제single thread 관점으로 kernel 을 쓰고 각 thread 가 처리할 index 를 계산해야 함
원인i = threadIdx.x + blockDim.x * blockIdx.x; 2D 는 col/row 를 x·y 각각 계산
해결host 는 cudaMalloc → cudaMemcpy(HostToDevice) → vector_add<<<N/256, 256>>> → cudaMemcpy(DeviceToHost) 로 결과 회수
- 예: 1024 원소면 원소당 thread 하나
- 3664~3708 출석 확인(손 들기)
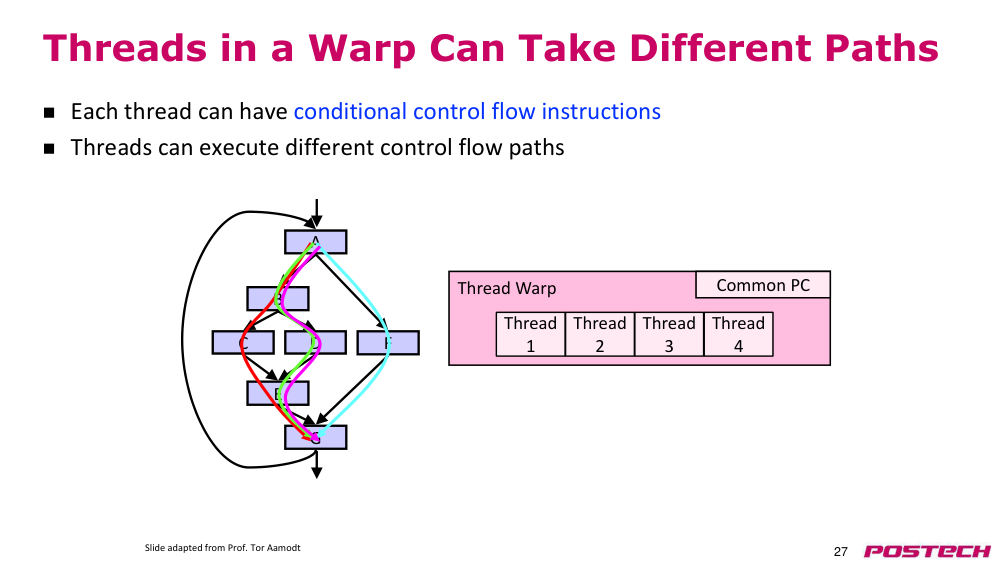
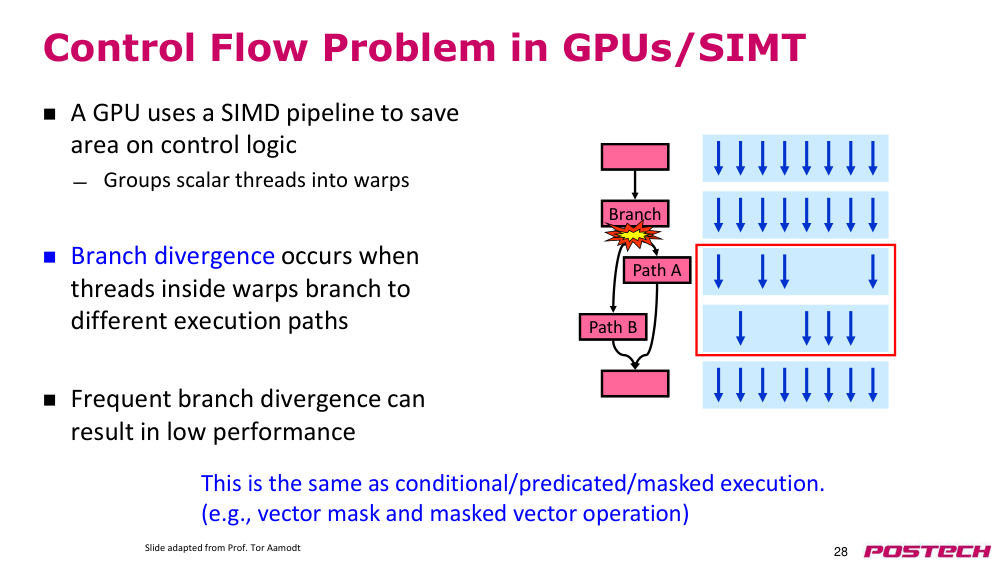
2.141:01:50–1:06:28warp 내 control flow divergence
상황·문제warp 내 thread 들이 if 등으로 서로 다른 control flow path 를 탈 수 있음
원인한 warp 로 시작했다가 분기 시 path A/B 별 warp 를 동적으로 만들고, 각 warp 에서 비활성 lane 의 HW 자원이 낭비
해결분기가 합쳐지면 다시 한 warp 로; divergence 는 최소화하되 불가피해도 정확히 동작
- predicated / masked execution 과 같은 개념
- vector machine 은 mask 계산 코드가 따로 필요, CUDA 는 thread 가 if 만 실행
2.14.r.1Wikipedia: Single instruction, multiple threads ↗ · SIMT, 32-thread warp lock-step, branch divergence 의 predicate masking
2.151:06:28–1:16:46shared memory: memory hierarchy, cache 와 비교, variable type
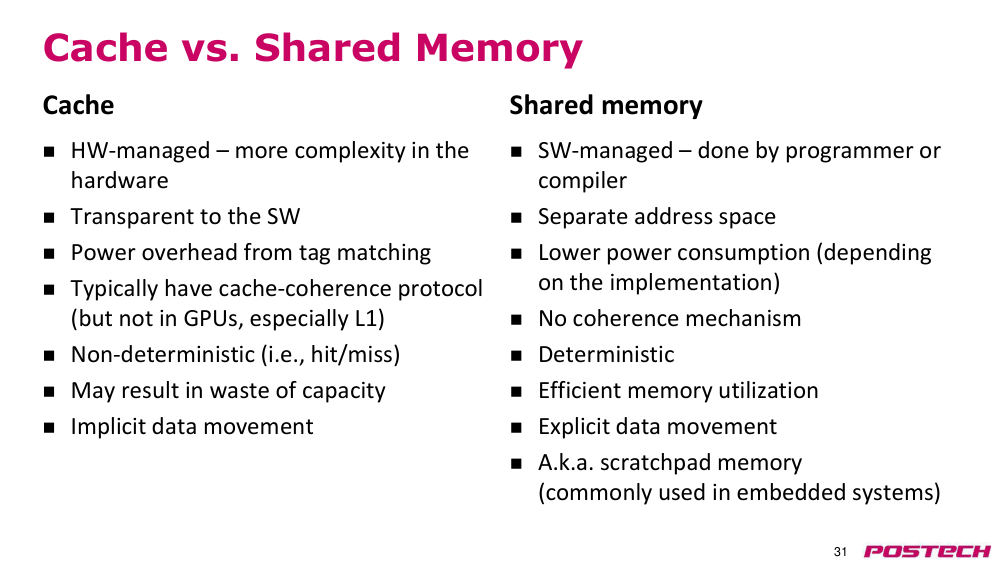
상황·문제많은 thread 가 많은 data 를 다뤄 L1/L2 cache thrashing, hit rate 낮고 GPU cache 는 CPU 보다 느림
원인register 는 few cycles, shared 는 10s cycles, local·global 은 DRAM 이라 ~500 cycles
해결shared memory(SRAM scratchpad): software-managed, tag 없음, deterministic, explicit 이동 → block 내 공유 data 를 고대역·저지연으로 접근
- GPU L1 은 coherence 없음, 단일 shared L2 는 coherent 로 볼 수 있음
- automatic scalar 는 register(넘치면 local spill), automatic array 는 local memory
- shared 변수는 block 수명, block 종료 시 소멸; shared memory 활용법은 다음 강의
2.15.r.1Wikipedia: Scratchpad memory ↗ · software-managed on-chip memory, CUDA shared memory 가 scratchpad 임을 명시
2.15.r.2NVIDIA CUDA C++ Best Practices Guide ↗ · coalesced access, shared memory bank conflict, shared memory 로 tiled matrix multiply
3핵심 개념
3.1SIMT(Single Instruction Multiple Threads)
scalar thread 로 프로그래밍하고 HW 가 warp 로 묶어 SIMD pipeline 에서 실행
3.1.r.1Wikipedia: Single instruction, multiple threads ↗ · SIMT, 32-thread warp lock-step, branch divergence 의 predicate masking
3.2warp(워프)
같은 instruction 을 실행하는 32 threads 묶음, PC 공유, programmer 에 비노출
3.2.r.1Lindholm et al., NVIDIA Tesla: A Unified Graphics and Computing Architecture (IEEE Micro 2008, CMU 강의 사본) ↗ · 8쪽 인용 원 논문, SIMT·warp 용어의 출처
3.3fine-grained multithreading(FGMT)
warp 를 cycle 단위로 교차 실행해 memory latency 를 숨김, register 가 RF 에 상주
3.4thread block / grid
block 은 한 SM 에서 실행되며 shared memory 공유, grid 는 kernel launch 단위
3.4.r.1NVIDIA CUDA C++ Programming Guide ↗ · thread hierarchy, memory hierarchy, qualifier, SIMT 공식 문서(목차에서 해당 절로 이동)
3.5heterogeneous computing(이종 컴퓨팅)
serial 은 CPU, parallel kernel 은 GPU 에 매핑
3.6branch divergence(분기 발산)
warp 내 thread 가 다른 path 로 갈라져 일부 lane 만 active → 성능 저하
3.6.r.1Wikipedia: Single instruction, multiple threads ↗ · SIMT, 32-thread warp lock-step, branch divergence 의 predicate masking
3.7tensor core
4x4 FP16 tile 곱과 FP16/FP32 누적을 cycle 당 수행하는 matrix 전용 unit
3.7.r.1NVIDIA Tesla V100 GPU Architecture whitepaper (2017) ↗ · V100 80 SMs, FP32 15.7 TFLOPS, 125 Tensor TFLOPS, SM 구조·tensor core
3.8shared memory / scratchpad
software-managed on-chip SRAM, block 내 공유, tag·coherence 없음
3.8.r.1Wikipedia: Scratchpad memory ↗ · software-managed on-chip memory, CUDA shared memory 가 scratchpad 임을 명시
3.9local memory
thread-local scope 이지만 실제로는 DRAM, register spill·array 가 배치
3.10__global__ / __device__ / __shared__ / __constant__
host launch 가능 kernel / GPU 내부 함수 / block shared 변수 / constant 변수
3.10.r.1NVIDIA CUDA C++ Programming Guide ↗ · thread hierarchy, memory hierarchy, qualifier, SIMT 공식 문서(목차에서 해당 절로 이동)
4스스로 확인
4.1GPU 가 latency-tolerant 할 수 있는 이유는?
답
많은 warp 의 register 가 RF 에 상주해 memory 대기 warp 대신 다른 warp 를 거의 무비용으로 실행
4.2SIMD 와 SIMT 의 프로그래밍 차이는?
답
SIMD 는 vector instruction stream, SIMT 는 scalar thread 코드를 HW 가 warp 로 묶음
4.3block 간 동기화를 하면 안 되는 이유는?
답
block 실행 순서·동시성이 보장되지 않아 lock 은 deadlock 가능, 독립성이 scalability 의 근거
4.4CUDA 'local memory' 는 어디에 있나?
답
DRAM. 이름은 scope(thread-local) 를 뜻함
4.5A100 의 L1 이 192 KB/SM 인데도 thread 당 용량이 작은 이유는?
답
SM 당 최대 2048 threads 가 공유하기 때문
4.6shared memory 가 cache 대비 갖는 장점 두 가지는?
답
tag 없음(저전력·단순), deterministic 하고 software 가 필요한 data 만 배치
5참고 자료
5.1Hennessy & Patterson, Computer Architecture: A Quantitative Approach 6th ed. (Elsevier) ↗ · Ch.4 Data-Level Parallelism in Vector, SIMD, and GPU Architectures (82쪽 추천 4.4-4.9)
5.2NVIDIA CUDA C++ Programming Guide ↗ · thread hierarchy, memory hierarchy, qualifier, SIMT 공식 문서(목차에서 해당 절로 이동)
5.3NVIDIA CUDA C++ Best Practices Guide ↗ · coalesced access, shared memory bank conflict, shared memory 로 tiled matrix multiply
5.4NVIDIA Tesla V100 GPU Architecture whitepaper (2017) ↗ · V100 80 SMs, FP32 15.7 TFLOPS, 125 Tensor TFLOPS, SM 구조·tensor core
5.5NVIDIA A100 Tensor Core GPU Architecture whitepaper ↗ · A100 SM 구조, L1/shared 192 KB per SM, L2 cache
5.6Lindholm et al., NVIDIA Tesla: A Unified Graphics and Computing Architecture (IEEE Micro 2008, CMU 강의 사본) ↗ · 8쪽 인용 원 논문, SIMT·warp 용어의 출처