Lec 13 · Classic VLIW 의 한계와 EPIC/IA-64(Itanium)
정밀 정리 · 검증 2026-09-24 03:15
1개요
1.1Lec 9(VLIW) part 3: 12강에서 설명 없이 끝난 p16 부터 p31 까지.
1.2classic VLIW 문제(호환성·code size·variable latency·branch)와 encoding 개선(압축, parallel group, UniOp).
1.3EPIC/IA-64: bundle·template, rotating register file, predicated execution, control·data speculation.
1.4static scheduling 의 한계, Itanium 2 성능과 Itanium 단종(2019)으로 마무리.
2섹션별 정리 상황·문제 → 원인 → 해결
2.10:00–2:20복습: VLIW, loop unrolling, software pipelining, trace scheduling
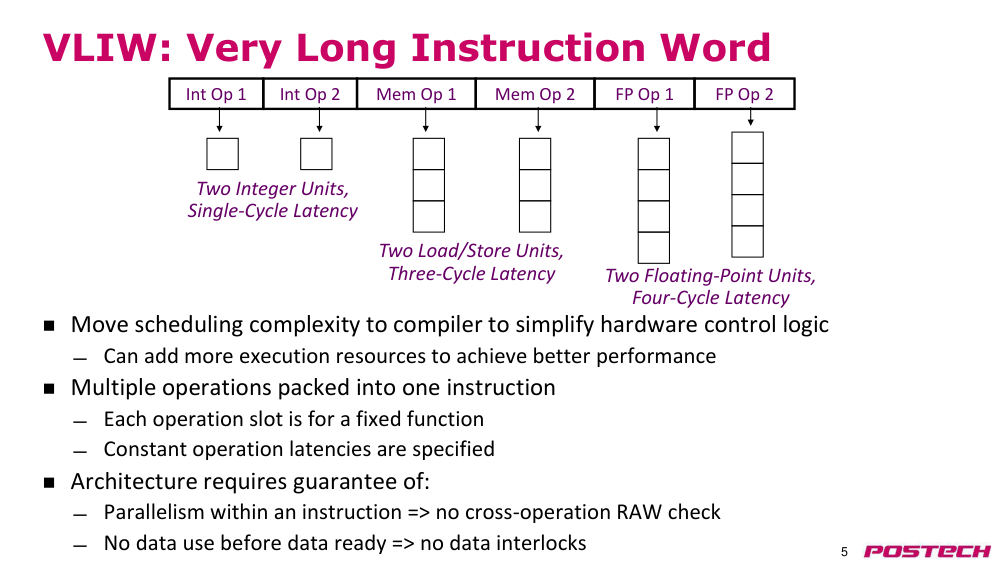
상황·문제지난 시간 내용 요약. VLIW 는 compiler 가 독립 연산을 찾아 한 very long instruction word 에 담는 구조.
원인hardware 는 word 내 연산 간 dependence check 를 하지 않아 복잡도가 낮다.
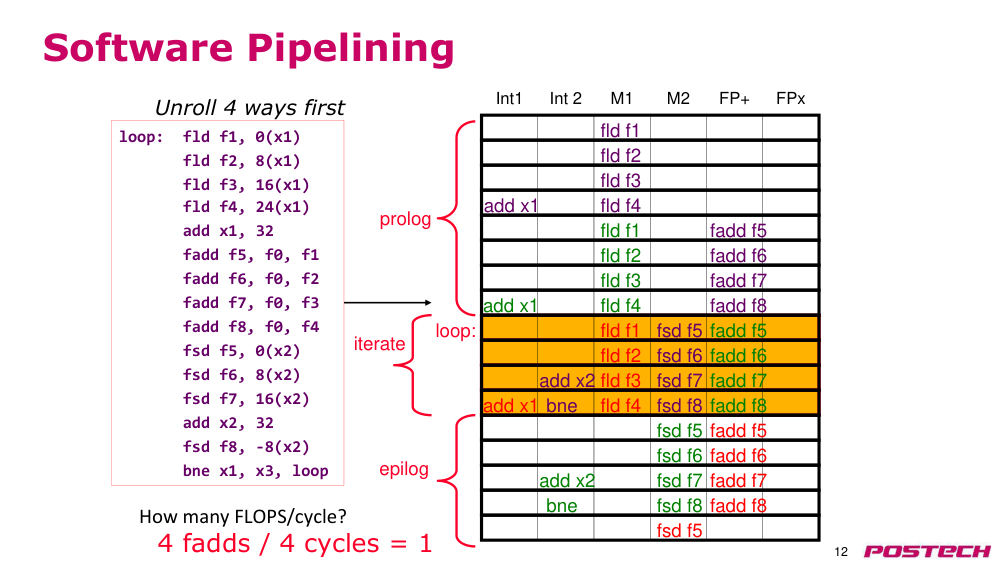
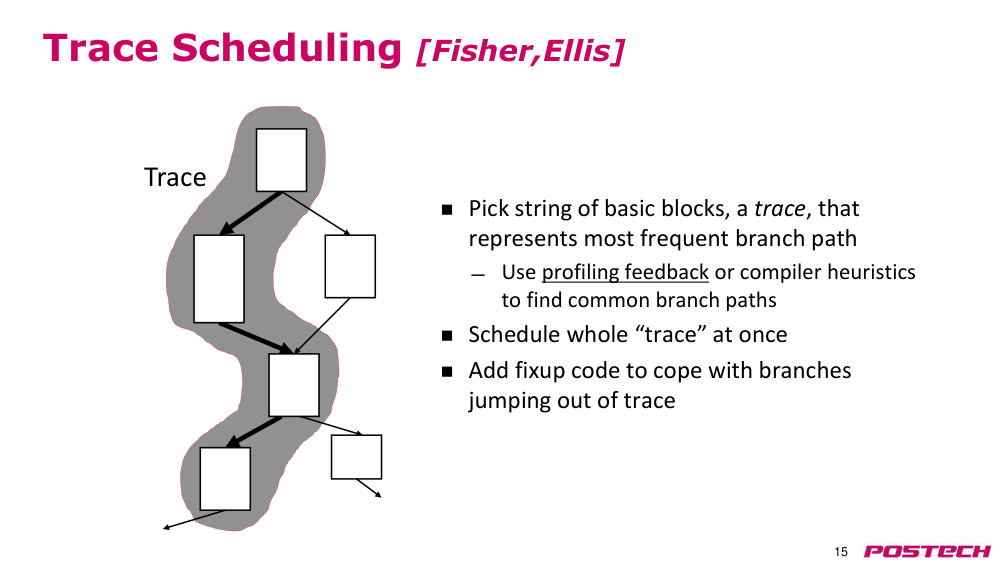
해결loop unrolling·software pipelining 으로 독립 연산을 늘리고, basic block 을 넘는 control flow 는 profiling 기반 trace 로 묶었다.
- 슬라이드 p5→p15 를 빠르게 넘기며 복습
- 12강은 p16 에서 끊겼고 이번 강의가 p16 부터 설명
2.1.r.1Very long instruction word — Wikipedia ↗ · VLIW 개념·역사, code size·object-code compatibility 문제
2.22:20–7:01Classic VLIW 의 문제점
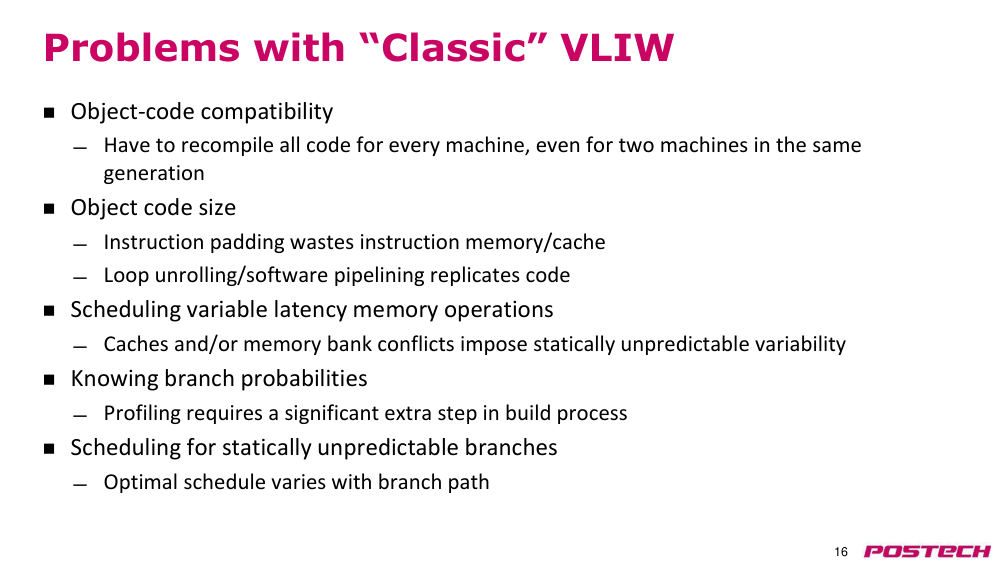
상황·문제fixed instruction format 을 가정한 classic VLIW 의 한계.
원인pipeline width 가 다르면 format 이 호환되지 않아 같은 세대 machine 사이에도 재컴파일. NOP padding·unroll·SWP 로 code size 증가. cache miss·bank conflict 로 memory latency 를 정적으로 모름. branch 확률은 profiling 이 필요하고 일부 branch 는 예측 불가.
해결compiler 가 예측한 실행 흐름이 실제로 실현되지 않아 suboptimal code 가 나온다. 이후 슬라이드들이 이를 완화하는 제안.
- object-code compatibility 문제
- instruction padding 이 I-memory·I-cache 낭비
- variable latency memory, branch probability 추정 부담
2.2.r.1Very long instruction word — Wikipedia ↗ · VLIW 개념·역사, code size·object-code compatibility 문제
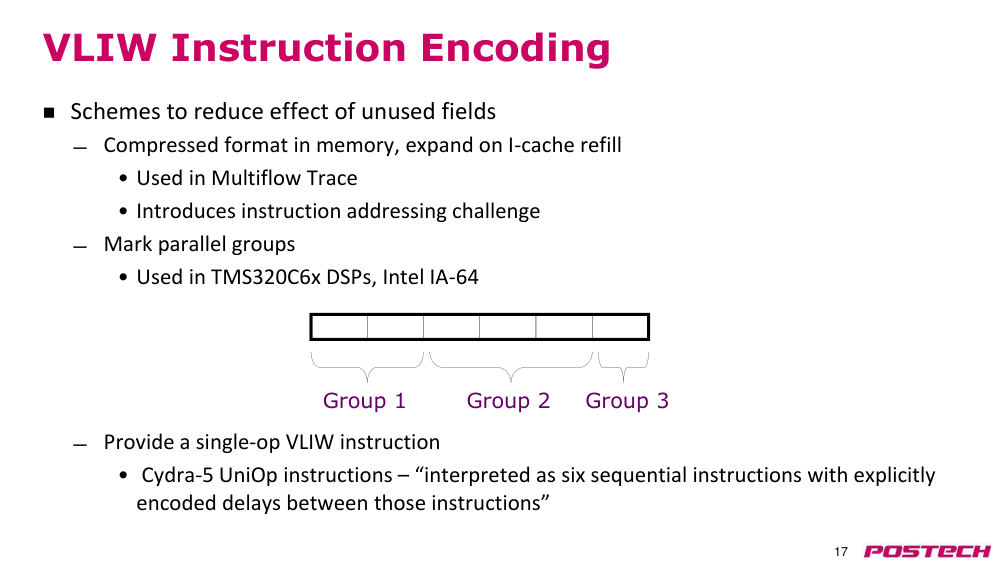
2.37:01–11:44VLIW instruction encoding 개선: 압축, parallel group, UniOp
상황·문제unused field(NOP) 의 영향과 호환성 문제를 줄이려는 제안들.
원인고정 폭 word 를 채우지 못하면 NOP 이 들어가고, 폭이 machine 마다 다르면 호환되지 않는다.
해결(1) memory 에 compressed format, I-cache refill 때 expand(Multiflow Trace) — 가변 길이로 branch offset·정렬 안 된 fetch 문제. (2) parallel group 표시: group 내는 독립, group 간은 의존 가능, width 가 다른 machine 에서도 같은 code(IA-64). (3) Cydra-5 UniOp: word 안 6개 연산을 순차로 해석, 명시적 delay, mode 전환.
- group 크기가 가변이라 호환성 문제를 피함
- UniOp 모드와 multi-op 모드를 병렬성에 따라 전환
2.411:44–16:50Intel Itanium, EPIC IA-64 와 Poulson
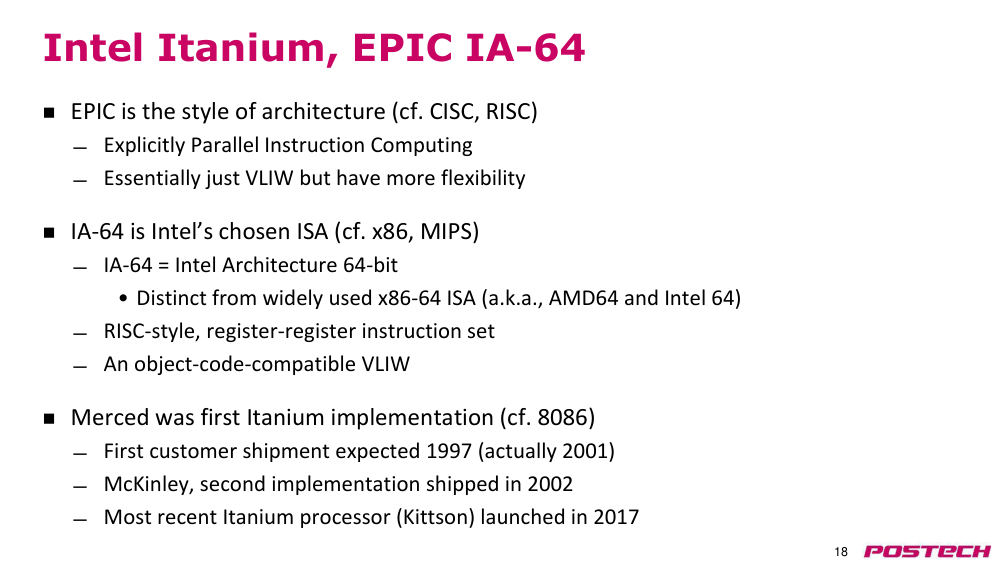
상황·문제Intel·HP 가 2000년대 초 더 유연한 VLIW 를 차세대 64-bit architecture 로 제안.
원인VLIW 라는 이름은 오래됐고 성공하지 못해, style 이름을 EPIC(Explicitly Parallel Instruction Computing) 으로 구분.
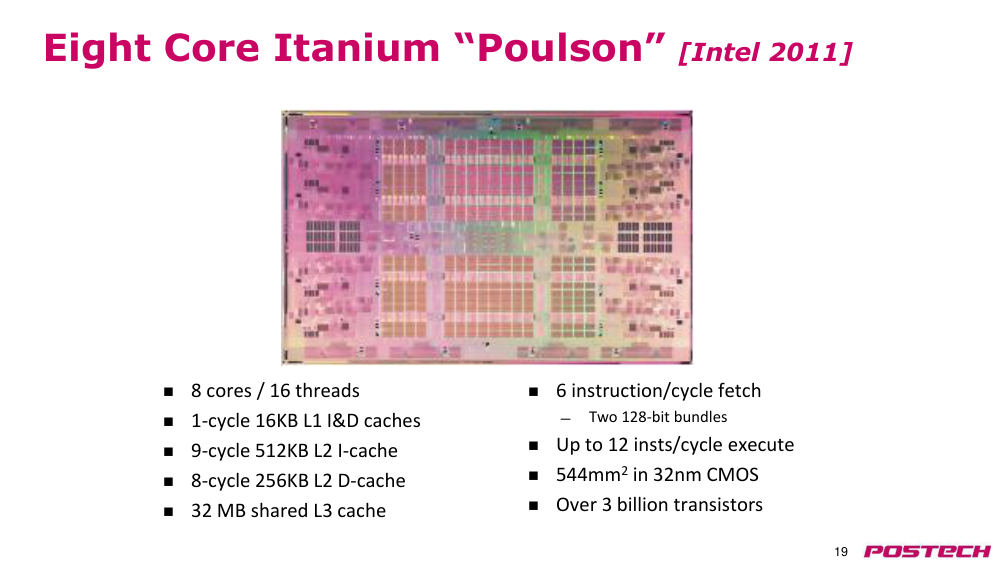
해결IA-64 = RISC-style register-register ISA, object-code compatible VLIW. x86-64(AMD64/Intel 64) 와는 별개. Merced 1997 예정→2001 출시, McKinley 2002, Poulson(32nm, 8 core, 2-way multithreading) 2011 발표.
- IA-64 ≠ x86-64: x86-64 는 32-bit CISC x86 의 확장
- Poulson: cycle 당 6 instruction fetch(128-bit bundle 2개), 최대 12 insts/cycle 실행
2.4.r.1Explicitly parallel instruction computing — Wikipedia ↗ · EPIC 의 bundle·speculative load·check load·rotating register file 개요
2.4.r.2Itanium — Wikipedia ↗ · Merced(2001)·McKinley(2002)·Poulson·Kittson(2017), 2019 단종 발표, 판매 예측 하향
2.516:50–18:32IA-64 instruction format 과 register
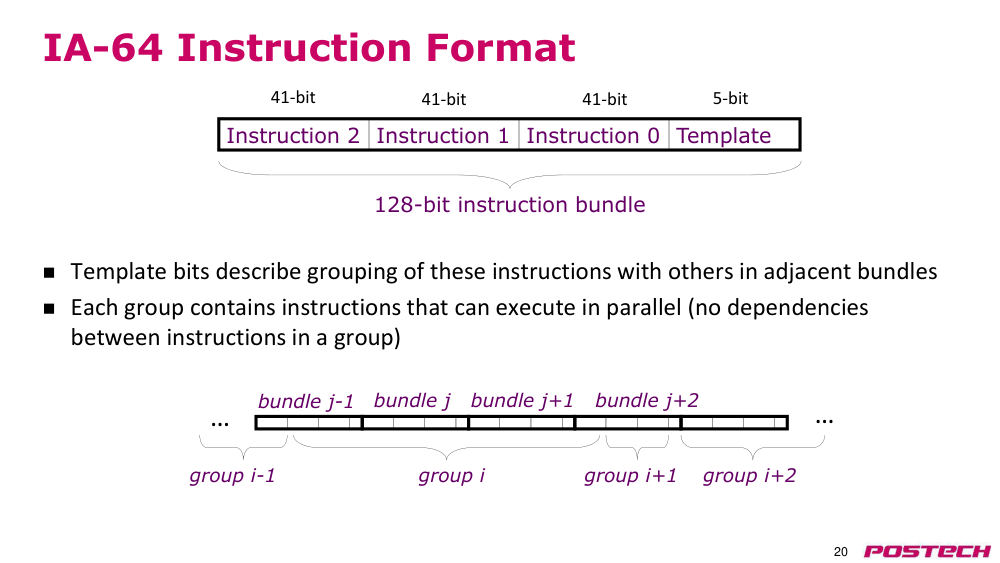
상황·문제128-bit bundle 에 41-bit instruction 3개 + 5-bit template.
원인group 경계를 표시해야 hardware 가 group 간 의존만 보고 동적으로 schedule 할 수 있다.
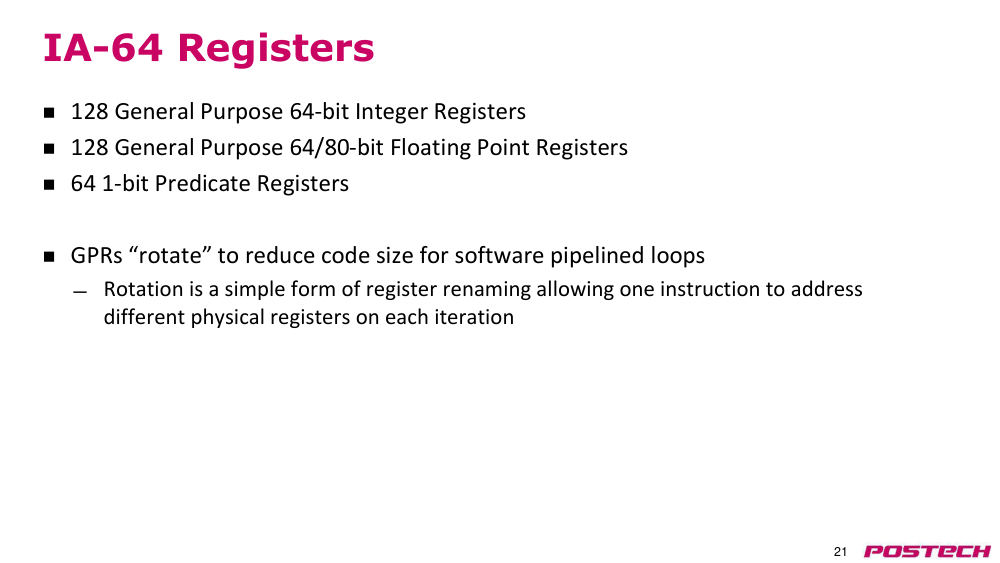
해결template bit 가 인접 bundle 과의 group 경계를 지정. 128 개 64-bit integer GPR, 128 개 64/80-bit FP register, 64 개 1-bit predicate register.
- group 내 instruction 은 의존 없음 → 병렬 실행
- group 은 bundle 경계를 넘을 수 있음
2.5.r.1IA-64 — Wikipedia ↗ · 128-bit bundle(41-bit ×3 + 5-bit template), 128 GR/FR, 64 predicate, speculation
2.618:32–29:44Rotating register file
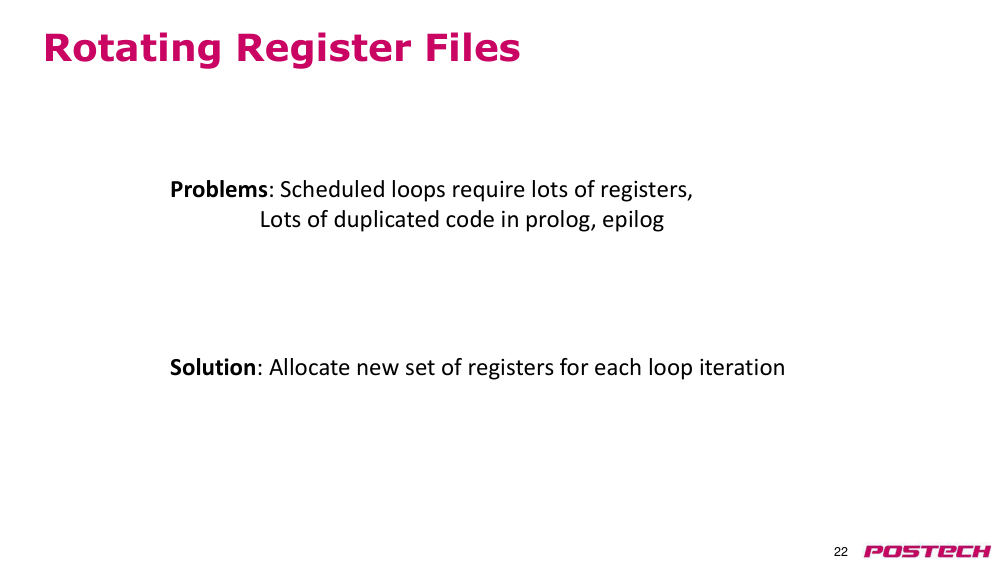
상황·문제unroll·SWP 로 한 iteration 에 독립 연산을 많이 담으면 register 가 많이 필요하고 prolog/epilog 에 중복 code.
원인architectural register 를 늘리면 register specifier bit 가 늘어 code size 가 커진다.
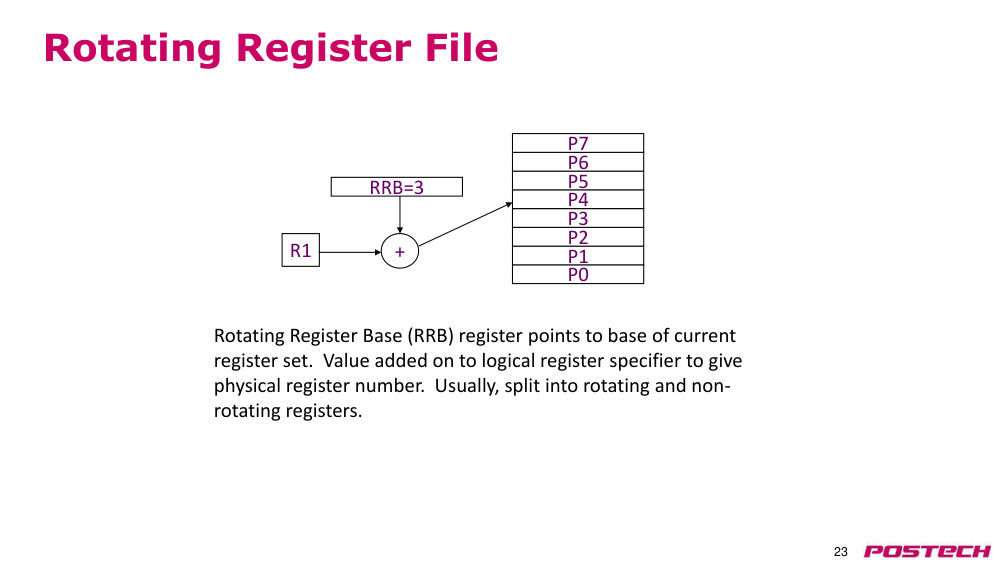
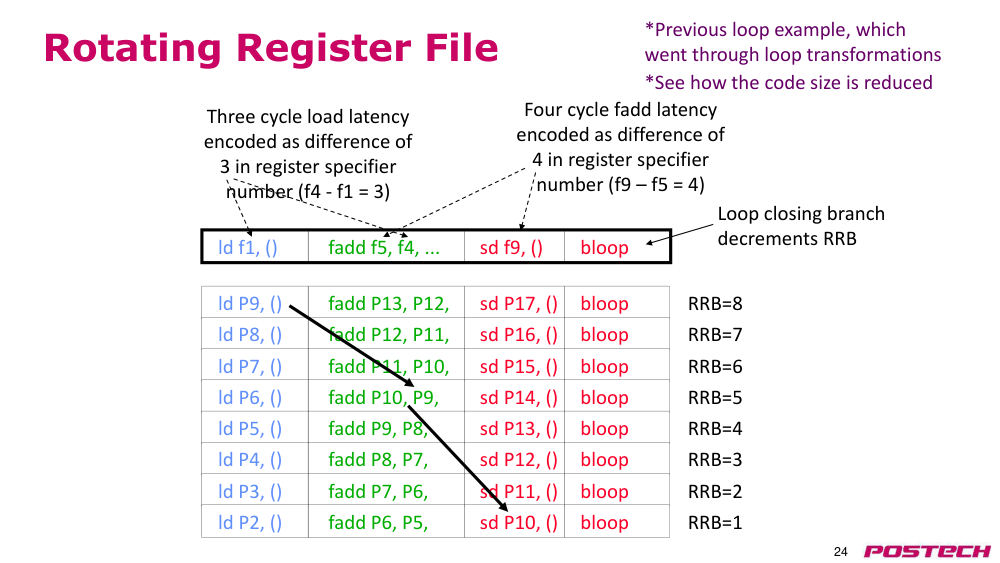
해결RRB(rotating register base) 를 logical 번호에 더해 physical register 를 정함(R1+RRB 3 → P4). loop 마다 bloop 가 RRB 를 감소시켜 같은 instruction 이 iteration 마다 다른 physical register 사용.
- ld f1 / fadd f5,f4 / sd f9 / bloop 한 줄 loop, RRB=8 에서 시작
- load 3-cycle latency 는 f4-f1=3, fadd 4-cycle 은 f9-f5=4 로 encode
- 강의 중 software pipelining 슬라이드(p12)로 잠시 돌아가 대응 관계 설명
2.6.r.1Software pipelining — Wikipedia ↗ · prologue/epilogue, IA-64 rotating register 로 unroll·rename 없이 SWP
2.6.r.2IA-64 — Wikipedia ↗ · 128-bit bundle(41-bit ×3 + 5-bit template), 128 GR/FR, 64 predicate, speculation
2.729:44–43:05IA-64 predicated execution
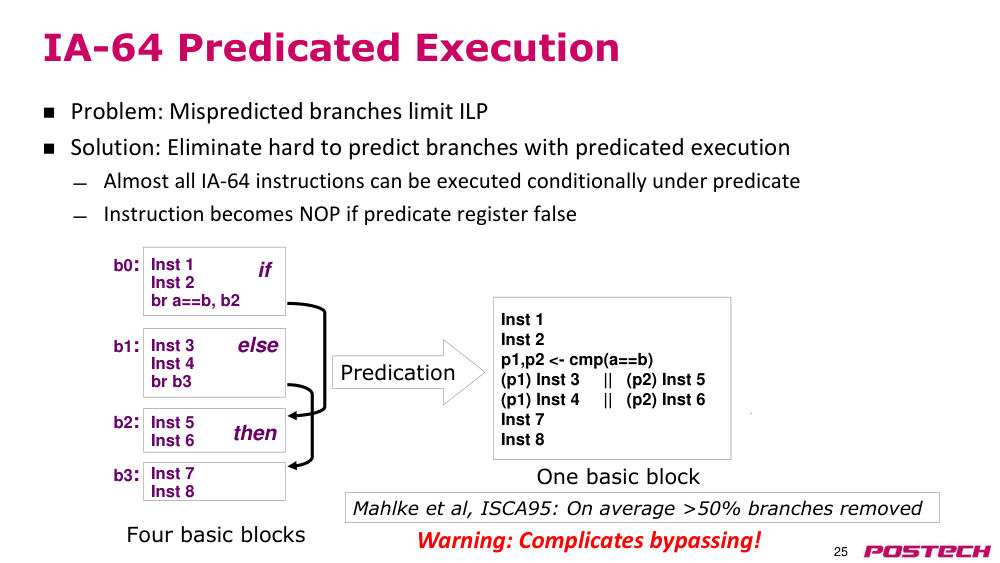
상황·문제mispredicted branch 가 ILP 를 제한. 수십 개 in-flight instruction 을 flush 해야 한다.
원인예측이 어려운 branch 는 flush 비용이 크다.
해결compare 가 predicate p1,p2 를 set, 이후 instruction 은 predicate 가 false 면 NOP(bubble) 이 되어 branch 제거. IA-64 는 거의 모든 instruction 이 predicate 하에 조건 실행. 평균 50% 이상 branch 제거(Mahlke ISCA95).
- 단점: 양쪽 경로를 모두 실행해 execution unit 낭비 → 예측 정확도가 높으면 branch 가 낫고, compiler 가 판단
- bypassing 복잡: predicate 값이 나올 때까지 bypass 여부를 결정 못 함
- Q&A: NOP 이 된다는 것은 store 가 아니라 in-flight instruction 을 무효화하는 것
2.7.r.1Predication (computer architecture) — Wikipedia ↗ · branch 를 predicate 조건 실행으로 대체, IA-64 predicate register
2.843:05–48:12IA-64 control speculation 과 data speculation
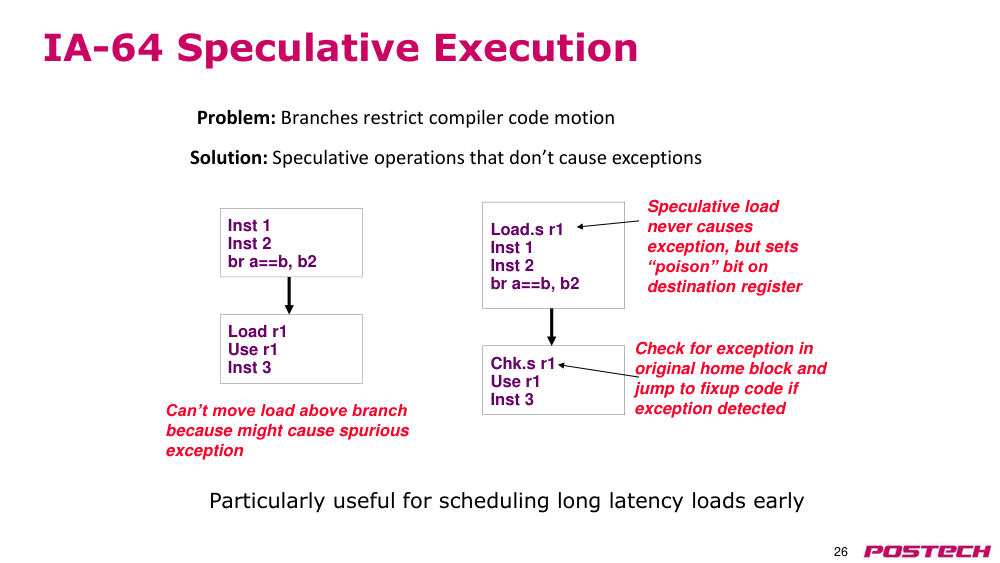
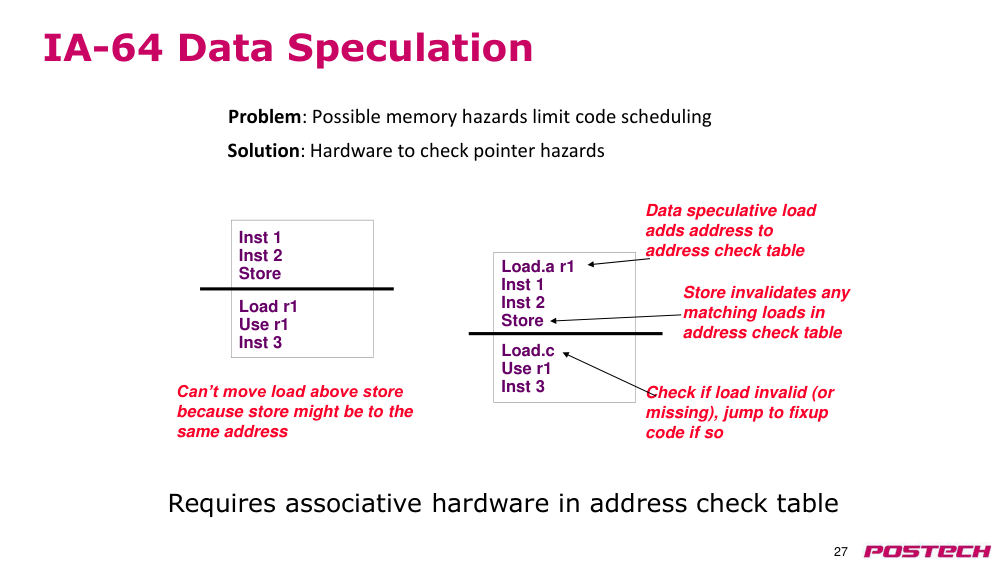
상황·문제branch 와 memory hazard 가 compiler 의 code motion 을 제한한다.
원인load 를 branch 위로 올리면 page fault 같은 spurious exception, store 위로 올리면 같은 주소일 수 있음.
해결Load.s: exception 대신 destination 에 poison bit, 원위치 Chk.s 가 확인해 fixup code 로. Load.a: 주소를 address check table 에 등록, 이후 store 가 일치 load 를 무효화, Load.c 가 확인해 fixup.
- 목적: cache miss 가능한 long-latency load 를 일찍 실행
- 대가: associative 비교 hardware 와 fixup code 를 만드는 compiler 복잡도
2.8.r.1Explicitly parallel instruction computing — Wikipedia ↗ · EPIC 의 bundle·speculative load·check load·rotating register file 개요
2.8.r.2IA-64 — Wikipedia ↗ · 128-bit bundle(41-bit ×3 + 5-bit template), 128 GR/FR, 64 predicate, speculation
2.948:12–51:17Static scheduling 의 한계
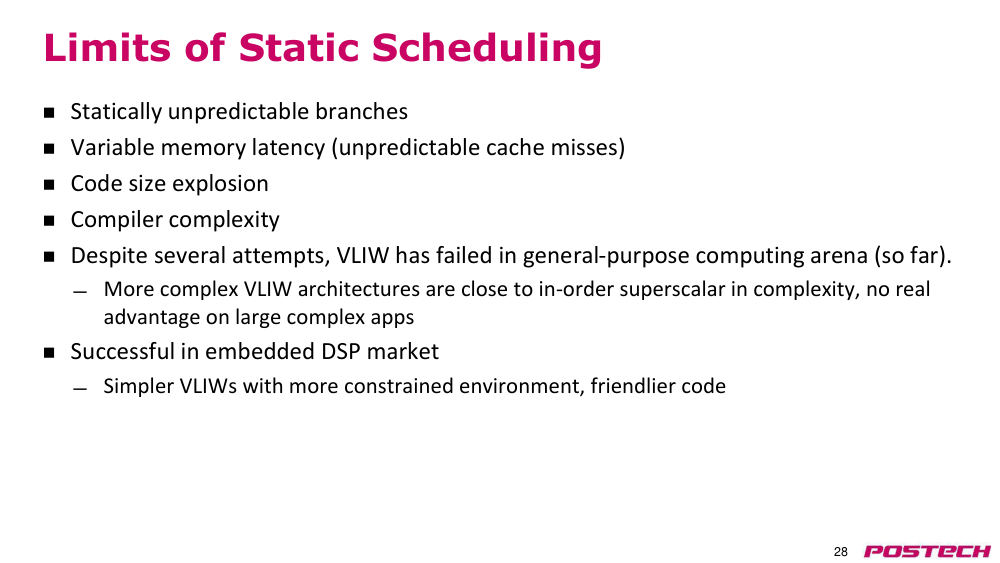
상황·문제여러 보완에도 static scheduling 에는 근본 한계가 있다.
원인예측 불가 branch(predication 도 단점), cache hit/miss 에 따른 variable latency, code size explosion, compiler complexity.
해결범용 computing 에서 VLIW 는 실패: 보완을 다 넣으면 in-order superscalar 와 복잡도가 비슷하고 이득은 작다. 실행 code 가 제한적인 embedded DSP 에서는 단순한 VLIW 로 성공.
- embedded 에서는 compiler 가 program 동작을 더 확신할 수 있음
2.9.r.1Very long instruction word — Wikipedia ↗ · VLIW 개념·역사, code size·object-code compatibility 문제
2.1051:17–55:52Itanium 2 성능과 Itanium 의 종말
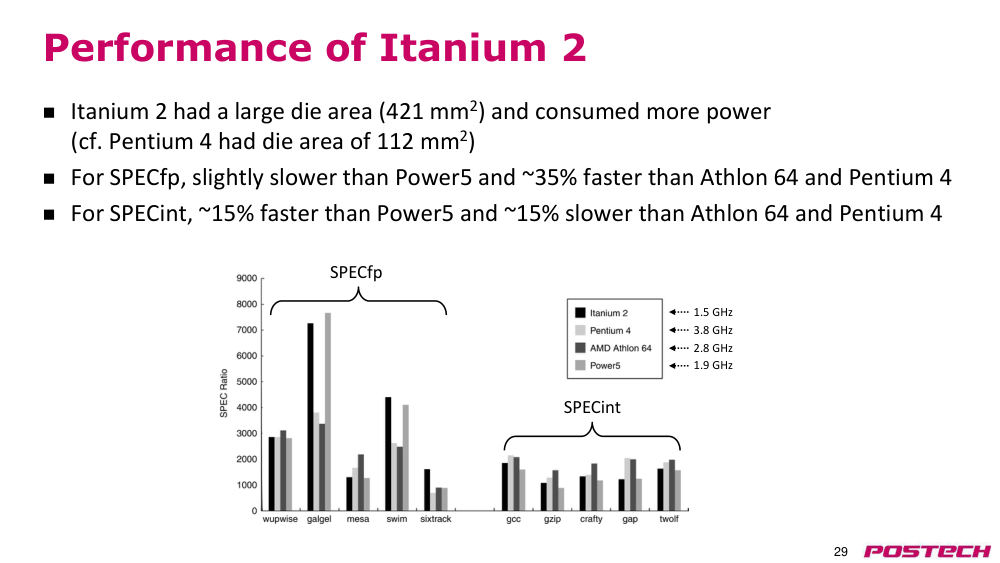
상황·문제Itanium 2 를 Pentium 4·Athlon 64·Power5 와 SPEC 으로 비교.
원인die 421 mm²(Pentium 4 의 3배 이상), 전력도 더 소비.
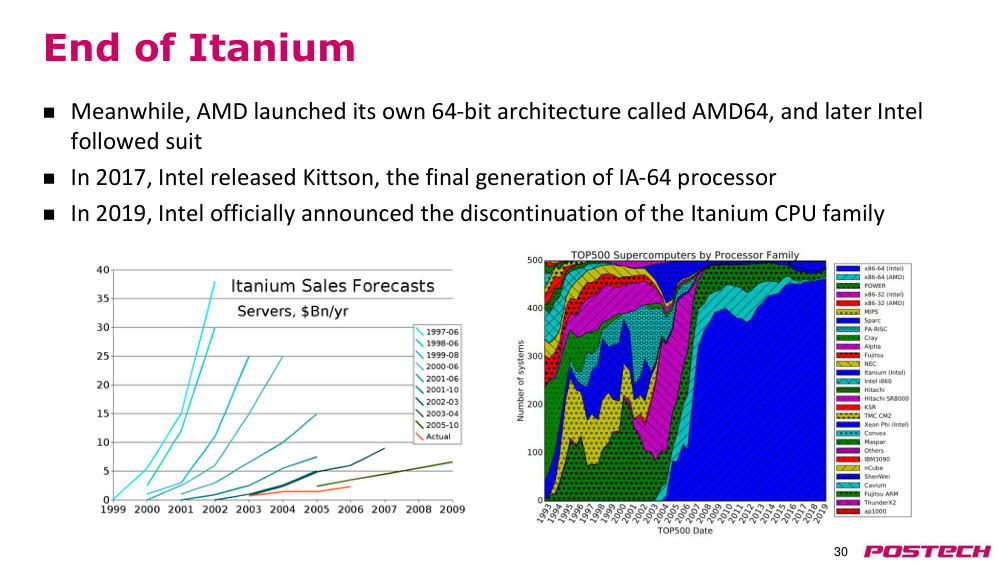
해결SPECint 에서 Power5 보다 ~15% 빠르나 Athlon 64·Pentium 4 보다 느림 → 면적·전력 대비 좋지 않은 결과. 판매 예측이 계속 하향, TOP500 점유도 빠르게 잃음. HP high-end 때문에 생산 지속, 2017 Kittson 이 마지막, 2019 단종 발표.
- SPECfp: slide 는 Power5 보다 약간 느림, x86 두 개보다 ~35% 빠름
- 강의는 floating point 중심 application 이 아니면 전통 architecture 가 더 효율적이라 언급
2.10.r.1Itanium — Wikipedia ↗ · Merced(2001)·McKinley(2002)·Poulson·Kittson(2017), 2019 단종 발표, 판매 예측 하향
2.1155:52–56:20마무리: VLIW 파트 종료, 질문
상황·문제VLIW 파트 종료, 질문 받음. 권장 읽기는 교재 3.7, Appendix H.
2.11.r.1Computer Architecture: A Quantitative Approach, 6th ed. — Elsevier ↗ · 교재. 권장 읽기 3.7·Appendix H(VLIW/EPIC)
3핵심 개념
3.1object-code compatibility(목적 코드 호환성)
classic VLIW 는 pipeline width 가 다르면 같은 세대 machine 에도 재컴파일해야 한다.
3.1.r.1Very long instruction word — Wikipedia ↗ · VLIW 개념·역사, code size·object-code compatibility 문제
3.2parallel group(병렬 그룹)
group 내 instruction 은 독립, group 간 의존 가능. 크기 가변이라 width 가 다른 machine 에서도 같은 code.
3.2.r.1IA-64 — Wikipedia ↗ · 128-bit bundle(41-bit ×3 + 5-bit template), 128 GR/FR, 64 predicate, speculation
3.3EPIC(Explicitly Parallel Instruction Computing)
Intel·HP 의 architecture style, 사실상 더 유연한 VLIW. ISA 는 IA-64.
3.3.r.1Explicitly parallel instruction computing — Wikipedia ↗ · EPIC 의 bundle·speculative load·check load·rotating register file 개요
3.4template bits(템플릿 비트)
128-bit bundle 의 5-bit, 인접 bundle 과의 group 경계를 표시.
3.4.r.1IA-64 — Wikipedia ↗ · 128-bit bundle(41-bit ×3 + 5-bit template), 128 GR/FR, 64 predicate, speculation
3.5rotating register file(회전 레지스터 파일)
RRB 를 logical register 번호에 더해 physical register 결정. bloop 가 RRB 를 감소.
3.5.r.1Software pipelining — Wikipedia ↗ · prologue/epilogue, IA-64 rotating register 로 unroll·rename 없이 SWP
3.6predicated execution(조건부 실행)
predicate 가 false 인 instruction 은 NOP 이 되어 branch 를 제거. 양쪽 경로 실행으로 execution unit 낭비.
3.6.r.1Predication (computer architecture) — Wikipedia ↗ · branch 를 predicate 조건 실행으로 대체, IA-64 predicate register
3.7poison bit(포이즌 비트)
Load.s 가 exception 대신 destination register 에 set, Chk.s 가 검사해 fixup code 로 jump.
3.7.r.1IA-64 — Wikipedia ↗ · 128-bit bundle(41-bit ×3 + 5-bit template), 128 GR/FR, 64 predicate, speculation
3.8address check table(주소 검사 테이블)
Load.a 가 주소를 등록하고 store 가 일치 항목을 무효화, Load.c 가 확인. associative hardware 필요.
3.8.r.1IA-64 — Wikipedia ↗ · 128-bit bundle(41-bit ×3 + 5-bit template), 128 GR/FR, 64 predicate, speculation
4스스로 확인
4.1classic VLIW 에서 같은 세대 machine 사이에도 재컴파일이 필요한 이유는?
답
fixed instruction format 이 pipeline width 에 묶여 width 가 다르면 호환되지 않기 때문.
4.2rotating register file 이 register specifier 를 늘리지 않고 register 를 더 쓰게 하는 방법은?
답
RRB 를 logical 번호에 더해 physical register 를 정하고 bloop 가 iteration 마다 RRB 를 바꾼다.
4.3predication 이 branch 보다 불리한 경우는?
답
branch 예측 정확도가 높을 때. 양쪽 경로를 모두 실행해 execution unit 을 낭비하기 때문.
4.4Load.s 와 Load.a 가 각각 해결하는 문제는?
답
Load.s 는 branch 위로 올린 load 의 spurious exception, Load.a 는 store 위로 올린 load 의 memory 주소 충돌.
4.5IA-64 와 x86-64 의 관계는?
답
별개 ISA. x86-64(AMD64/Intel 64)는 32-bit CISC x86 의 확장, IA-64 는 RISC-style EPIC.
5참고 자료
5.2Explicitly parallel instruction computing — Wikipedia ↗ · EPIC 의 bundle·speculative load·check load·rotating register file 개요
5.3IA-64 — Wikipedia ↗ · 128-bit bundle(41-bit ×3 + 5-bit template), 128 GR/FR, 64 predicate, speculation
5.5Predication (computer architecture) — Wikipedia ↗ · branch 를 predicate 조건 실행으로 대체, IA-64 predicate register
5.6Software pipelining — Wikipedia ↗ · prologue/epilogue, IA-64 rotating register 로 unroll·rename 없이 SWP
5.7Computer Architecture: A Quantitative Approach, 6th ed. — Elsevier ↗ · 교재. 권장 읽기 3.7·Appendix H(VLIW/EPIC)