Lec 7 part2 & Lec 8 · physical register 관리, superscalar rename, branch prediction
정밀 정리 · 검증 2026-09-24 01:49
1개요
1.1unified physical register file 예제로 rename·commit 시 LPRd 반환과 free list 순환을 따라감.
1.2오예측 시 rename table 복구(R10K 역순 unrenaming, Alpha 21264 snapshot), ROB 와 별도 issue window 의 크기 관계.
1.3superscalar rename 은 같은 cycle 내 RAW 비교·bypass 가 필요해 비용이 super-linear.
1.4Lec 8: control-flow penalty, static/1-bit/2-bit/two-level predictor, BHT 한계와 BTB (p20 이후 다음 강의).
2섹션별 정리 상황·문제 → 원인 → 해결
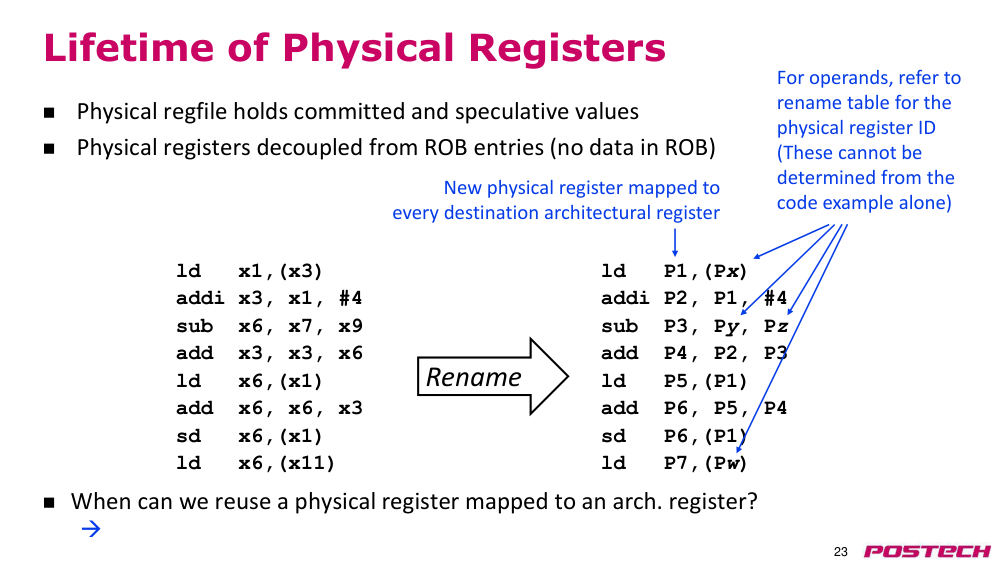
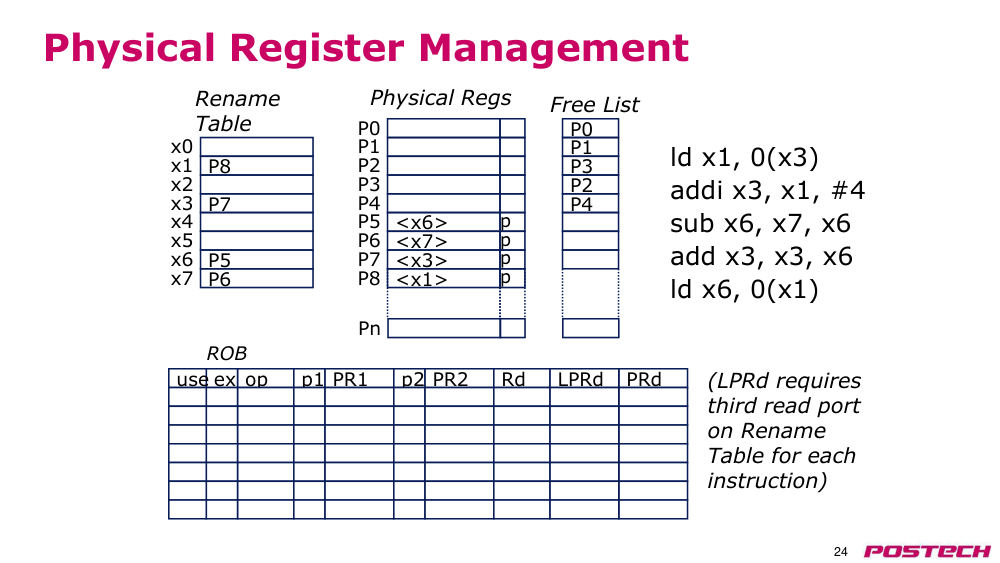
2.11:28–5:09Unified physical register file 의 rename 구조 복습
상황·문제지난 강의의 unified physical register file 방식: architectural register 를 모두 physical register 로 바꾸고 PRF 하나가 FU 에 operand 공급.
원인ROB 에는 data 가 없고 PR1·PR2·PRd·LPRd 같은 physical register 번호만 기록한다.
해결rename table(x1→P8 등)·free list·ROB 필드를 예제로 설명. LPRd = 이 destination 이 전에 매핑돼 있던 physical register.
- PRF 가 모든 operand 의 단일 source
- free list = 현재 쓰이지 않는 physical register 목록
- LPRd(last physical destination register) 는 이전 mapping 기록용
2.1.r.1MIT 6.5900 Quiz 1 handout — Physical Register File Design ↗ · rename table·physical register file·free list·ROB(tag 만 보관) 구성
2.1.r.2Register renaming — Wikipedia ↗ · free tag FIFO 에서 새 tag 배정, graduation 때 이전 tag 를 free queue 로 반환
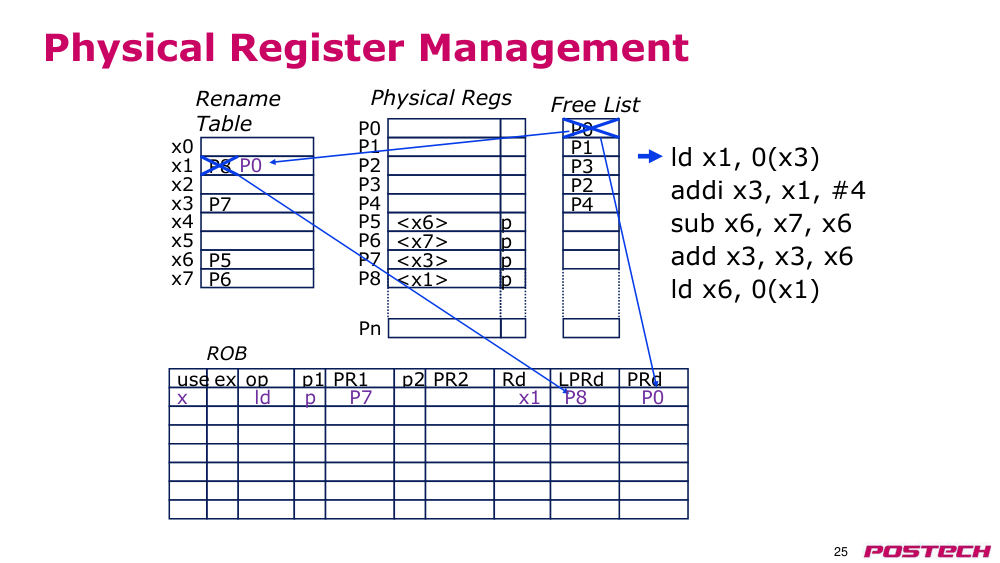
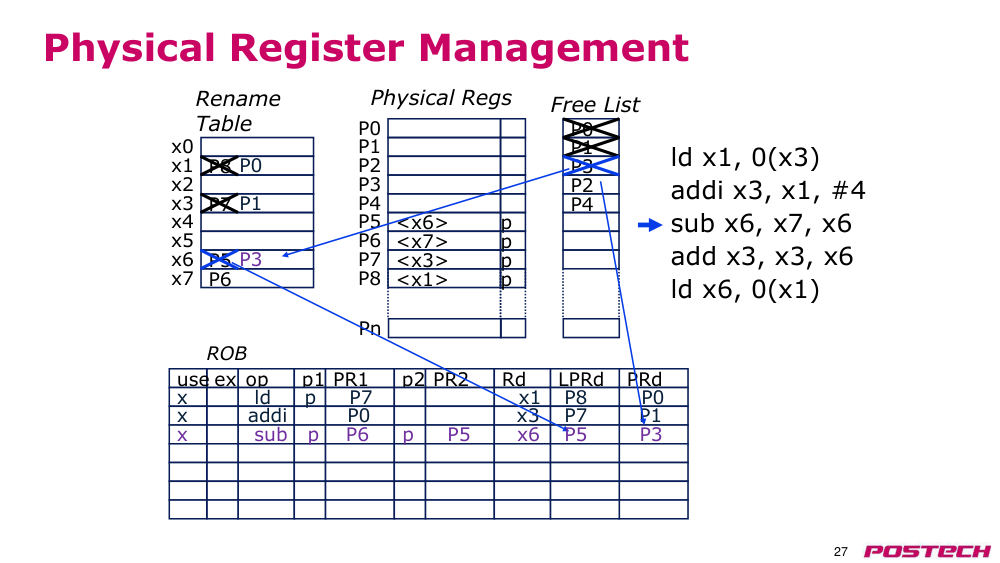
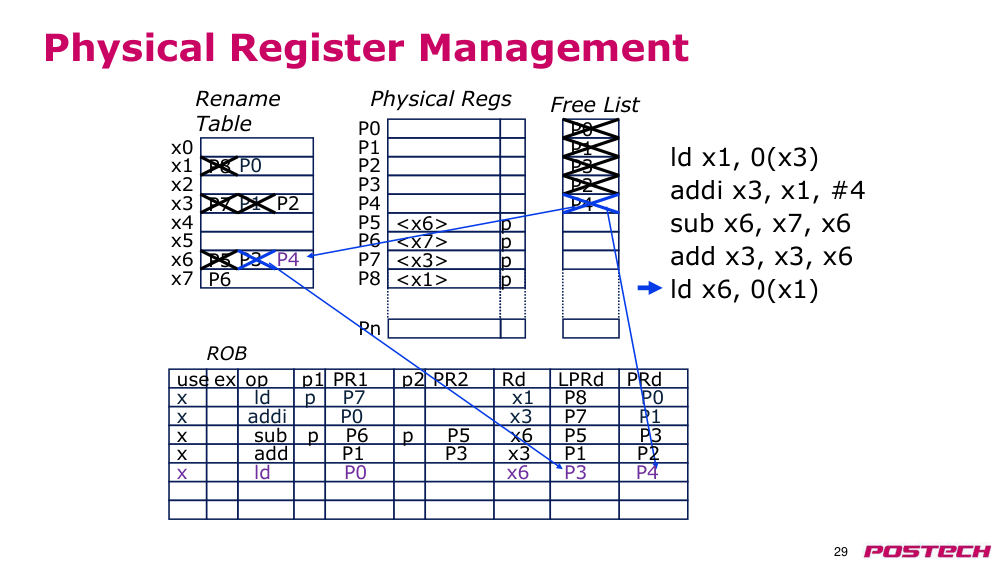
2.25:09–12:20예제: 다섯 명령어 rename (P0·P1·P3·P2·P4 배정)
상황·문제모든 destination 에 새 physical register 를 배정해 WAW·WAR hazard 를 없앤다.
원인source 는 rename table 을 조회만 하고, destination 은 이전 mapping 을 LPRd 에 적은 뒤 free list 맨 앞 register 로 교체.
해결ld x1→P0(LPRd P8), addi x3→P1(LPRd P7, src P0 미존재), sub x6→P3(src 는 옛 P5), add x3→P2(src P1), ld x6→P4.
- sub x6,x7,x6: source x6 은 새 배정 이전 mapping(P5)을 읽는다
- 값이 없는 source(P0)는 present bit 없이 번호만 기록
- 배정된 register 는 free list 에서 제거
2.2.r.1MIT 6.5900 Quiz 1 handout — Physical Register File Design ↗ · rename table·physical register file·free list·ROB(tag 만 보관) 구성
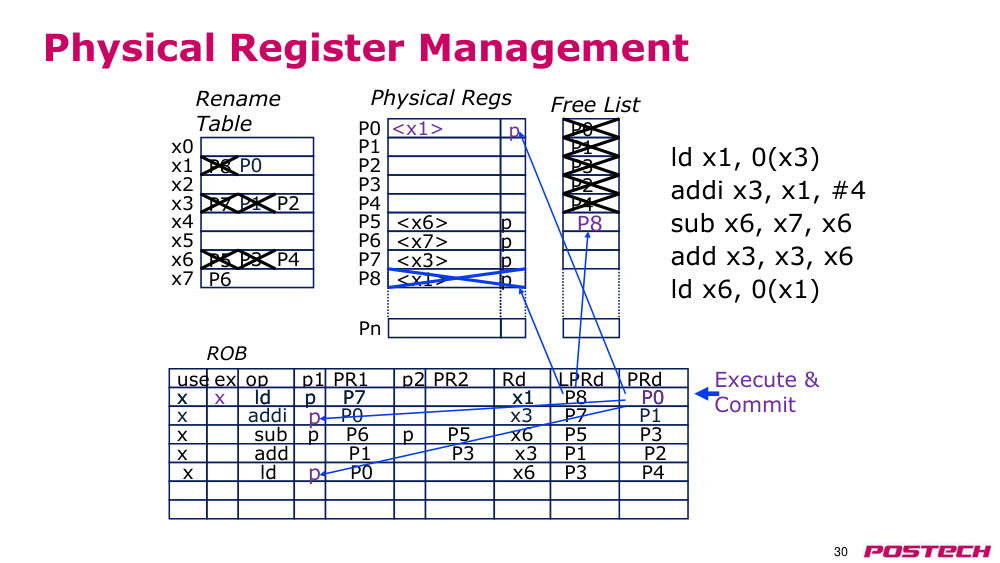
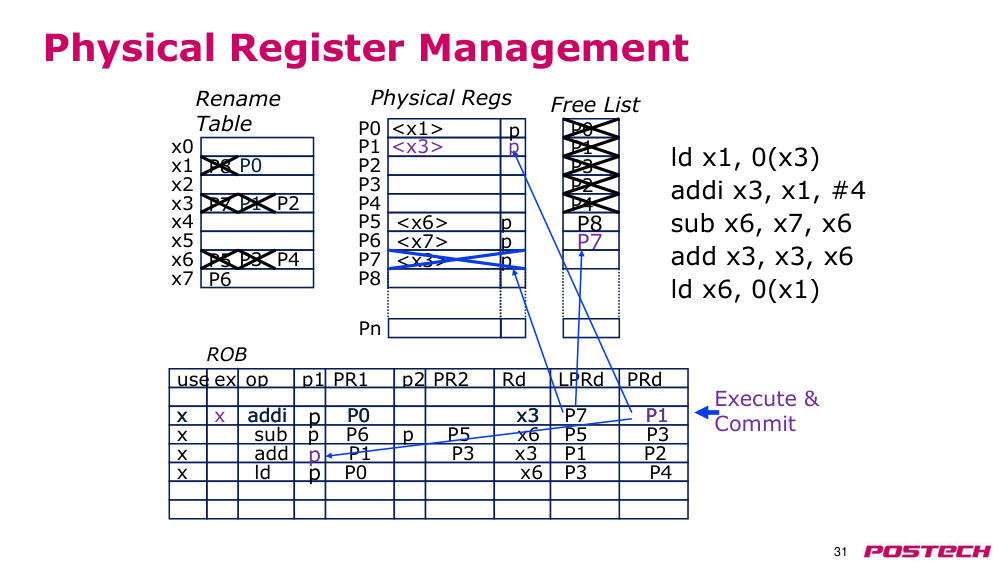
2.312:20–16:16Execute & commit: 옛 physical register 해제
상황·문제physical register 는 유한하므로 언제 재사용할지 정해야 한다.
원인명령어가 commit 되면 그 이전 명령어 중 옛 mapping(LPRd)을 쓰는 것이 더 없음이 보장된다.
해결ld x1 commit → P0 에 값·대기 entry present bit set, LPRd P8 을 free list 로. addi commit → P1 기록, P7 반환.
- 결과 기록 시 ROB 의 대기 entry 들 present bit 갱신
- 해제 대상은 PRd 가 아니라 LPRd
- PRF 가 operand 의 단일 source 로 동작
2.3.r.1Register renaming — Wikipedia ↗ · free tag FIFO 에서 새 tag 배정, graduation 때 이전 tag 를 free queue 로 반환
2.3.r.2Yeager, The MIPS R10000 Superscalar Microprocessor (IEEE Micro 1996) ↗ · active list·free list·map table, exception 시 역순 unmapping, branch mask
2.416:16–19:21잘못된 speculation 후 rename table 복구
상황·문제speculative OoO 머신은 예측이 틀리면 rename table 을 올바른 상태로 되돌려야 한다.
원인PRF 의 옛 값은 남아 있으나, speculative 명령어가 만든 mapping 과 할당한 physical register 는 되돌려야 한다.
해결MIPS R10K: ROB 를 역순으로 돌며 PRd/LPRd 로 unrenaming. Alpha 21264: snapshot 80개 중 하나를 한 cycle 에 flash copy.
- R10K = 역순 unrenaming
- Alpha 21264 = snapshot 총 80개, 1 cycle 복사
2.4.r.1Yeager, The MIPS R10000 Superscalar Microprocessor (IEEE Micro 1996) ↗ · active list·free list·map table, exception 시 역순 unmapping, branch mask
2.4.r.2Alpha 21264 — Wikipedia ↗ · 최대 80개 in-flight 명령어, 40 rename register, local/global/choice tournament predictor
2.519:21–29:05ROB 와 별도 issue window, 크기 비율
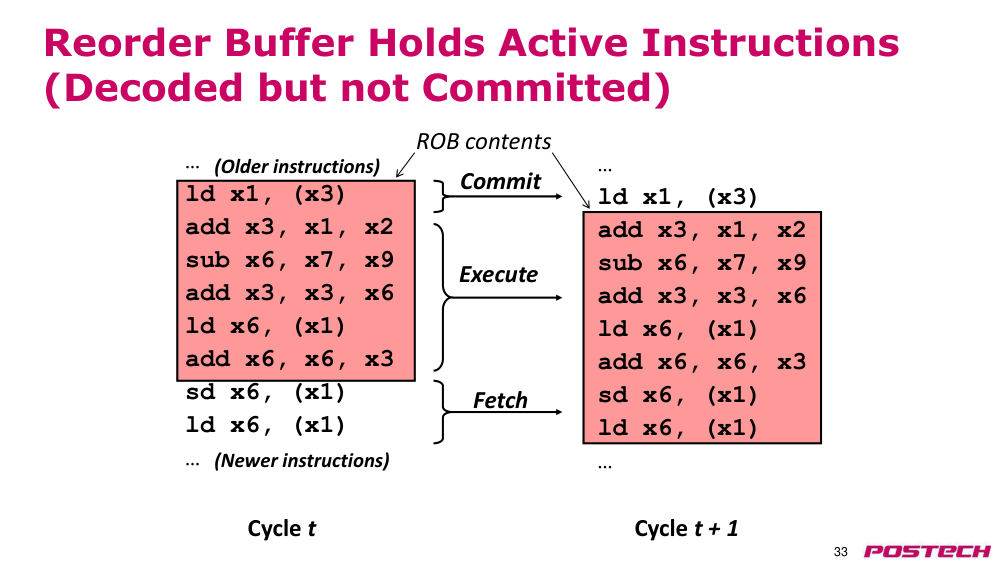
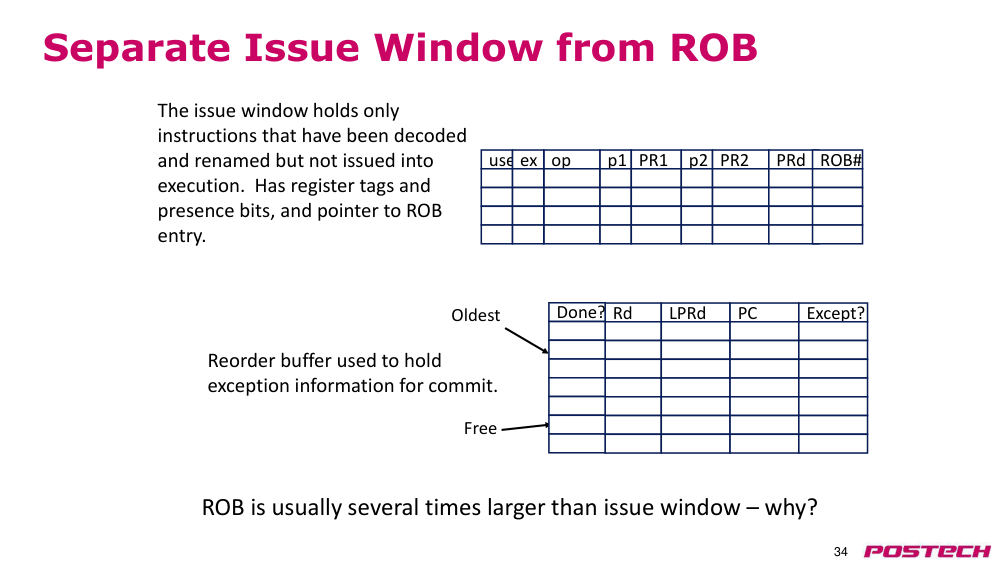
상황·문제ROB 에 모든 active 명령어를 두면 issue 할 명령어를 찾을 때 이미 실행된 것까지 탐색해야 한다.
원인issue window 명령어는 ROB 에도 있어야 하므로 ROB 가 조금만 크면 FU 를 지나는 명령어가 ROB 를 채워 dispatch 가 막힌다.
해결decode·rename 된 미-issue 명령어만 issue window 에 두고, ROB 는 issue window 보다 몇 배 크게 설계.
- 별도 issue window 로 탐색 비용 감소
- ROB 가 가득 차면 issue window entry 가 놀고 FU 활용도 저하
- multiply·FP divide 같은 긴 명령어가 ROB 를 오래 점유
2.5.r.1Out-of-order execution — Wikipedia ↗ · dispatch 와 issue, execute 와 graduation 을 queue 로 decouple
2.629:05–36:37Superscalar register renaming
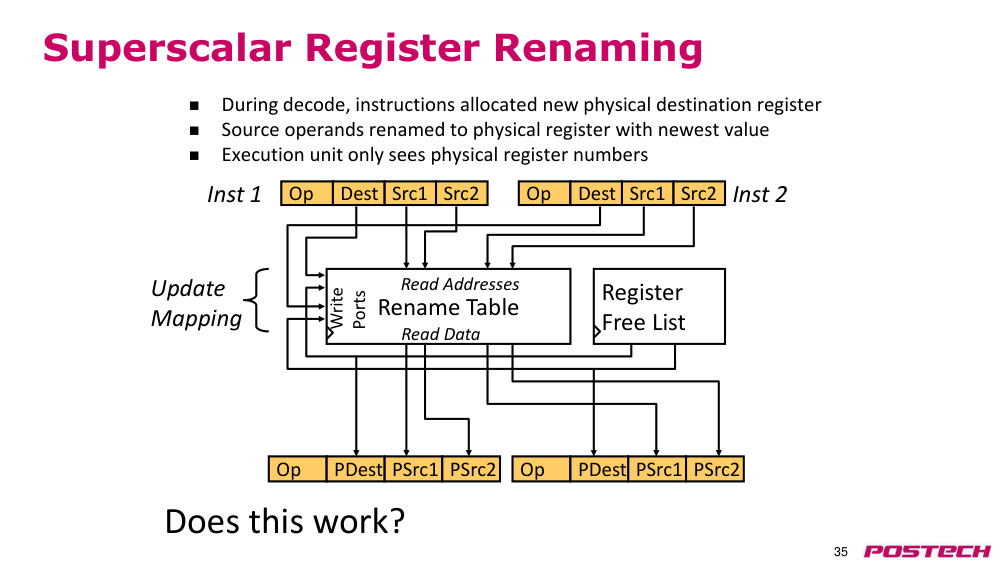
상황·문제issue width 2 면 rename table 의 source port 4개, destination port 2개, PRF port 도 늘어난다.
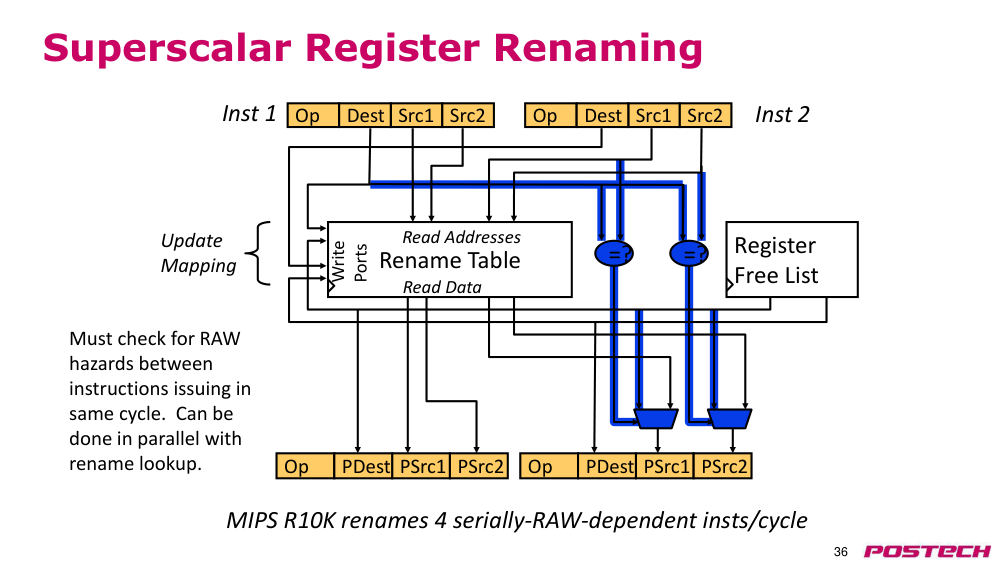
원인port 만 두 배로는 부족: 같은 cycle 의 inst 2 source 가 inst 1 destination 을 가리키면 rename table 에 아직 새 mapping 이 없다.
해결비교기(=?)로 확인해 새 PDest 를 bypass. 이 때문에 issue width 증가에 따라 비용이 super-linear 로 증가.
- MIPS R10K 는 serially RAW-dependent 명령어 4개를 cycle 당 rename
- 최신 프로세서는 cycle 당 최대 8개 decode·rename·issue
2.6.r.1Yeager, The MIPS R10000 Superscalar Microprocessor (IEEE Micro 1996) ↗ · active list·free list·map table, exception 시 역순 unmapping, branch mask
2.736:37–43:16Control-flow penalty 와 branch prediction 의 중요성 (Lec 8 시작)
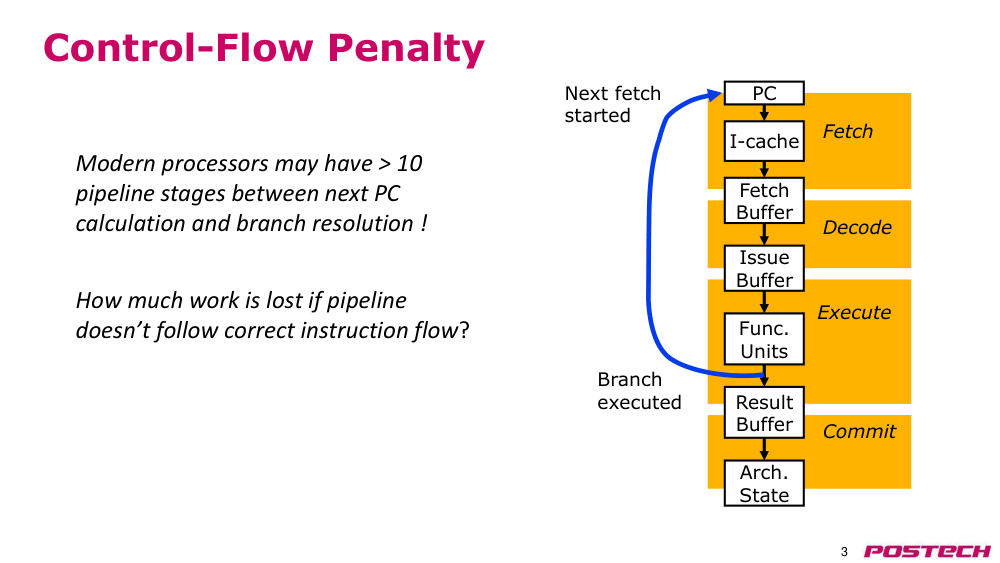
상황·문제고성능 프로세서는 next PC 계산부터 branch resolution 까지 10단계 이상이다.
원인오예측 시 fetch·부분 실행된 많은 명령어를 flush 해야 한다.
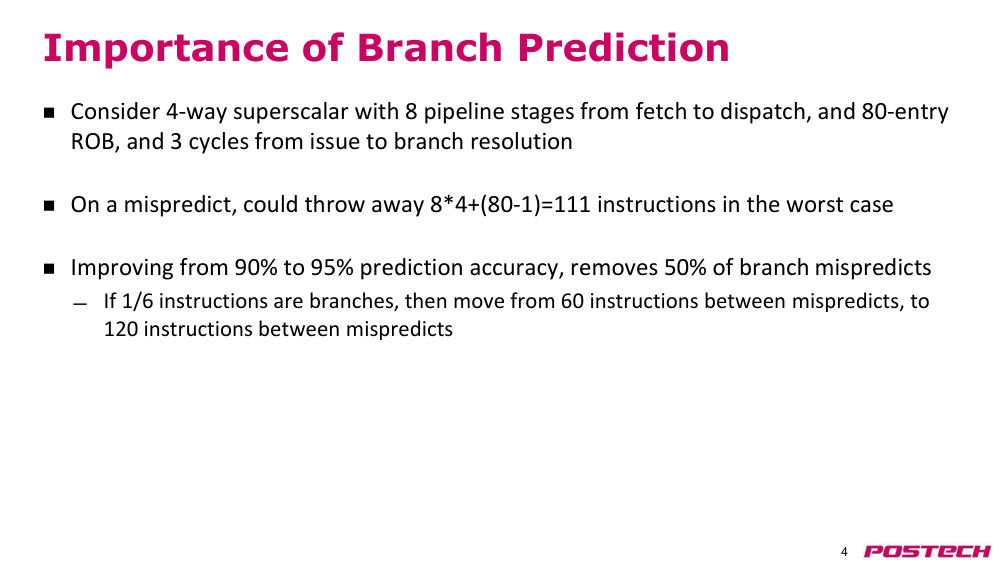
해결4-way, fetch→dispatch 8단계, ROB 80: 최악 8×4+79=111개 폐기. 정확도 90→95% 면 오예측 절반, 1/6 이 branch 면 오예측 간격 60→120.
- 20~30단계 pipeline 에서 front-end 는 여러 stage
- 정확도 5%p 개선 = misprediction 50% 감소
2.7.r.1Branch predictor — Wikipedia ↗ · static, 1-bit/2-bit saturating counter, two-level adaptive(Yeh & Patt), global/local history, hybrid, return stack
2.843:16–48:39Control-flow penalty 줄이기: software·hardware
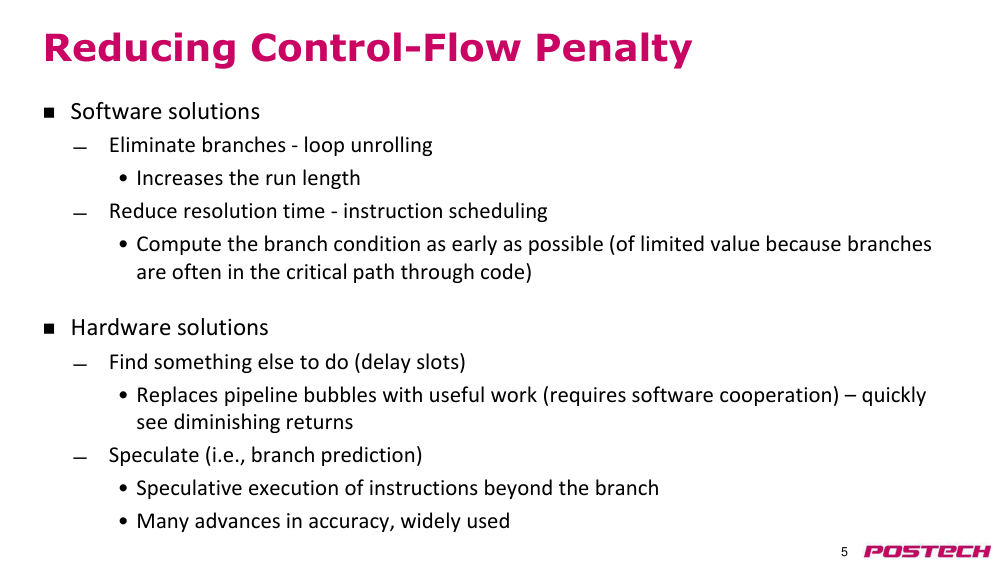
상황·문제branch 로 인한 penalty 를 줄이는 방법은 software 와 hardware 양쪽에 있다.
원인compiler 는 loop unrolling·instruction scheduling 으로 branch 수·resolution 시간을 줄이지만, branch 는 critical path 에 있어 효과가 한정.
해결branch delay slot 은 100개 명령어 pipeline 에선 효과가 미미해 현대엔 잘 안 씀. 가장 유력한 것은 speculation(branch prediction).
- loop unrolling 은 code size 증가 단점
- branch 조건 계산(add x2 등)을 앞당기면 resolution 이 빨라짐
- delay slot 은 채우지 못하면 nop
2.948:39–52:49Branch prediction 동기와 static prediction
상황·문제깊은 pipeline 성능은 branch penalty 로 제한되며 현대 predictor 는 95% 이상 정확하다.
원인prediction 구조(history 저장, target 을 빨리 얻는 구조)와 mispredict recovery 메커니즘이 필요.
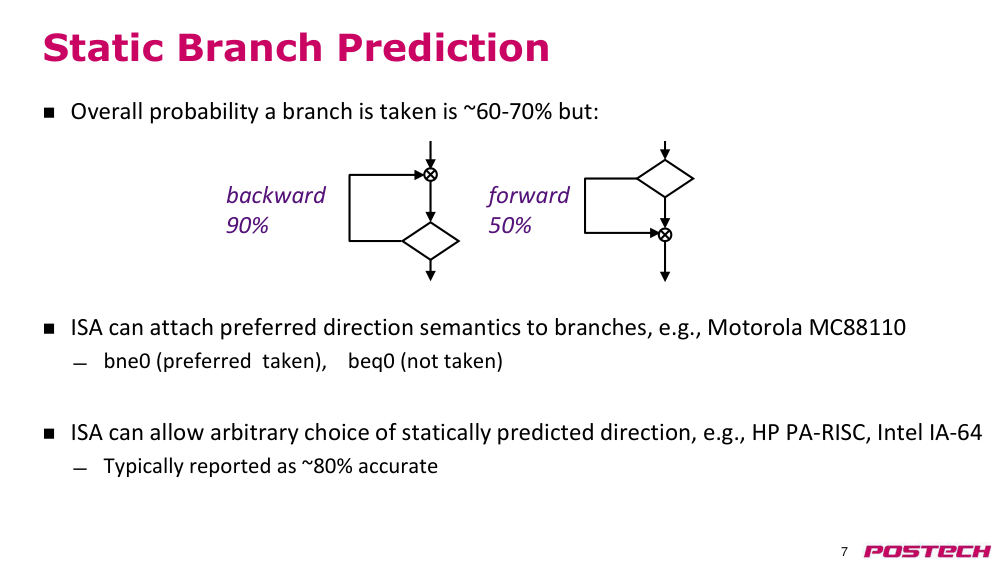
해결static: backward branch 90%, forward 50%. ISA hint(MC88110 bne0/beq0)나 임의 방향(PA-RISC, IA-64)도 가능하나 hardware 가 무시하기도.
- loop 끝 backward branch 는 static 으로도 잘 맞음
- forward branch 는 50%
2.9.r.1Branch predictor — Wikipedia ↗ · static, 1-bit/2-bit saturating counter, two-level adaptive(Yeh & Patt), global/local history, hybrid, return stack
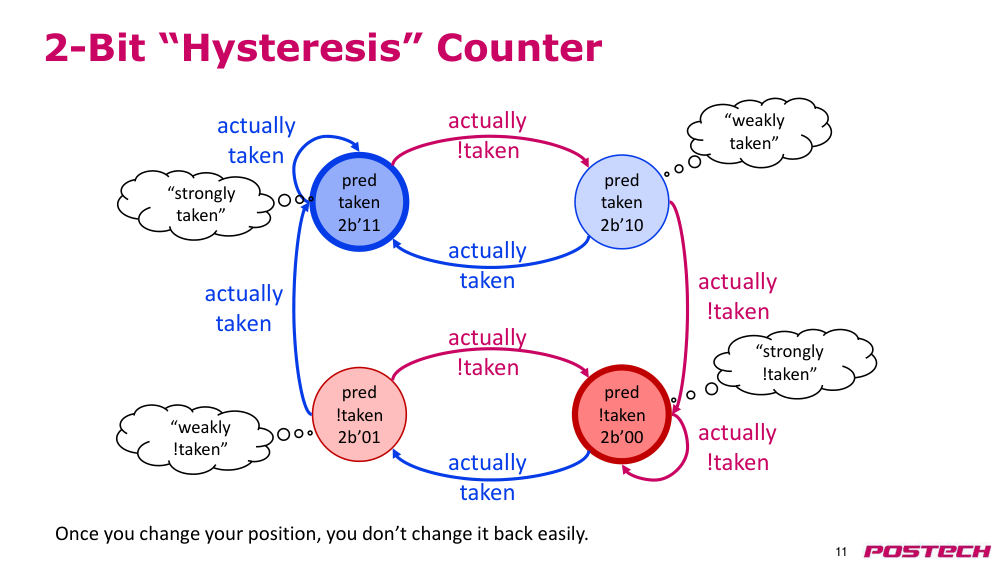
2.1052:49–1:00:26Dynamic prediction: 1-bit, 2-bit saturating, hysteresis counter
상황·문제과거 동작으로 학습: temporal correlation(같은 branch 의 과거), spatial correlation(최근 다른 branch).
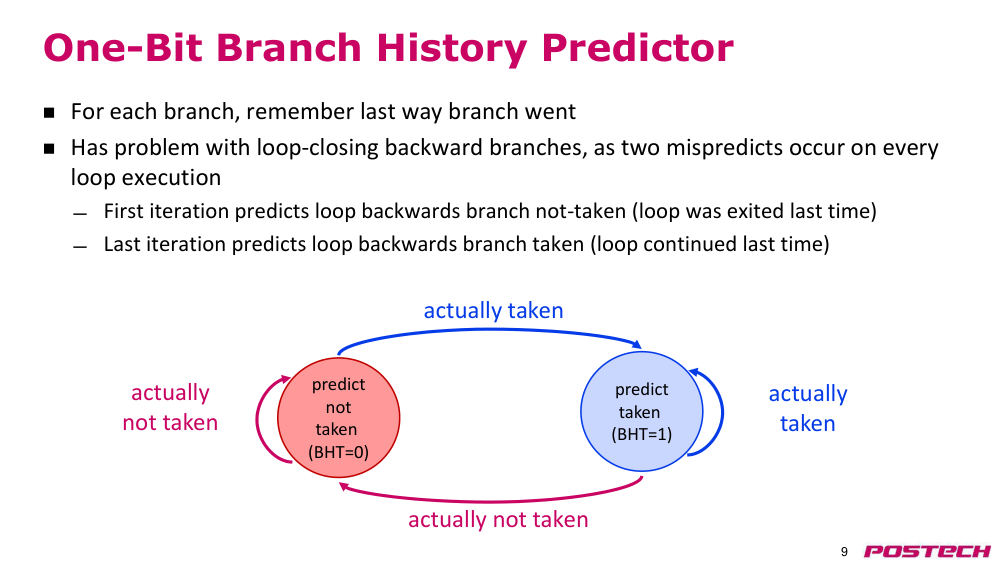
원인1-bit predictor 는 loop 를 돌 때마다 첫 iteration 과 마지막 iteration 에서 두 번 틀린다.
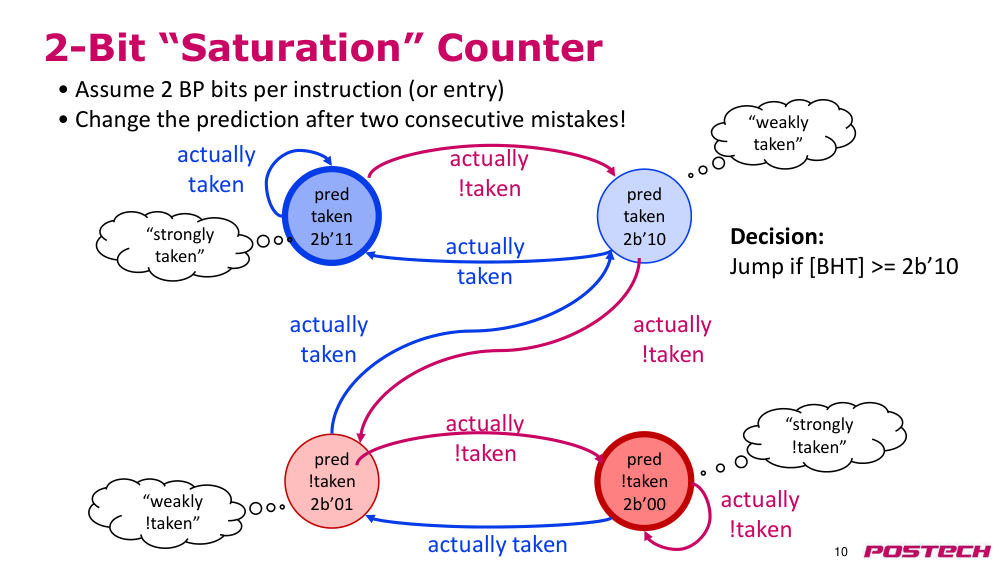
해결2-bit saturating counter: 두 번 틀려야 방향 전환 → loop 재진입 시 오예측 제거. hysteresis counter: 반대편으로 넘어가면 strongly 상태로.
- 4개 상태: strongly/weakly taken·not taken
- occasionally 다른 결과를 내는 forward branch 에도 유용
2.10.r.1Branch predictor — Wikipedia ↗ · static, 1-bit/2-bit saturating counter, two-level adaptive(Yeh & Patt), global/local history, hybrid, return stack
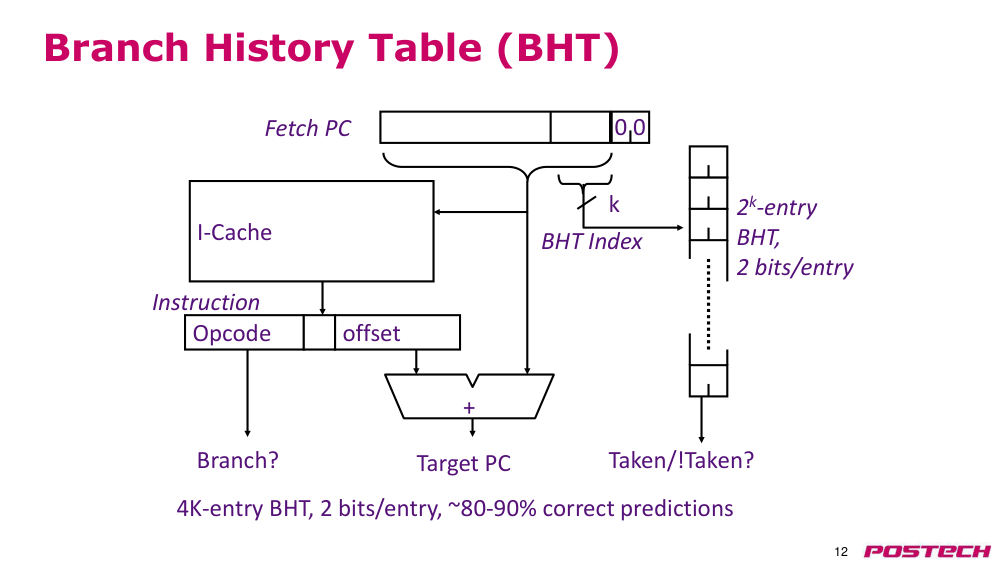
2.111:00:26–1:02:47BHT 를 pipeline 에서 쓰는 법
상황·문제decode 에서 opcode 로 branch 여부, offset+PC 로 target 을 알지만 outcome 은 아직 모른다.
원인4-byte 명령어라 PC 하위 2bit 는 00, 나머지 PC bit 일부로 BHT 를 index.
해결BHT(entry 당 1~2bit) 기록으로 taken/not-taken 을 예측해 next PC 결정. 4K-entry 2-bit BHT ≈ 80-90%.
- temporal correlation 기반
- 실행 전 예측으로 next PC 결정
2.11.r.1Branch predictor — Wikipedia ↗ · static, 1-bit/2-bit saturating counter, two-level adaptive(Yeh & Patt), global/local history, hybrid, return stack
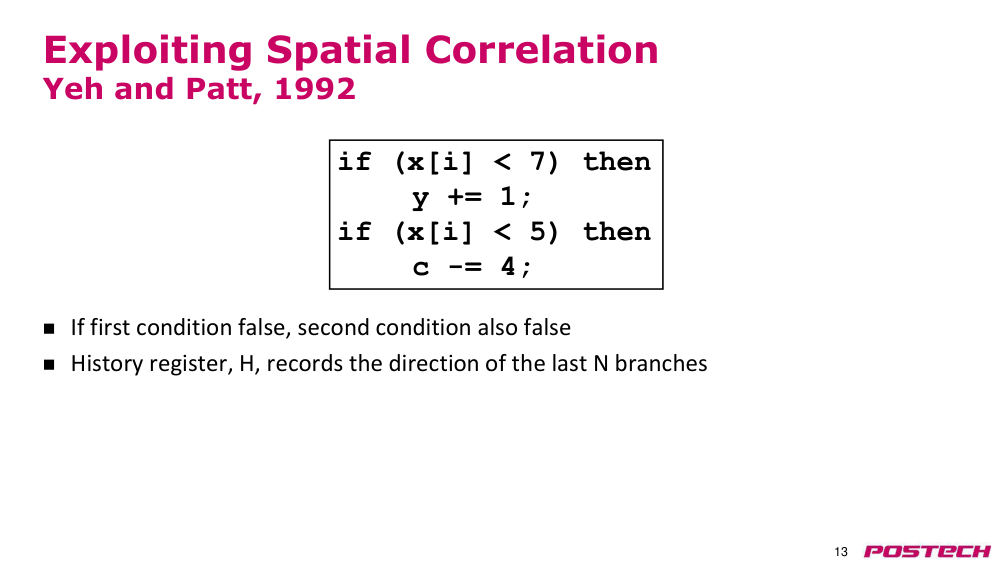
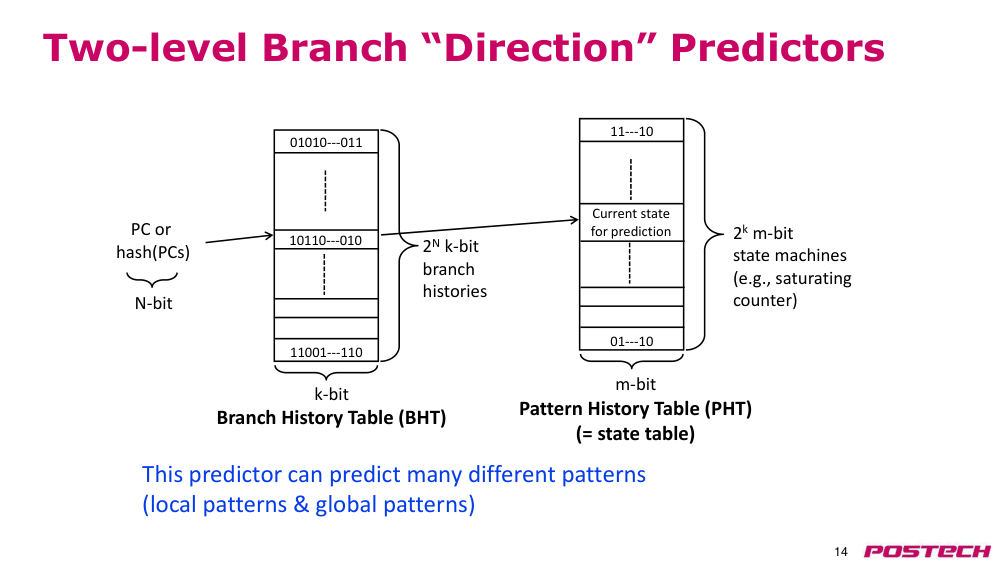
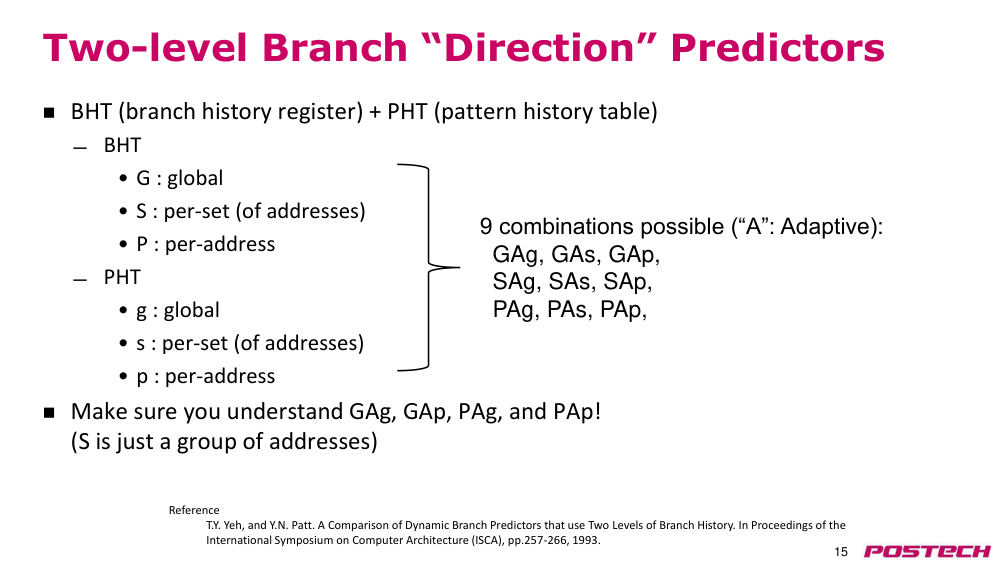
2.121:02:47–1:11:03Spatial correlation 과 two-level predictor (GAg…PAp)
상황·문제if (x[i]<7) 가 false 면 if (x[i]<5) 도 false: branch 결과가 앞선 branch 와 상관.
원인history register H 에 최근 N개 branch 방향을 기록해 이를 활용(Yeh & Patt 1992).
해결PC 로 BHT entry 선택 → 그 history 로 PHT(2-bit counter) index. BHT G/S/P × PHT g/s/p = 9가지 조합.
- 첫 table = branch history table, 둘째 = pattern history table
- 앞 BHT 슬라이드의 'BHT' 는 사실 PHT 에 해당
- local·global pattern 모두 예측 가능
2.12.r.1Branch predictor §Two-level adaptive predictor — Wikipedia ↗ · history register 로 pattern history table 을 고르는 구조
2.131:11:03–1:16:48BHT 한계와 branch target buffer
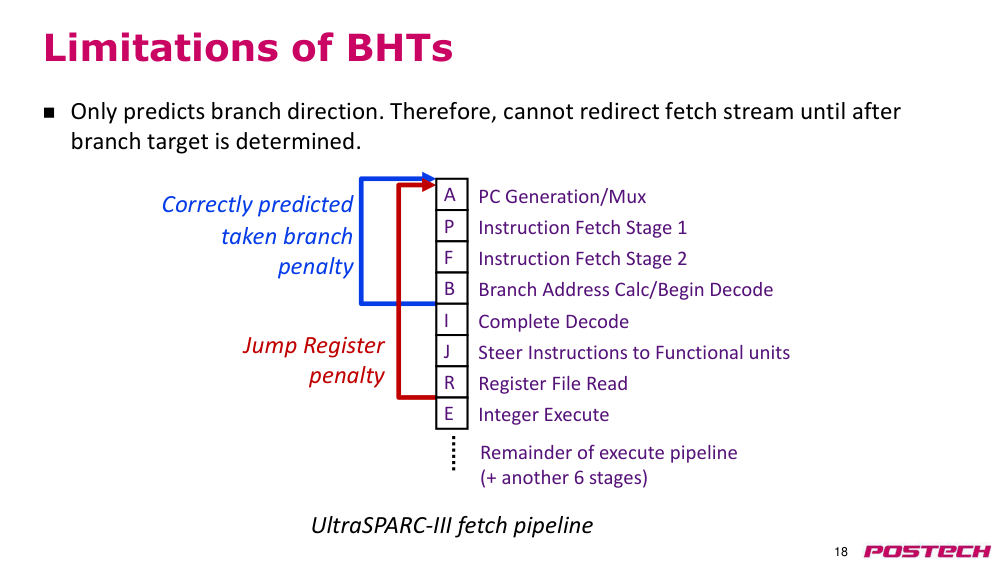
상황·문제BHT 는 방향만 예측, taken 일 때 다음 PC 는 모른다.
원인target 은 fetch·decode 후에야 계산(UltraSPARC-III), JR 은 register 값에 의존해 penalty 가 더 크다.
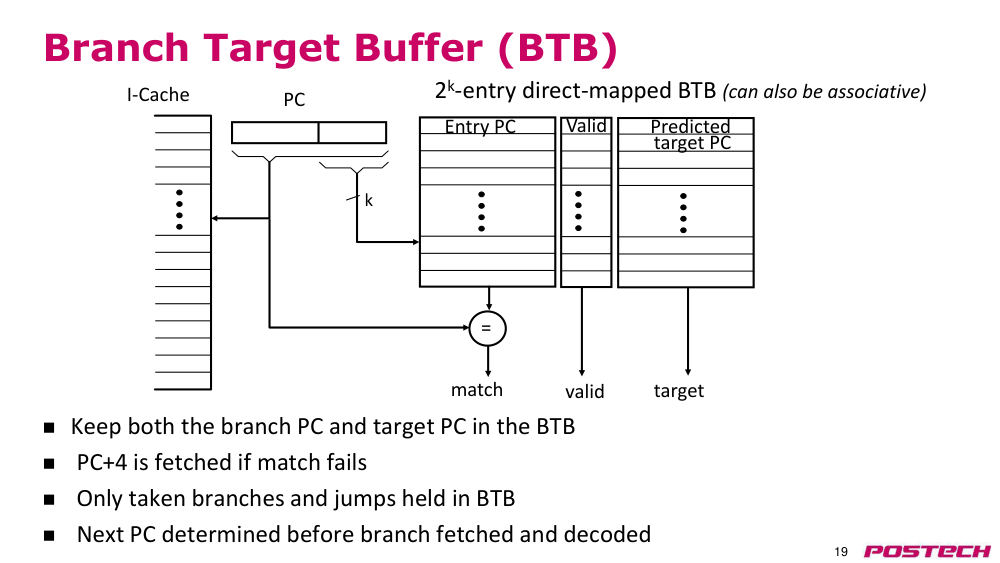
해결BTB: PC 로 index, tag·valid·target 저장. match·valid 면 target, 아니면 PC+4. taken branch·jump 만 저장.
- direction predictor 가 taken 이면 BTB target 으로 fetch
- fetch·decode 전에 next PC 결정
- 나머지(p20~)는 다음 강의
3핵심 개념
3.1LPRd(last physical destination register)
ROB entry 에 적는 destination 의 이전 physical register. commit 시 free list 로 반환, 복구 시 역순 unrenaming 에 사용.
3.1.r.1Register renaming — Wikipedia ↗ · free tag FIFO 에서 새 tag 배정, graduation 때 이전 tag 를 free queue 로 반환
3.2free list(프리 리스트)
쓰이지 않는 physical register 목록. rename 때 맨 앞을 꺼내고 commit 때 LPRd 를 돌려받음.
3.2.r.1MIT 6.5900 Quiz 1 handout — Physical Register File Design ↗ · rename table·physical register file·free list·ROB(tag 만 보관) 구성
3.3issue window(이슈 윈도우)
decode·rename 됐지만 아직 issue 안 된 명령어만 보관. ROB 는 보통 이보다 몇 배 큼.
3.3.r.1Out-of-order execution — Wikipedia ↗ · dispatch 와 issue, execute 와 graduation 을 queue 로 decouple
3.4rename table snapshot(스냅샷)
Alpha 21264 는 80개 snapshot 을 두고 오예측 시 한 cycle 에 flash copy.
3.4.r.1Alpha 21264 — Wikipedia ↗ · 최대 80개 in-flight 명령어, 40 rename register, local/global/choice tournament predictor
3.52-bit saturating counter(2비트 포화 카운터)
strongly/weakly taken·not-taken 4상태. 두 번 틀려야 예측이 바뀜.
3.5.r.1Branch predictor — Wikipedia ↗ · static, 1-bit/2-bit saturating counter, two-level adaptive(Yeh & Patt), global/local history, hybrid, return stack
3.6two-level predictor(2단계 예측기)
BHT(branch history) 로 PHT(pattern history, counter) 를 index. G/S/P × g/s/p 9조합.
3.6.r.1Branch predictor §Two-level adaptive predictor — Wikipedia ↗ · history register 로 pattern history table 을 고르는 구조
3.7branch target buffer(BTB)
PC 로 index, tag·valid·target 저장. taken 예측 시 fetch·decode 전에 next PC 제공, miss 면 PC+4.
4스스로 확인
4.1sub x6,x7,x6 에서 source x6 은 어느 physical register 를 읽나?
답
새 destination(P3) 배정 이전 mapping 인 P5.
4.2ld x1 이 commit 될 때 free list 로 돌아가는 register 는?
답
LPRd 인 P8. 이전 명령어가 x1→P8 mapping 을 더 쓰지 않음이 보장되므로.
4.3ROB 가 issue window 보다 조금만 크면 생기는 문제는?
답
실행 중 명령어가 ROB 를 채워 dispatch 가 막히고 issue window 가 놀아 FU 활용도가 떨어진다.
4.42-issue rename 에서 port 증가 외에 필요한 것은?
답
같은 cycle inst 1 dest 와 inst 2 source 비교 후 새 mapping bypass.
4.51-bit predictor 가 loop 당 두 번 틀리는 시점은?
답
loop 재진입 첫 iteration(not taken 으로 예측)과 마지막 iteration(taken 으로 예측).
4.6정확도 90→95% 개선의 의미는?
답
misprediction 50% 감소, branch 가 1/6 이면 오예측 간격 60→120 명령어.
5참고 자료
5.1Computer Architecture: A Quantitative Approach, 6th ed. — Elsevier ↗ · 교재. ca_L07 권장 3.6, ca_L08 권장 3.9-3.10
5.2Branch predictor — Wikipedia ↗ · static, 1-bit/2-bit saturating counter, two-level adaptive(Yeh & Patt), global/local history, hybrid, return stack
5.4Yeager, The MIPS R10000 Superscalar Microprocessor (IEEE Micro 1996) ↗ · active list·free list·map table, exception 시 역순 unmapping, branch mask
5.5Register renaming — Wikipedia ↗ · free tag FIFO 에서 새 tag 배정, graduation 때 이전 tag 를 free queue 로 반환