Lec 19 · Prefetching 후반: 성능 metric·software/hardware·FDP·execution-based(runahead)
정밀 정리 · 검증 2026-09-24 05:46
1개요
1.1ca_L12 p14~48: prefetcher performance metric(accuracy·coverage·timeliness)과 aggressiveness(distance·degree)
1.2software prefetching 의 어려움(x86 명령, 삽입 위치, HP PA8000 예)과 hardware prefetcher(next-line, stride, stream buffer, Pentium 4 locality-based)
1.3feedback-directed prefetching 으로 aggressiveness·insertion policy 적응, Q&A(mcf, BIOS prefetcher 설정)
1.4execution-based prefetcher 와 runahead execution, hybrid·multi-core prefetching 조율
2섹션별 정리 상황·문제 → 원인 → 해결
2.10:46–1:21시작: 갱신된 lecture note 와 slide 재배치
상황·문제PLMS 에 갱신된 lecture note 를 올렸고 slide 순서를 바꿨다고 안내. 지난 시간 basic concept 이후 prefetch performance 부터 시작
- p1~p13 은 빠르게 넘기고 p14 로 이동
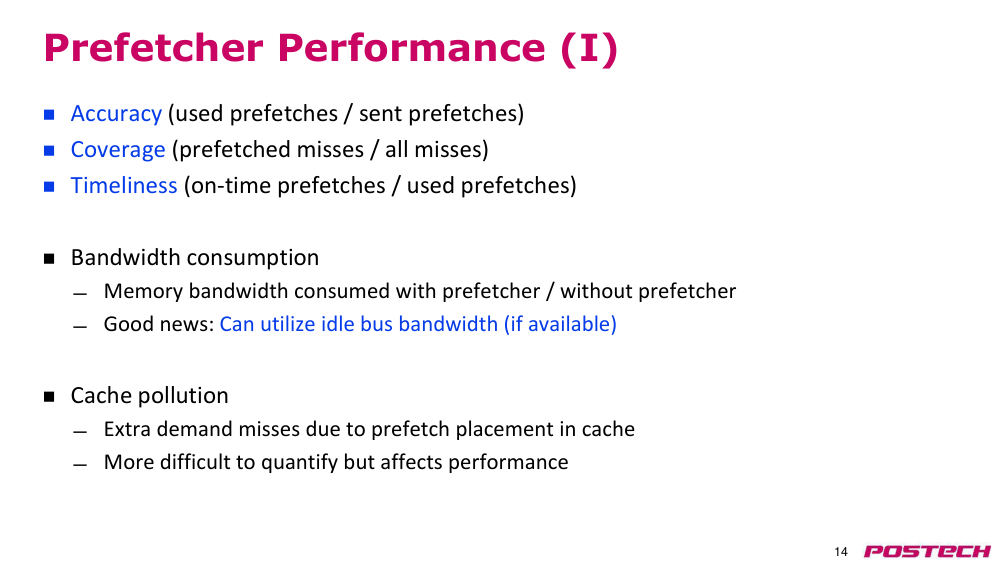
2.21:21–8:03Prefetcher performance metric: accuracy·coverage·timeliness·bandwidth·pollution
상황·문제prefetcher 를 어떤 metric 으로 평가해야 하는가. 한 metric 만 보면 잘못 판단한다
원인보수적으로 쉬운 pattern 만 prefetch 하면 accuracy(정확도)는 높지만 coverage(커버리지)는 작다. timeliness(적시성)는 Venn diagram 에 안 잡힌다
해결accuracy·coverage·timeliness 를 동시에 보고, bandwidth 소비와 cache pollution(캐시 오염)도 고려. idle bus bandwidth 에 prefetch 를 보내고 demand 를 우선
- accuracy = used prefetches / sent prefetches, coverage = prefetched misses / all misses
- timeliness = on-time prefetches / used prefetches (demand access 시점에 도착했는가)
- accurate·high coverage·timely 여도 bandwidth 경쟁으로 demand access 를 늦춰 성능을 떨어뜨릴 수 있음
- cache 에 넣으면 곧 쓰일 line 을 evict 하는 pollution 발생
2.2.r.1Wikipedia: Cache prefetching ↗ · accuracy·coverage·timeliness 정의, stream buffer·stride·compiler prefetching 개요
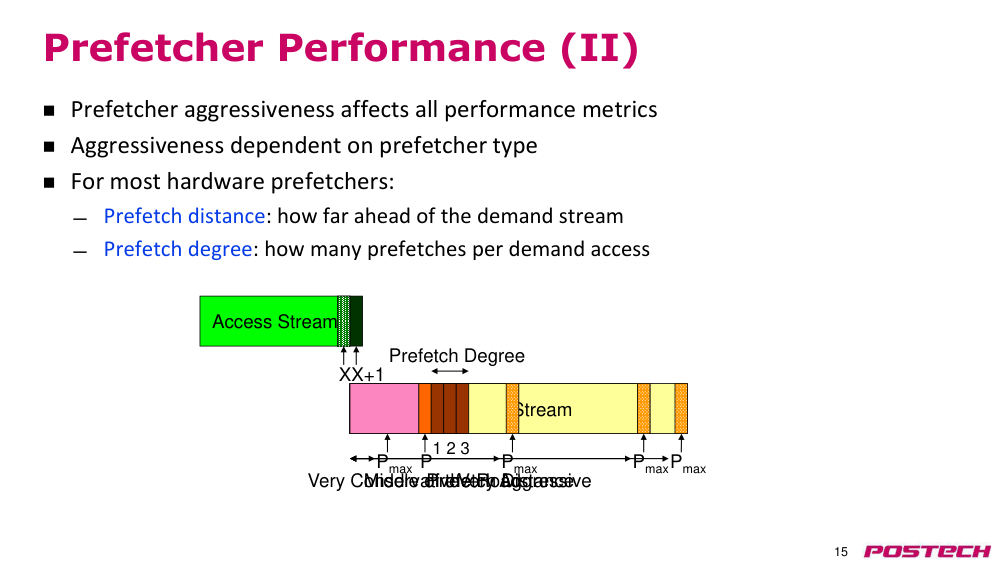
2.38:03–11:52Prefetcher aggressiveness: prefetch distance 와 prefetch degree
상황·문제aggressiveness(공격성)가 모든 performance metric 에 영향. 최종 평가는 workload 의 IPC
원인너무 aggressive 하면 bandwidth·pollution, 너무 conservative 하면 coverage·timeliness 손해
해결두 knob 로 조절: prefetch distance(demand stream 보다 얼마나 앞서) 와 prefetch degree(demand access 당 몇 개)
- 강의자가 array 위에 현재 access 위치와 멀리/가까이 prefetch 위치를 그려 distance 설명
- 근처 cache block 을 함께 가져오는 양 = degree
2.411:52–16:40Software prefetching: x86 prefetch 명령과 삽입 위치의 어려움
상황·문제compiler/programmer 가 prefetch instruction 을 코드에 넣는 방식. 어디에, 얼마나 앞에 넣을지가 문제
원인모든 load 에 넣으면 대부분 cache hit 이라 memory·execution bandwidth 낭비. profile 입력이 대표성이 없을 수 있고, 수백 instruction 앞에 넣으면 사이의 branch 때문에 accuracy 하락
해결profile 로 miss 가능 load 만 골라 삽입, distance 도 profile 로 추정 (입력 대표성 한계는 남음)
- p16~17 은 지난 시간에 다뤘다며 skip
- x86 PREFETCHT0/T1/T2/NTA: 대상 cache level 이 microarchitecture 마다 다름 (Pentium 3 는 T0 → L1/L2, Pentium 4·Xeon 은 L2 만)
- super-pipelined superscalar·high clock 일수록 필요한 distance 가 커져 accurate·timely 를 동시에 맞추기 어려움
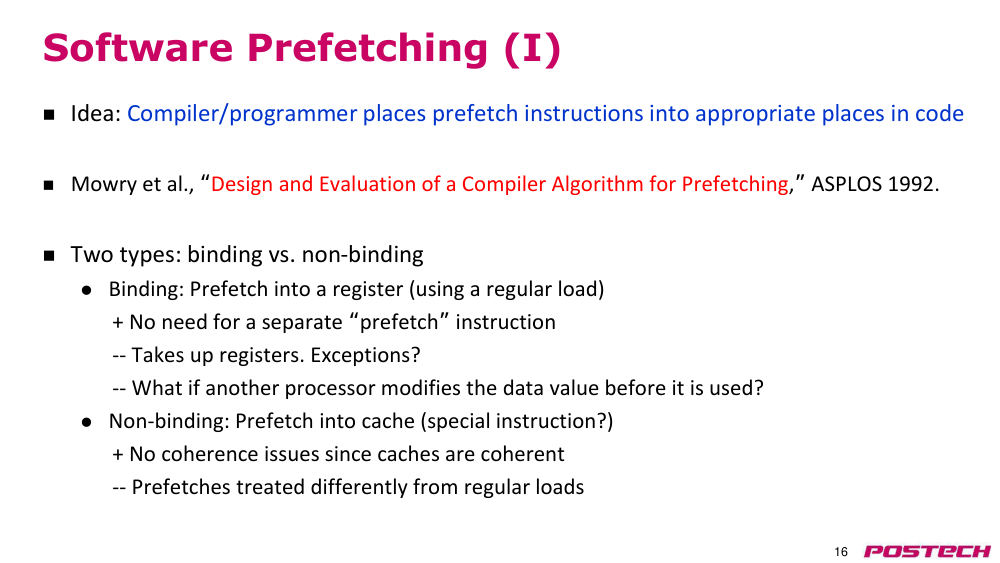
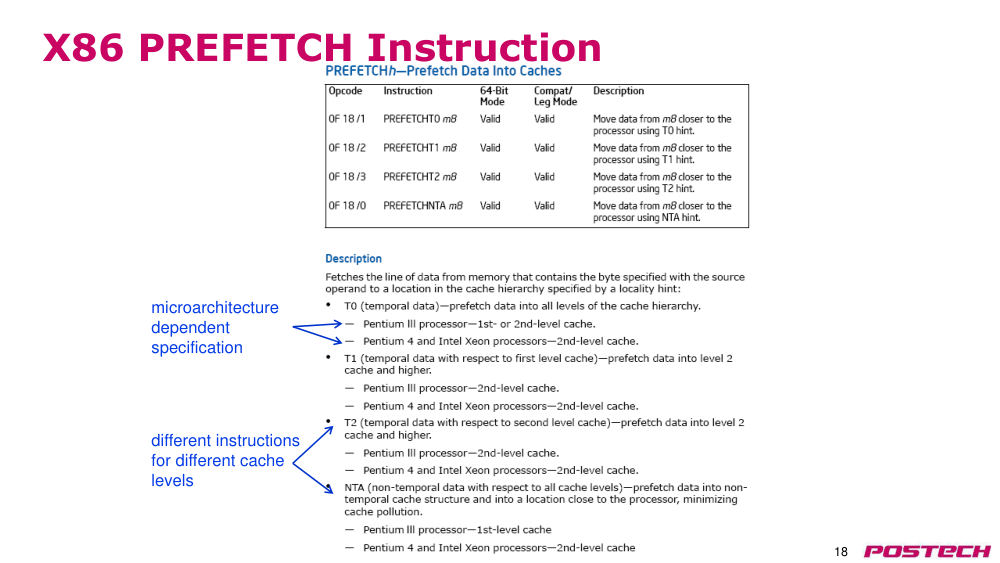
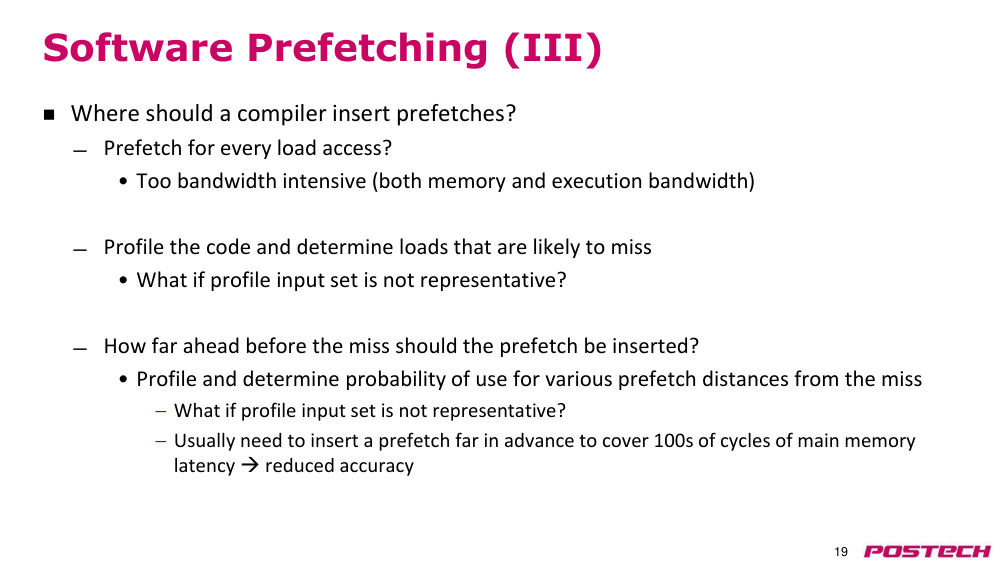
2.4.r.2Mowry, Lam, Gupta, Design and Evaluation of a Compiler Algorithm for Prefetching (ASPLOS 1992, PDF) ↗ · p16 에 인용된 compiler prefetching 원 논문
2.516:40–19:22Software prefetching 예: HP PA8000 (Santhanam et al., 1997)
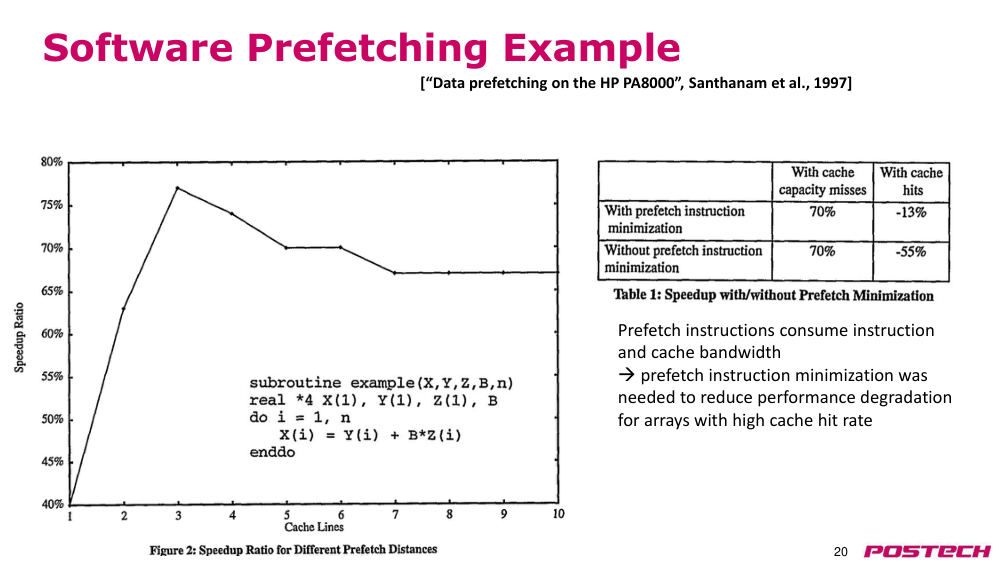
상황·문제단순 loop X(i)=Y(i)+B*Z(i) 에서 prefetch distance 와 삽입 정책을 바꿔 speedup 측정
원인distance 를 늘리면 어느 지점까지 speedup 이 커지다 이후 오히려 감소. 이상적인 distance 는 다 돌려 봐야 안다
해결prefetch instruction minimization 여부 비교: capacity miss 가 많은 경우 차이 없음(70%), cache hit 이 높은 경우 minimization 안 하면 -55% (하면 -13%)
- prefetch instruction 이 instruction/cache bandwidth 를 소비
- 성능은 program behavior 에 따라 크게 달라짐
2.619:22–24:55Hardware prefetching 과 next-line prefetcher
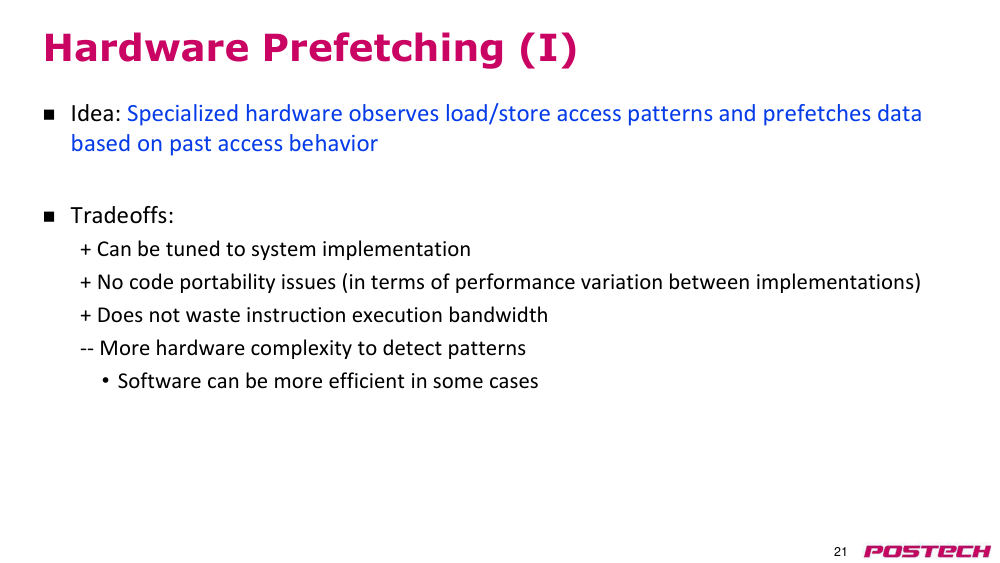
상황·문제전용 hardware 가 load/store(또는 miss) pattern 을 관찰해 과거 행동으로 prefetch
원인software prefetch 는 같은 binary 가 processor 마다 효과가 달라 portability 문제, execution bandwidth 도 소모
해결hardware 는 구현에 맞게 tuning, portability 문제 없음, instruction bandwidth 낭비 없음. 대가는 pattern detection 복잡도
- next-line prefetcher: demand access/miss 뒤 항상 다음 N 개 line. sequential·streaming, instruction access 에 효과적
- stride 2·degree 1 이면 전혀 안 쓰일 line 만 가져옴, 역방향 순회에도 무용
- 앞뒤 모두 prefetch 하면 prefetch bandwidth 의 최소 50% 낭비
2.6.r.1Wikipedia: Cache prefetching ↗ · accuracy·coverage·timeliness 정의, stream buffer·stride·compiler prefetching 개요
2.724:55–31:33Stride prefetcher 와 stream buffer (Jouppi, ISCA 1990)
상황·문제next-line 보다 일반적인 stride pattern 을 잡는 prefetcher
원인loop 안에서 여러 array 를 서로 다른 stride 로 접근하는 경우가 많음
해결PC 기반(Baer & Chen: load 별 last address·stride 기록 → last+stride prefetch) 또는 cache block address 기반(entry 별 tag·stride·confidence). stream buffer 는 별도 FIFO 에 prefetch
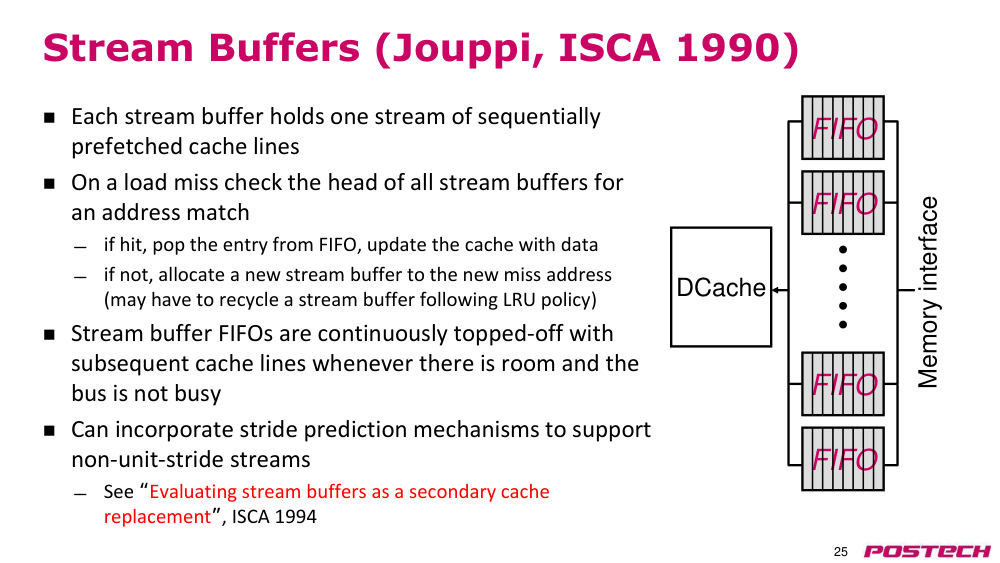
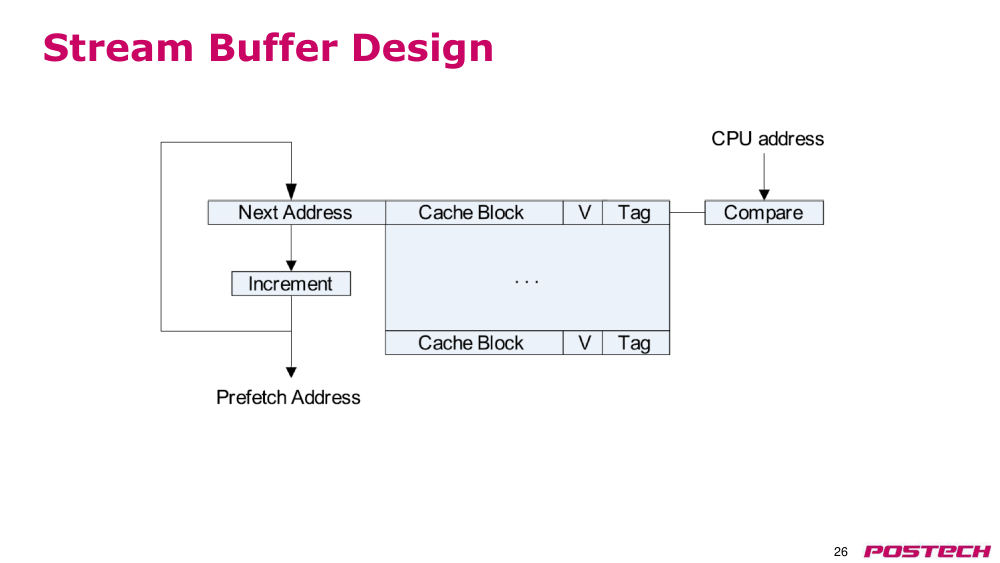
- stream buffer: load miss 시 각 buffer head 비교, hit 면 cache 로 옮기고 pop 후 다음 line prefetch, 아니면 새 buffer 할당
- buffer 가 모자라면 하나를 deallocate 해 새 stream 에 사용
- non-unit stride stream 으로 확장한 후속 논문 언급
2.7.r.1Jouppi, Retrospective: Improving Direct-Mapped Cache Performance ... Prefetch Buffers (PDF) ↗ · ISCA 1990 stream buffer 논문 저자 회고
2.7.r.2Wikipedia: Cache prefetching ↗ · accuracy·coverage·timeliness 정의, stream buffer·stride·compiler prefetching 개요
2.831:33–37:33Locality-based prefetcher: Pentium 4(-like) prefetcher
상황·문제많은 program 은 완전한 stride 가 아니라 근처 주소 안에서 random 해 보이는 pattern
원인stride detector 로는 region 내 localized random access 를 못 잡음
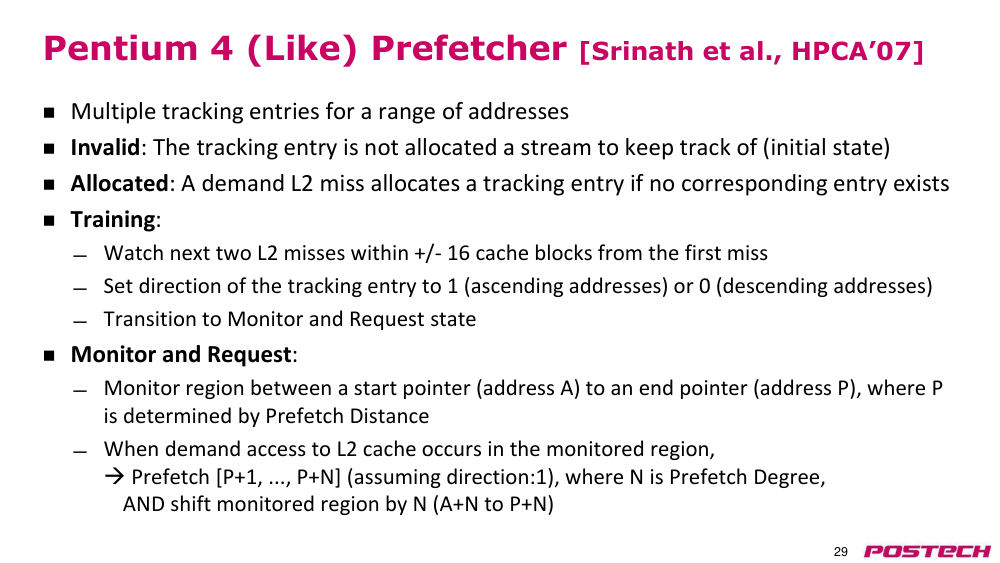
해결region 별 tracking entry: Invalid → Allocated(L2 demand miss) → Training(±16 block 안의 다음 2 miss 로 direction) → Monitor and Request. region 에 access 오면 P 부터 N 개 prefetch 후 region 을 N 만큼 이동
- N = prefetch degree, [A, P] 사이 distance 로 monitor 범위 결정
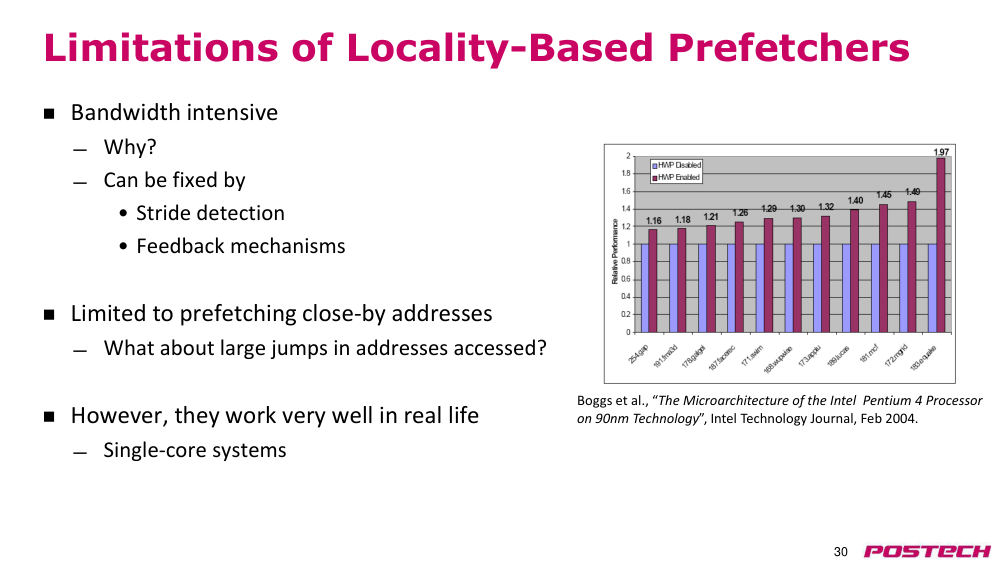
- 좋은 성능엔 N 이 커야 해 bandwidth-intensive, 큰 address jump 는 못 잡음
- 개선책: stride detection, feedback mechanism
2.8.r.1Srinath, Mutlu, Kim, Patt, Feedback Directed Prefetching (HPCA 2007, PDF) ↗ · Pentium 4-like prefetcher·FDP aggressiveness·insertion policy 원 논문
2.937:33–40:03Prefetcher 효과와 accuracy vs IPC
상황·문제Intel Pentium 4 결과: hardware prefetcher 를 켜면 최대 97% 성능 향상
원인single core 라 bandwidth 경쟁이 없었을 가능성. multi-core 에선 다른 core 의 demand access 와 경쟁
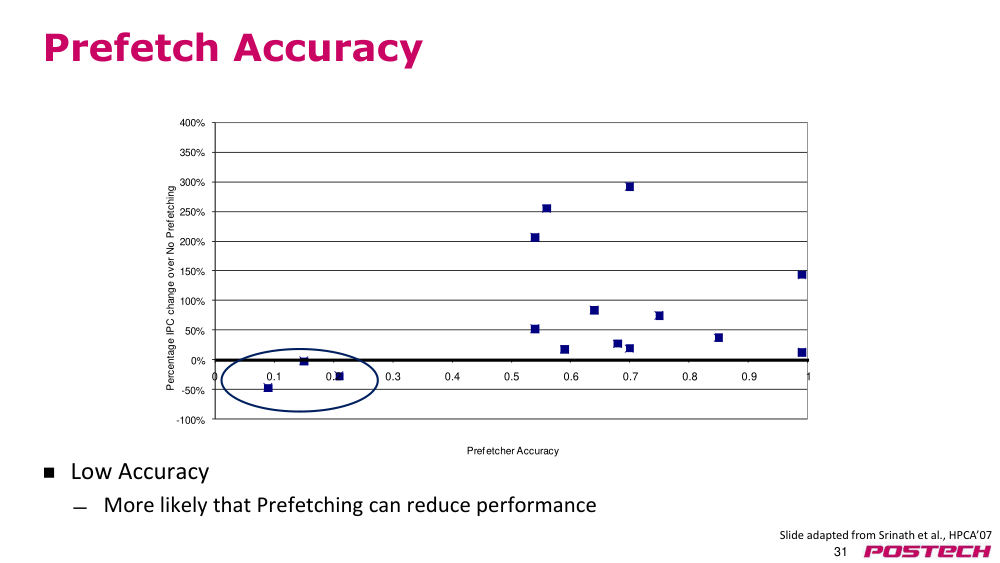
해결application 별 accuracy–IPC 변화 scatter: 대부분 향상되지만 일부는 저하/무영향 → 그런 경우 prefetcher 를 끄는 것이 나음
- multi/many-core prefetcher 는 bandwidth 낭비에 특히 주의
2.1040:03–49:26Feedback-directed prefetching (FDP, HPCA 2007)
상황·문제고정 aggressiveness 는 application 에 따라 성능을 오히려 떨어뜨림
원인application 마다 최적 aggressiveness·insertion 위치가 다름. static policy 는 모두에 최적일 수 없음
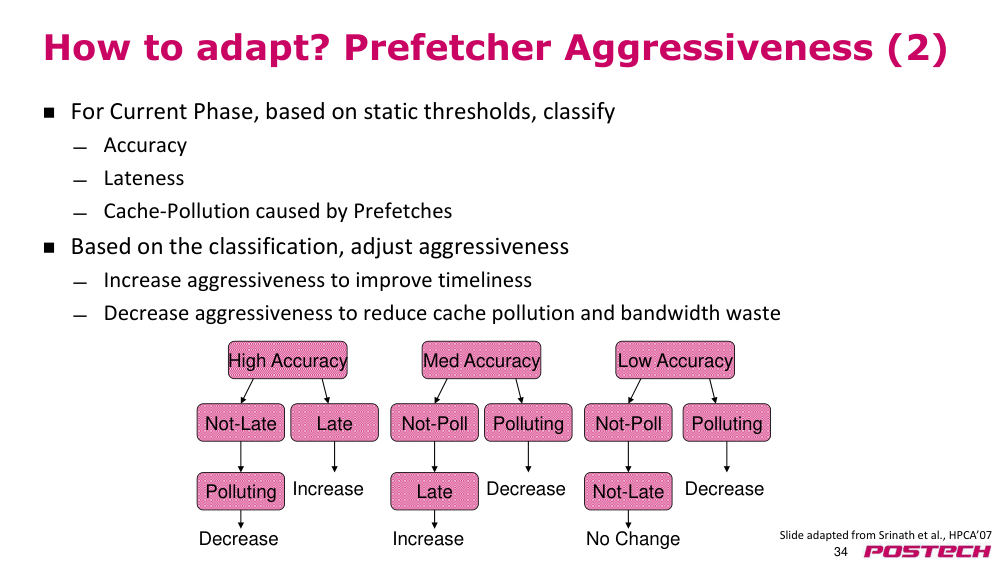
해결accuracy·lateness·pollution 을 static threshold 로 분류해 aggressiveness(distance 4·degree 1 ~ 64·4) 조절, pollution 정도로 insertion 위치(MID/LRU-4/LRU) 선택
- pollution 이 있으면 aggressiveness 감소, pollution 없고 late 면 증가, low accuracy 에서 non-polluting·not late 면 유지
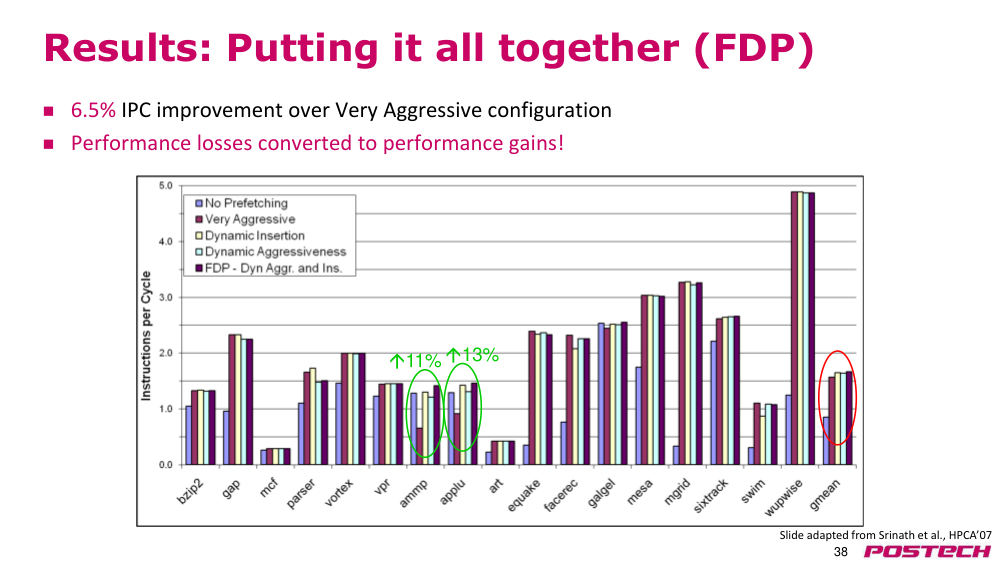
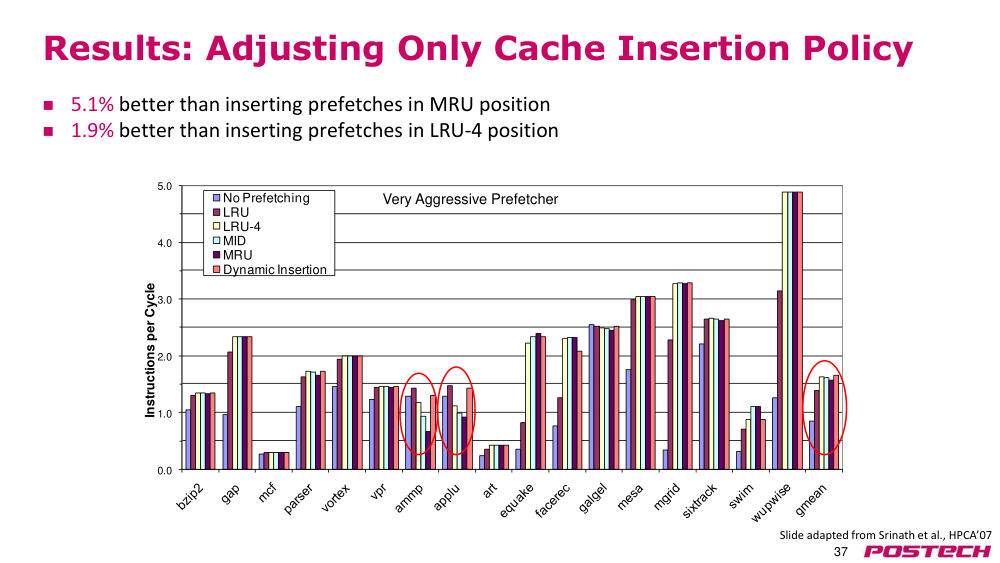
- dynamic aggressiveness 가 모든 static 구성보다 평균 최고, insertion 도 ammp·equake 처럼 app 마다 최적이 다름
- 둘을 합친 FDP 가 최고: very aggressive 대비 IPC 6.5% 향상
2.10.r.1Srinath, Mutlu, Kim, Patt, Feedback Directed Prefetching (HPCA 2007, PDF) ↗ · Pentium 4-like prefetcher·FDP aggressiveness·insertion policy 원 논문
2.1149:26–55:13Q&A: mcf 가 반응 없는 이유, program/OS 의 prefetcher 선택
상황·문제왜 mcf 는 policy 에 따라 차이가 없나? program 이나 OS 가 thread 별 prefetch policy 를 고를 수 있나?
원인mcf 는 memory intensive·irregular access 에 miss rate 가 높아 prefetch 효과·pollution 영향 모두 작음 (강의자: 정확한 이유는 모름, 논문 참조). locality prefetcher 의 max N 이 4 뿐이라 작은 region
해결program 이 고르려면 hardware prefetcher 종류를 알아야 하고 새 세대에 적응 못함. 실제로는 BIOS 에서 일부 prefetcher 를 끌 수 있음
- irregular pattern 을 겨냥한 다른 prefetcher 는 mcf 도 개선 가능하다고 언급
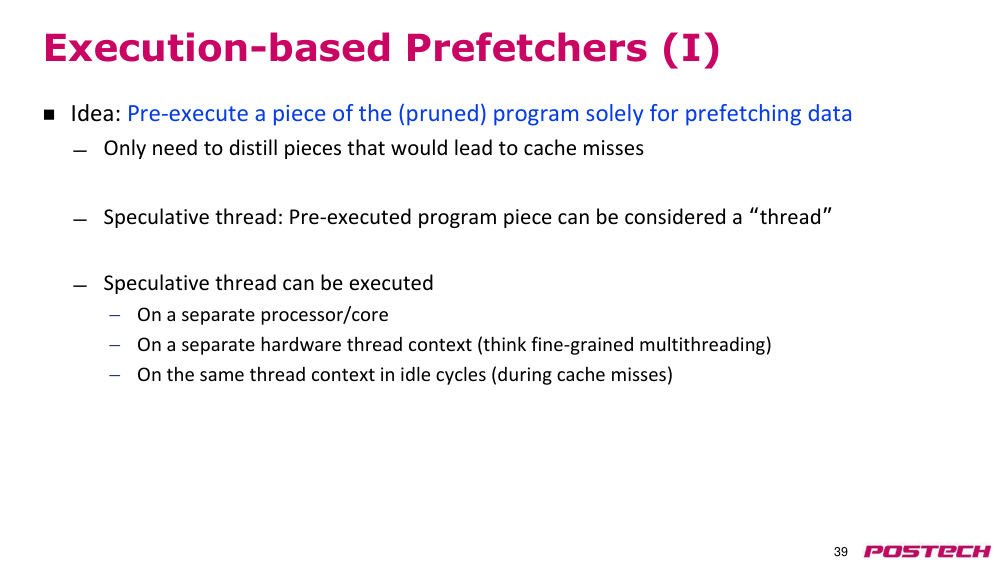
2.1255:13–1:03:13Execution-based prefetcher
상황·문제pattern 기반 prefetcher 로 잡기 어려운 access 를 program 을 미리 실행해 prefetch
원인speculative thread 가 main thread 보다 충분히 앞서야 하고, address 생성과 무관한 계산은 낭비
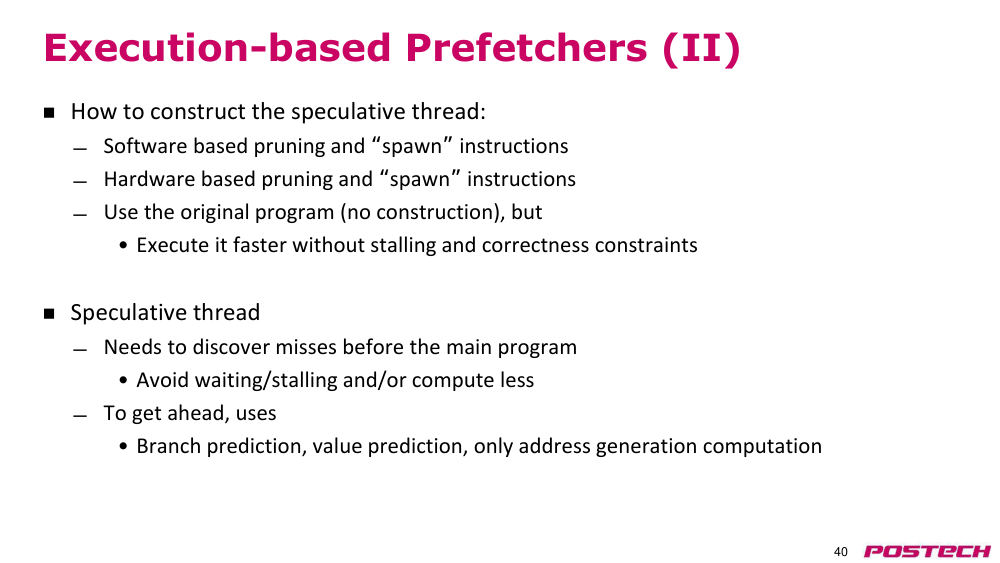
해결miss 를 유발할 부분만 추출한 speculative thread 를 별도 core·SMT context·같은 context 의 idle cycle 에서 실행. branch/value prediction 을 쓰고 address 계산만 수행
- 생성 방법: software/hardware pruning + spawn instruction, 또는 원 program 을 stall·correctness 제약 없이 실행
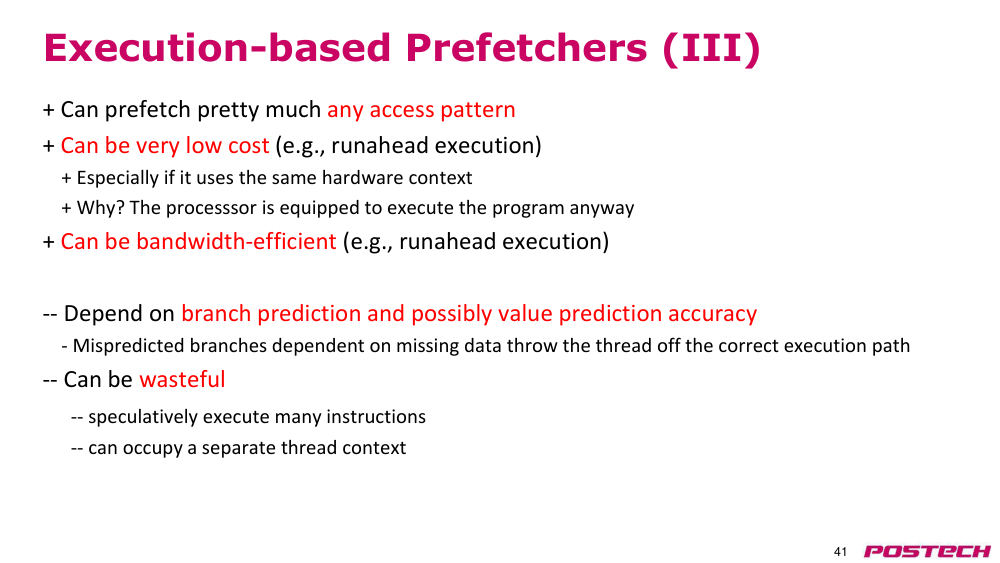
- + 거의 모든 pattern, 저비용(OoO 의 speculation 재사용), distance/degree knob 없이 bandwidth-efficient
- - branch/value prediction 정확도 의존, 추가 instruction 실행으로 main thread 와 경쟁·energy 낭비
2.131:03:13–1:10:19Runahead execution (Mutlu et al., HPCA 2003)
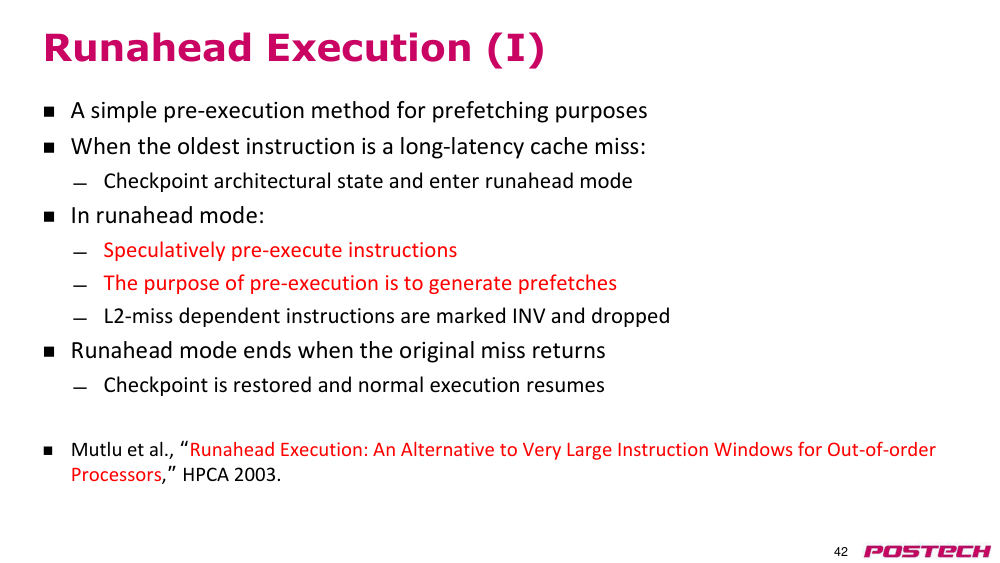
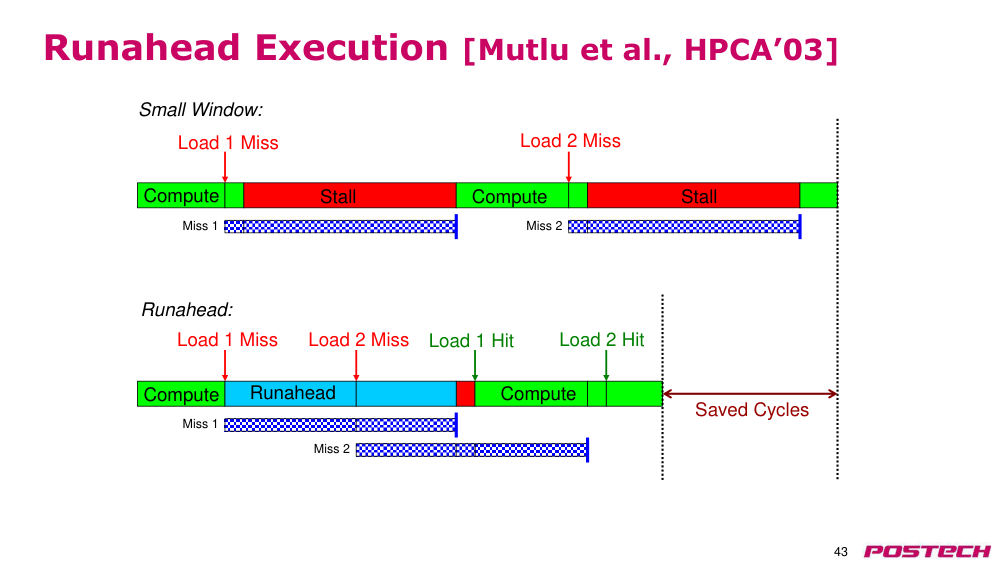
상황·문제ROB 의 oldest instruction 이 long-latency cache miss 면 processor 가 오래 stall
원인small window 에서는 dependent instruction 때문에 곧 멈추고, 다음 miss(load 2)는 첫 miss 해결 뒤에야 발생
해결architectural state 를 checkpoint 하고 runahead mode 로 speculative pre-execute, L2 miss 의존 instruction 은 INV 로 표시. 원 miss 가 돌아오면 checkpoint 복원 후 재실행 → load 2 가 hit
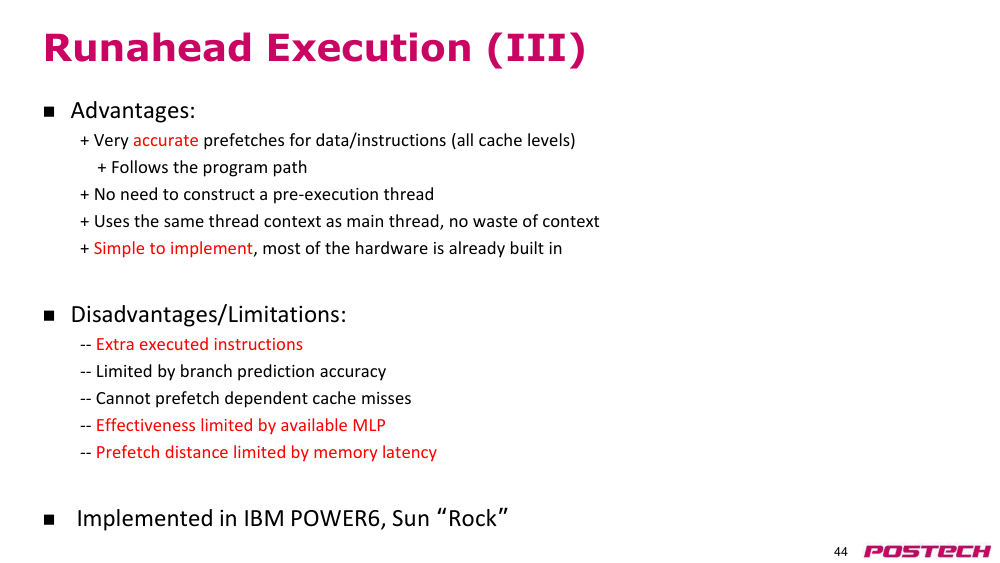
- + program path 를 따라 data/instruction 모두 정확히 prefetch, 별도 thread context 불필요, 구현 간단
- - 추가 instruction 실행, branch prediction 한계, dependent miss 불가, MLP·memory latency 에 효과 제한
- IBM POWER6, Sun Rock 에 구현
2.141:10:19–1:15:03Hybrid prefetcher 와 multi-core prefetching
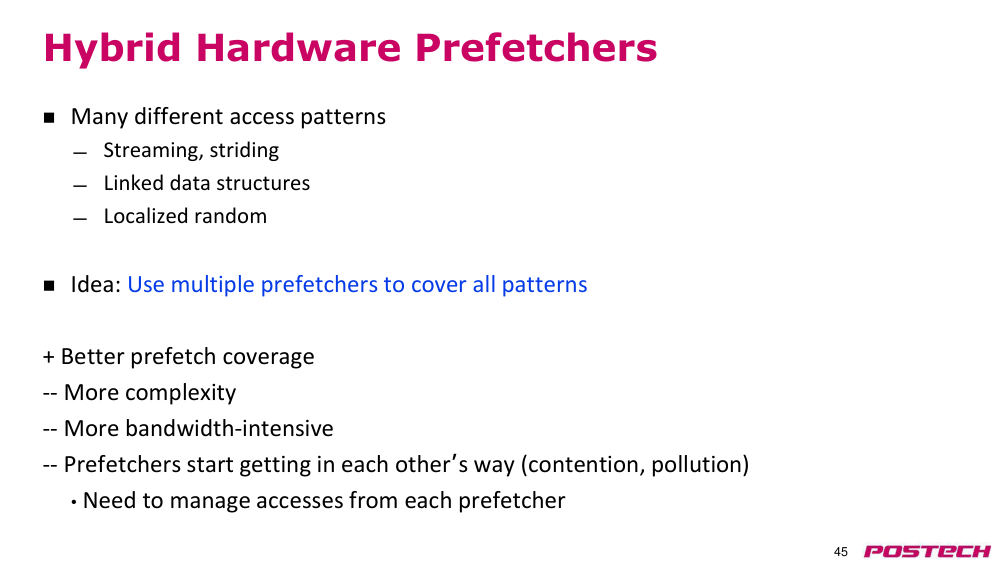
상황·문제streaming·stride·linked structure·localized random 등 pattern 이 다양
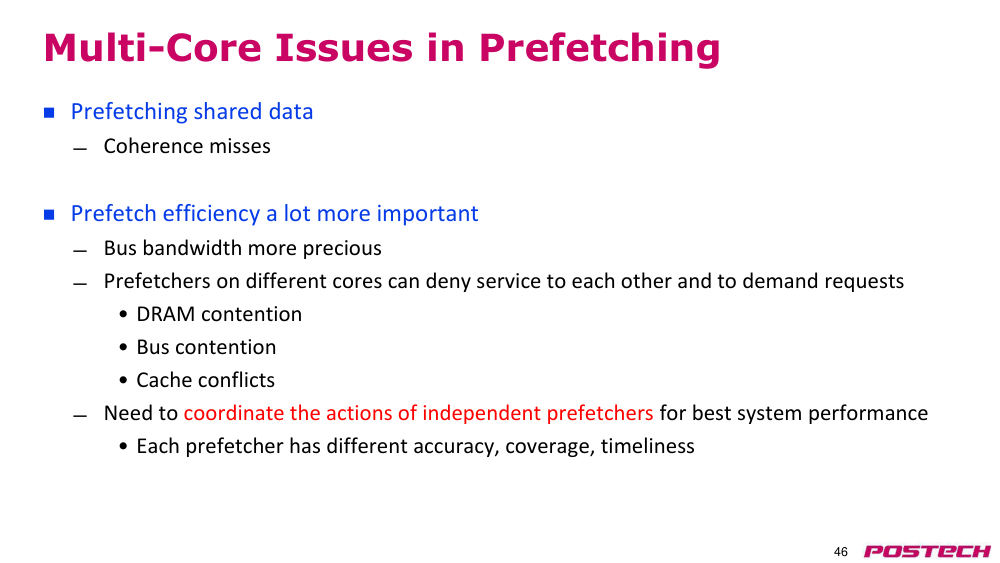
원인여러 prefetcher 를 합치면 complexity·bandwidth 증가, prefetcher 간·demand 와 contention. multi-core 에선 shared data prefetch 가 다른 core 의 line 을 invalidate 할 수 있고 bus bandwidth 가 더 귀함
해결utility 추정 기반 우선순위, cost-benefit 분석, local controller throttling 을 override 하는 global controller
- 과도한 prefetch 는 다른 core demand 에 denial of service
- 추천 읽기 교재 2.5-2.6장
3핵심 개념
3.1prefetch accuracy(정확도)
used prefetches / sent prefetches
3.1.r.1Wikipedia: Cache prefetching ↗ · accuracy·coverage·timeliness 정의, stream buffer·stride·compiler prefetching 개요
3.2prefetch coverage(커버리지)
prefetched misses / all misses. accuracy 와 함께 봐야 함
3.2.r.1Wikipedia: Cache prefetching ↗ · accuracy·coverage·timeliness 정의, stream buffer·stride·compiler prefetching 개요
3.4prefetch distance / degree
demand stream 보다 얼마나 앞서 / demand access 당 몇 line 을 prefetch 하는가
3.5next-line prefetcher(다음 라인 프리패처)
demand access/miss 뒤 항상 다음 N line. 단순하지만 stride·역방향에 무용
3.5.r.1Wikipedia: Cache prefetching ↗ · accuracy·coverage·timeliness 정의, stream buffer·stride·compiler prefetching 개요
3.6stream buffer(스트림 버퍼)
sequential prefetch line 을 cache 가 아닌 FIFO 에 보관, miss 시 head 비교
3.6.r.1Jouppi, Retrospective: Improving Direct-Mapped Cache Performance ... Prefetch Buffers (PDF) ↗ · ISCA 1990 stream buffer 논문 저자 회고
3.7feedback-directed prefetching(FDP)
accuracy·lateness·pollution feedback 으로 aggressiveness·insertion 위치를 동적 조절
3.7.r.1Srinath, Mutlu, Kim, Patt, Feedback Directed Prefetching (HPCA 2007, PDF) ↗ · Pentium 4-like prefetcher·FDP aggressiveness·insertion policy 원 논문
3.8runahead execution(런어헤드 실행)
long-latency miss 동안 checkpoint 후 pre-execute 해 미래 miss 를 prefetch, 복귀 시 복원
3.9memory-level parallelism(MLP)
여러 miss 를 동시에 처리하는 능력. runahead 효과의 상한
4스스로 확인
4.1accuracy 가 매우 높은 prefetcher 가 좋은 prefetcher 가 아닐 수 있는 이유는?
답
쉬운 pattern 만 보수적으로 prefetch 하면 coverage 가 작아 대부분의 miss 가 남는다
4.2next-line prefetcher 가 무용한 두 access pattern 은?
답
stride 2(degree 1) 와 높은 주소→낮은 주소 역방향 순회
4.3FDP 가 prefetch 가 late 이고 pollution 이 없을 때 하는 일은?
답
aggressiveness 를 높여 더 일찍 prefetch 한다
4.4runahead execution 이 dependent cache miss 를 prefetch 하지 못하는 이유는?
답
L2 miss 에 의존하는 instruction 은 값이 없어 INV 로 표시·무시되기 때문
4.5multi-core 에서 prefetch 효율이 더 중요한 이유는?
답
bus/DRAM bandwidth 를 공유해 과도한 prefetch 가 다른 core 의 demand 를 막고, shared data prefetch 가 coherence miss 를 유발
5참고 자료
5.1Wikipedia: Cache prefetching ↗ · accuracy·coverage·timeliness 정의, stream buffer·stride·compiler prefetching 개요
5.2Srinath, Mutlu, Kim, Patt, Feedback Directed Prefetching (HPCA 2007, PDF) ↗ · Pentium 4-like prefetcher·FDP aggressiveness·insertion policy 원 논문
5.4Jouppi, Retrospective: Improving Direct-Mapped Cache Performance ... Prefetch Buffers (PDF) ↗ · ISCA 1990 stream buffer 논문 저자 회고
5.5Mowry, Lam, Gupta, Design and Evaluation of a Compiler Algorithm for Prefetching (ASPLOS 1992, PDF) ↗ · p16 에 인용된 compiler prefetching 원 논문
5.7Hennessy & Patterson, Computer Architecture: A Quantitative Approach 6e (Elsevier) ↗ · 추천 읽기 Chapter 2.5-2.6