Lec 10 · Multithreading(다중 스레딩)
정밀 정리 · 검증 2026-09-24 04:17
1개요
1.1단일 thread 의 ILP 한계를 TLP 로 보완하는 hardware multithreading 을 다룬다.
1.2fixed interleave(CDC 6600 PP) → fine-grain(HEP, Tera MTA) → coarse-grain(Alewife, RS64-IV, Niagara) 순으로 발전.
1.3SMT 는 OoO superscalar 의 window 로 여러 thread 를 같은 cycle 에 발행해 vertical·horizontal waste 를 모두 줄인다.
1.4Pentium 4·Power5 사례, application 조합에 따른 성능, ICOUNT policy, SMT side channel 보안 문제로 마무리.
2섹션별 정리 상황·문제 → 원인 → 해결
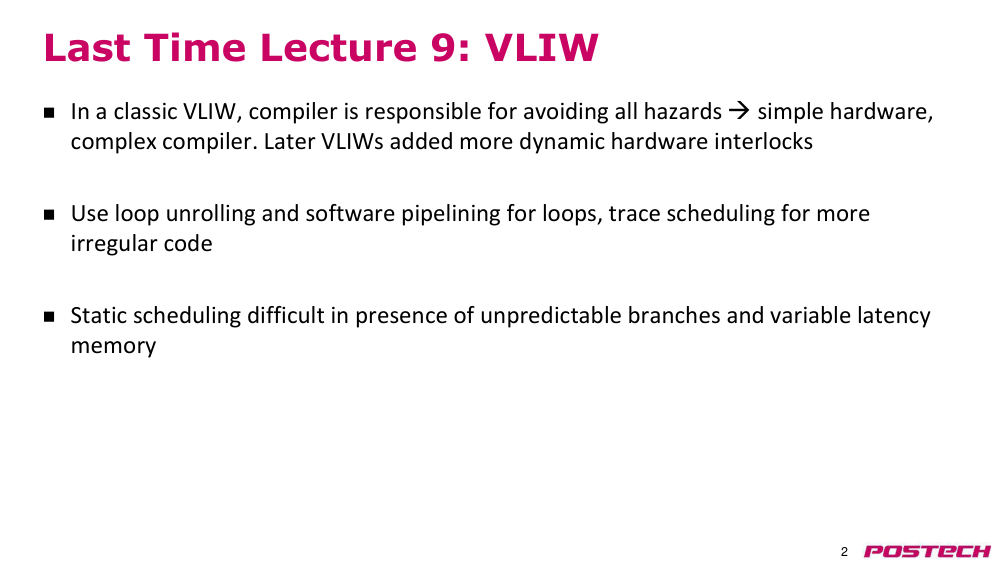
2.10:38–3:12도입과 복습: VLIW 의 한계
상황·문제이번 주제는 multithreading. 지난 강의 VLIW 를 요약하며 시작.
원인classic VLIW 는 compiler 가 hazard 를 scheduling 으로 피해 hardware 가 단순. 이후 EPIC(Itanium) 은 hardware dependence tracking 을 더했다.
해결loop unrolling·software pipelining(규칙적 loop), trace scheduling(비정형 code), predication·speculative load. 한계는 예측 불가 branch 와 가변 memory latency.
- static scheduling 은 unpredictable branch·variable latency memory 앞에서 어렵다
- 단일 thread 에서 ILP 를 더 뽑기 어렵다는 것이 이번 강의의 출발점
2.23:13–8:46TLP 와 fixed interleave: CDC 6600 PP
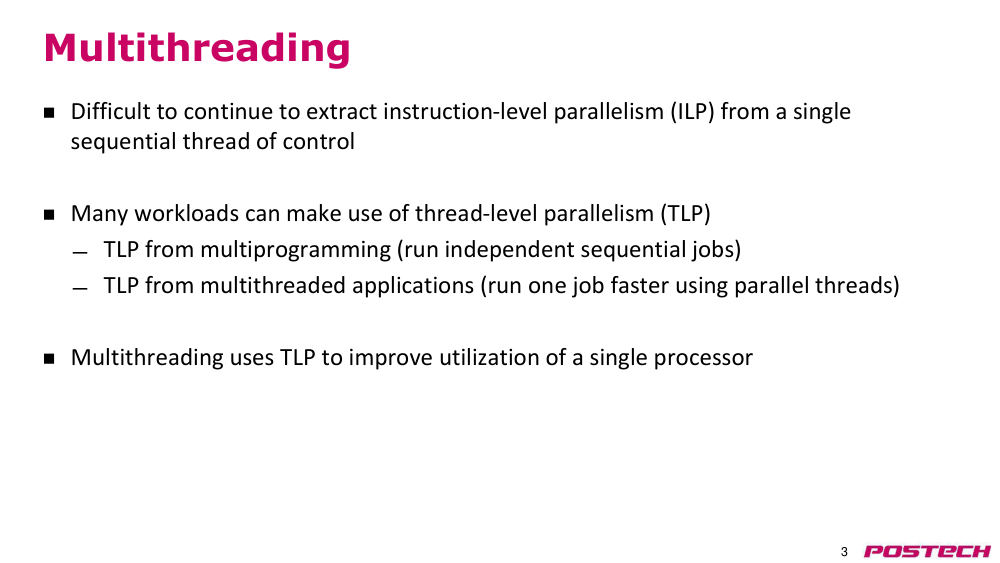
상황·문제단일 제어 흐름에서 ILP 추출이 어렵다. 대안은 thread-level parallelism(TLP, 스레드 수준 병렬성).
원인TLP 출처는 multiprogramming(독립 process 동시 실행)과 multithreaded application(한 작업을 여러 thread 로). 한 thread 안의 dependence 는 bypass·stall 을 요구한다.
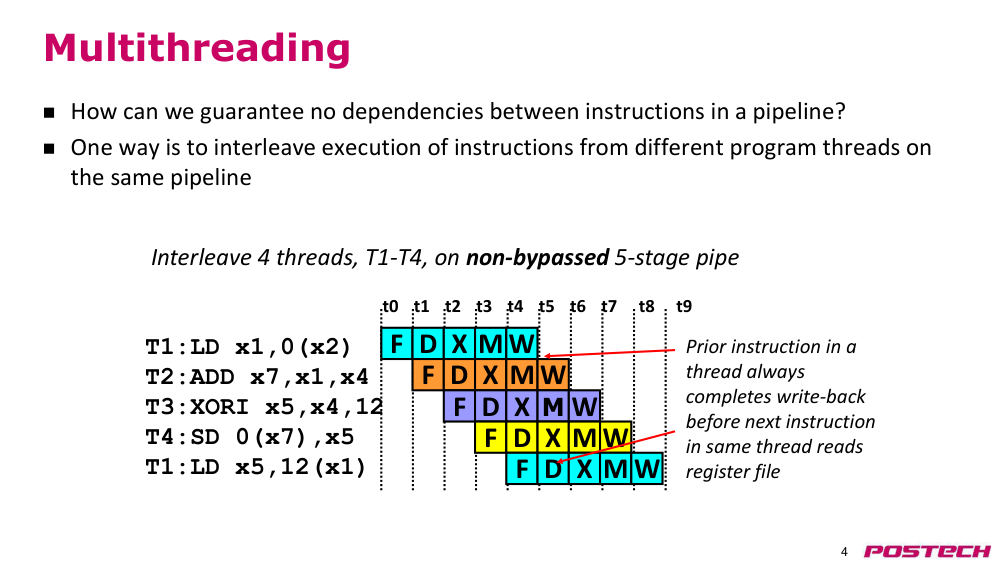
해결4 thread 를 non-bypassed 5-stage pipeline 에 cycle 마다 번갈아 넣으면 같은 thread 다음 instruction 이 register file 을 읽을 때 앞 write-back 이 끝나 있다. CDC 6600 PP 가 이 방식(100ns cycle, 10 thread, thread 당 1000ns 에 1 instruction).
- forwarding·stall 없이 pipeline 을 채움
- CDC 6600 PP: accumulator-based ISA 로 processor state 축소
- ready thread 가 없으면 bubble, I/O bound 작업이라 허용
2.2.r.1Barrel processor — Wikipedia ↗ · cycle 마다 thread 를 돌리는 fixed interleave 구조, CDC 6000 PP·Tera MTA 예
2.38:47–14:11Multithreaded pipeline 구조와 비용
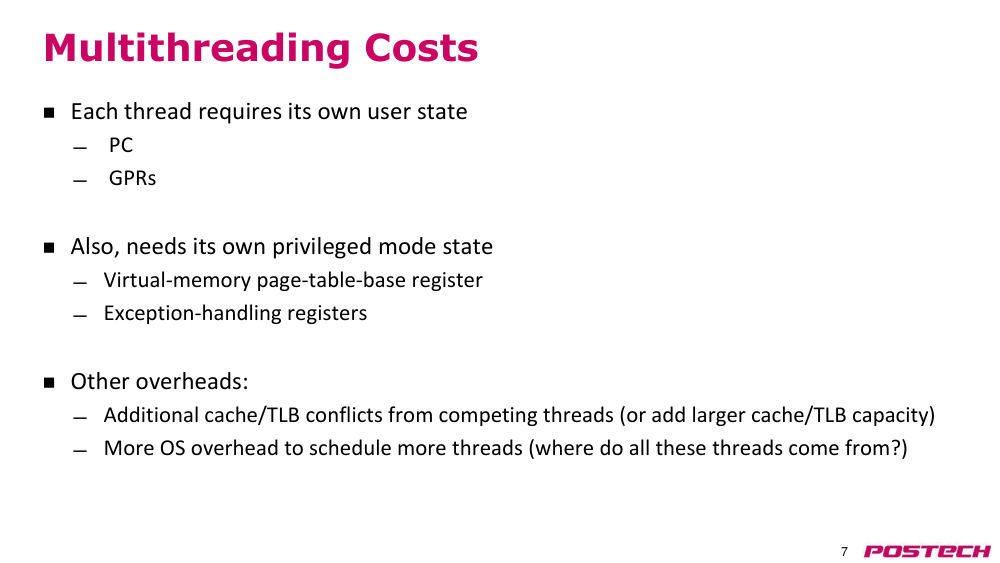
상황·문제여러 thread context 를 한 processor 에서 유지해야 한다.
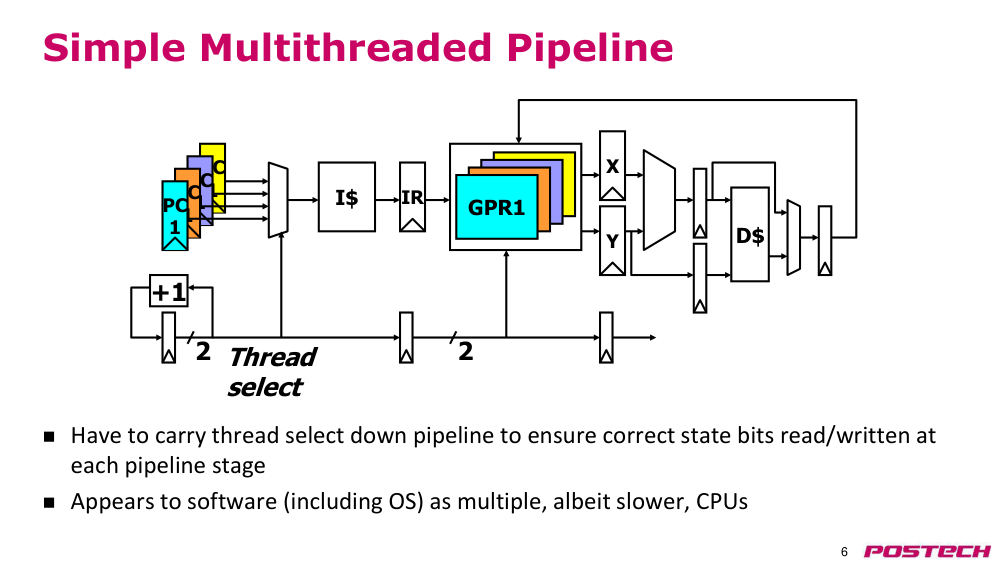
원인thread 마다 PC·GPR 이 필요하고, write-back 때 해당 thread 의 register file 을 골라야 한다.
해결thread select bit 를 pipeline 끝까지 전달. software(OS 포함) 에는 느린 CPU 여러 개로 보인다. 추가로 page-table-base register·exception-handling register 를 thread 마다 둔다.
- I$·execution unit·D$ 는 공유 → thread 각각은 느려지지만 memory stall 동안 다른 thread 로 utilization 향상
- 공유 cache·TLB·branch predictor·physical register 충돌 → 더 큰 용량 필요
- software 쪽 thread 생성·synchronization overhead
2.3.r.1Multithreading (computer architecture) — Wikipedia ↗ · coarse-grained·fine-grained(interleaved)·SMT 분류와 복제해야 할 state
2.414:12–17:09Thread scheduling policy 3종과 질의응답
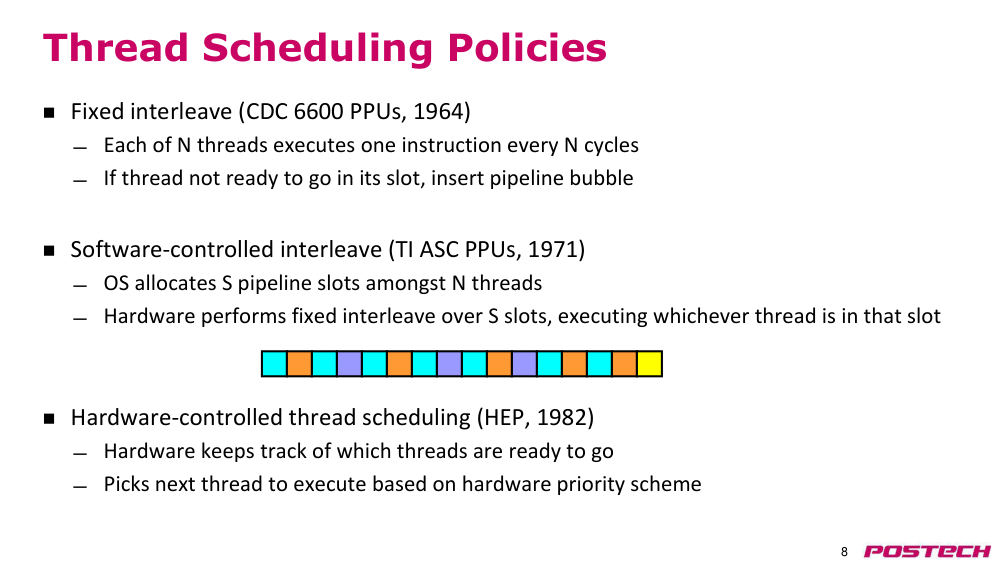
상황·문제여러 thread 를 hardware 에 어떻게 배정할지.
원인fixed interleave 는 해당 slot thread 가 준비 안 되면 bubble 이 생겨 utilization 이 떨어진다.
해결software-controlled interleave(TI ASC, 1971: OS 가 S slot 을 N thread 에 배정), hardware-controlled scheduling(HEP, 1982: ready thread 추적 + priority).
- 질문: thread 간 load/store dependence 는? → programmer 책임, mutex 등으로 동기화
2.4.r.1Heterogeneous Element Processor — Wikipedia ↗ · Denelcor HEP(1982, Burton Smith), PSW queue 로 hardware thread 관리
2.517:10–22:38Fine-grain MT: Denelcor HEP 와 Tera MTA
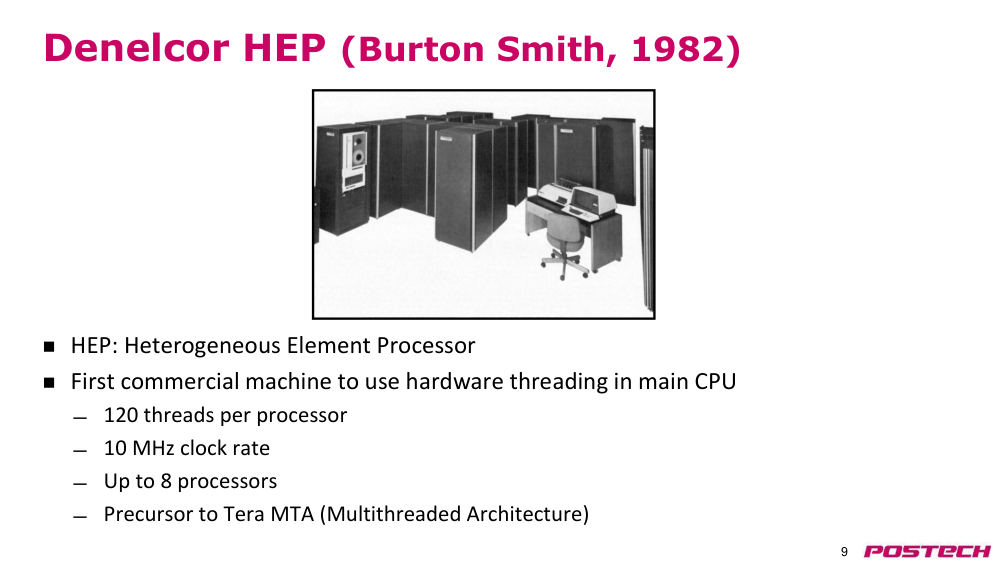
상황·문제main CPU 에 hardware threading 을 쓴 첫 상용기 HEP(processor 당 120 thread, 10 MHz, 최대 8 processor). 후속이 Tera MTA.
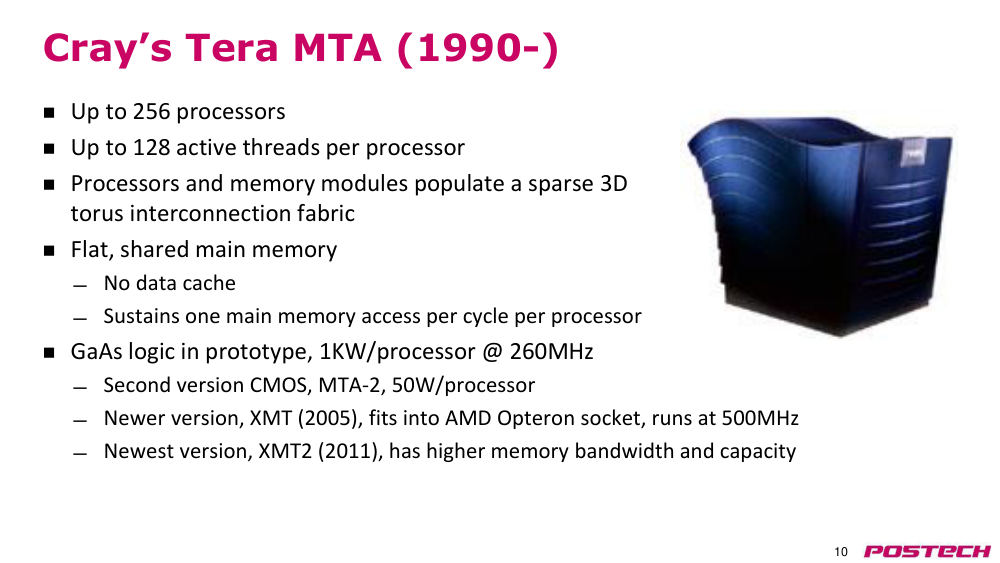
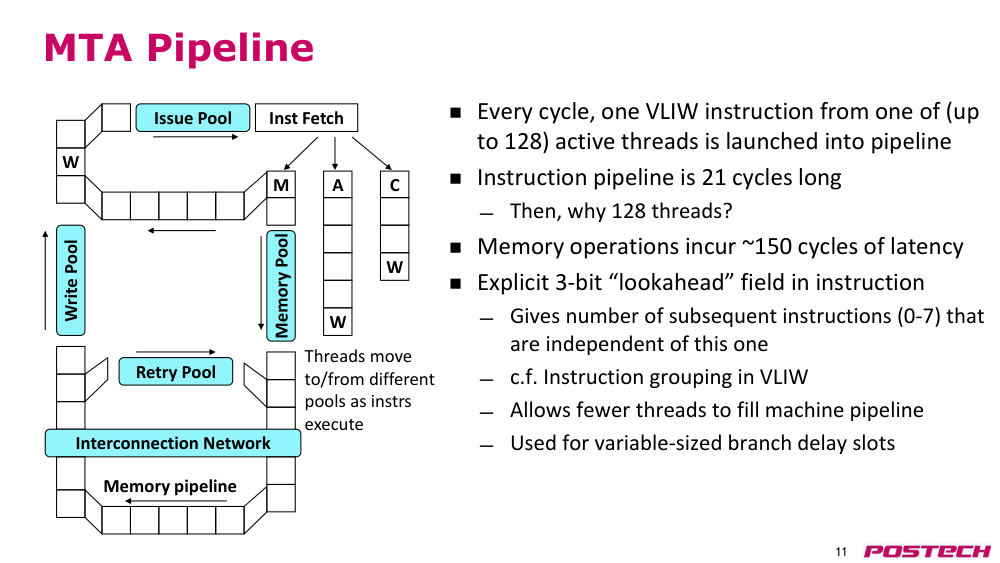
원인MTA 는 data cache 가 없어 memory access 가 약 150 cycle. 21-cycle pipeline 이라도 이를 숨기려면 thread 가 많이 필요.
해결processor 당 최대 128 thread, cycle 마다 한 thread 의 VLIW instruction 발행. memory 연산 중인 thread 는 memory pool 로 빠진다. 3-bit lookahead(0–7) 로 뒤따르는 독립 instruction 을 먼저 내 thread 수를 줄인다.
- 최대 256 processor, sparse 3D torus, flat shared memory, cycle 당 processor 당 memory access 1회
- GaAs prototype 1KW/processor @260MHz → MTA-2 CMOS 50W → XMT(2005) 는 AMD Opteron socket 호환
- lookahead 는 variable-sized branch delay slot 에 비유
2.5.r.1Heterogeneous Element Processor — Wikipedia ↗ · Denelcor HEP(1982, Burton Smith), PSW queue 로 hardware thread 관리
2.622:39–30:05Coarse-grain MT: MIT Alewife, IBM RS64-IV
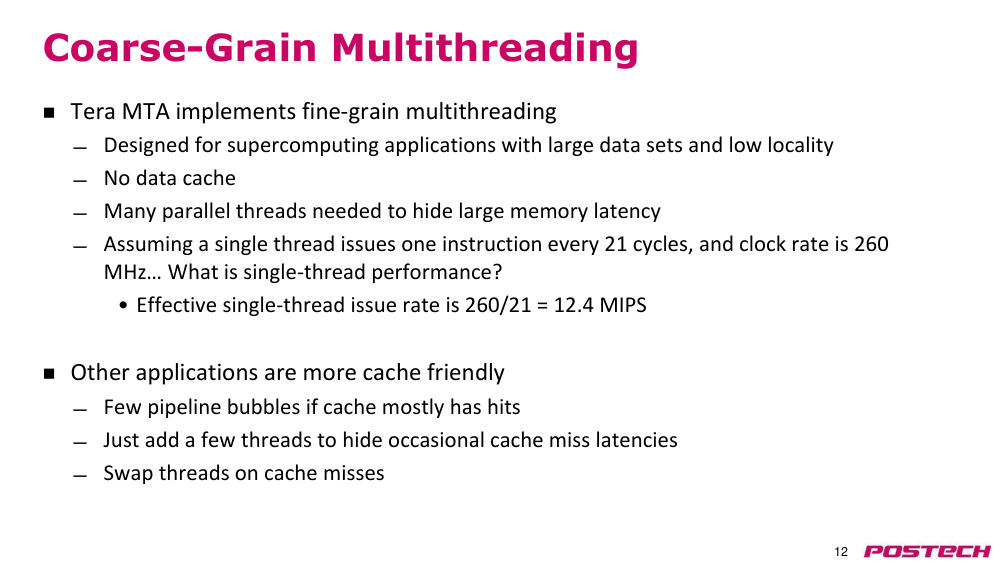
상황·문제fine-grain MT 는 single-thread 성능이 낮다: 21 cycle 마다 1 instruction, 260 MHz → 12.4 MIPS.
원인MTA 는 cache 없는 supercomputing 용 설계. 현대 processor 는 on-chip cache 가 대부분 access 를 걸러 bubble 이 적다.
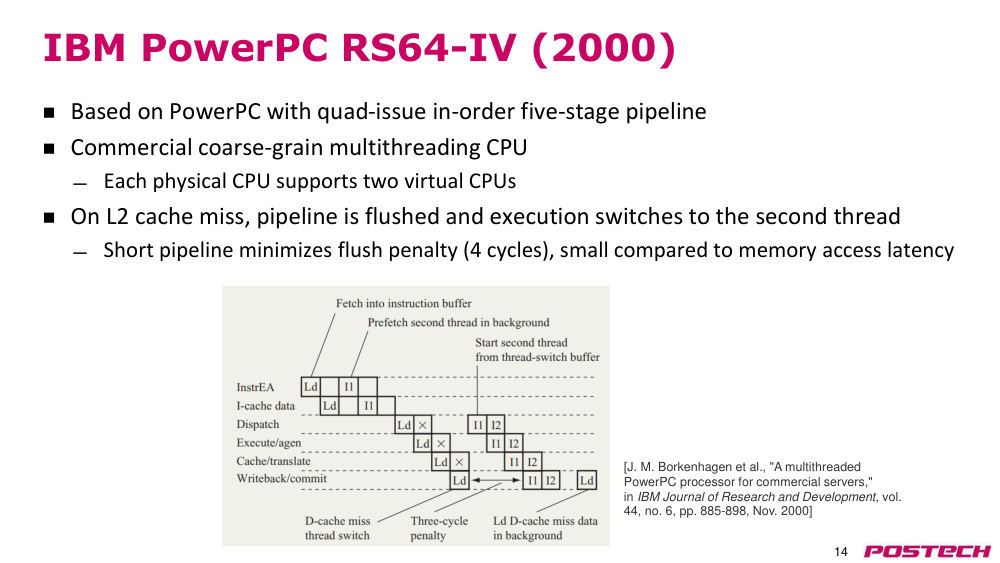
해결coarse-grain: 한 thread 를 계속 실행하다 cache miss 때만 교체. Alewife(1990) 는 SPARC register window 로 최대 4 thread context 유지, local cache miss 때 switch. RS64-IV(2000) 는 2 virtual CPU, L2 miss 때 pipeline flush 후 전환.
- RS64-IV 는 quad-issue in-order 5-stage 라 flush penalty 4 cycle 이 memory latency 대비 작다
- 두 번째 thread instruction 을 미리 prefetch 해 전환 즉시 실행
- deep pipeline 에서는 이 방식이 비현실적
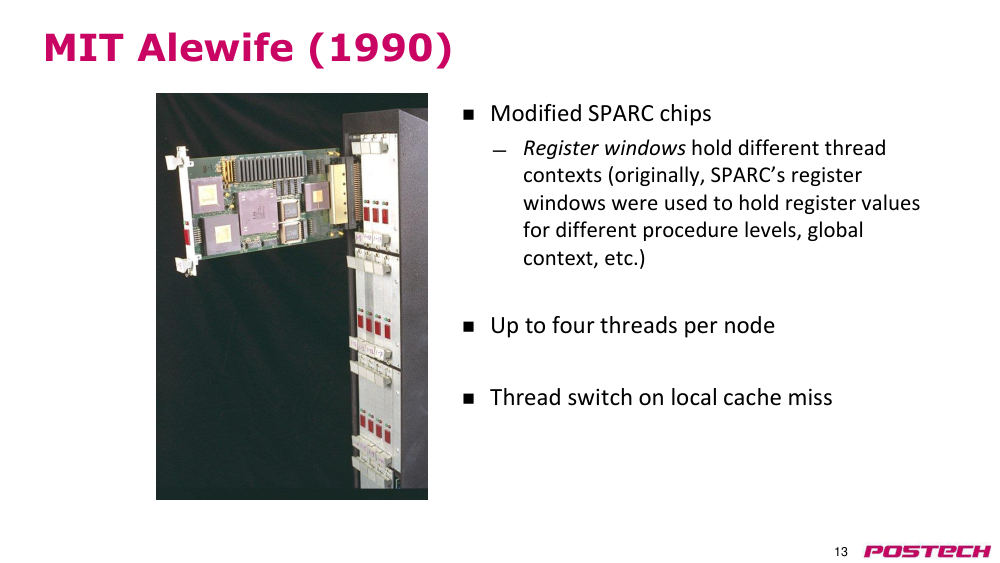
2.6.r.1Alewife (multiprocessor) — Wikipedia ↗ · SPARC 를 고쳐 fast context switch 를 넣은 Sparcle 기반 MIT machine
2.6.r.2Multithreading (computer architecture) — Wikipedia ↗ · coarse-grained·fine-grained(interleaved)·SMT 분류와 복제해야 할 state
2.730:06–34:53Oracle/Sun Niagara 와 SPARC M6
상황·문제web/DB server 처럼 동시 요청이 많은 datacenter 를 겨냥.
원인요청 단위 병렬성이 많아 single-thread 성능보다 throughput·energy/operation 이 중요.
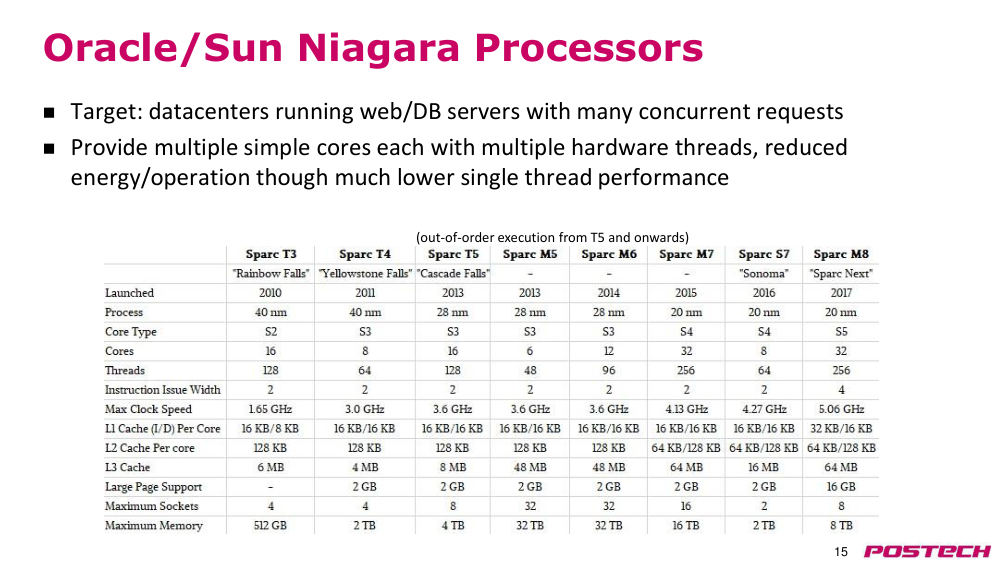
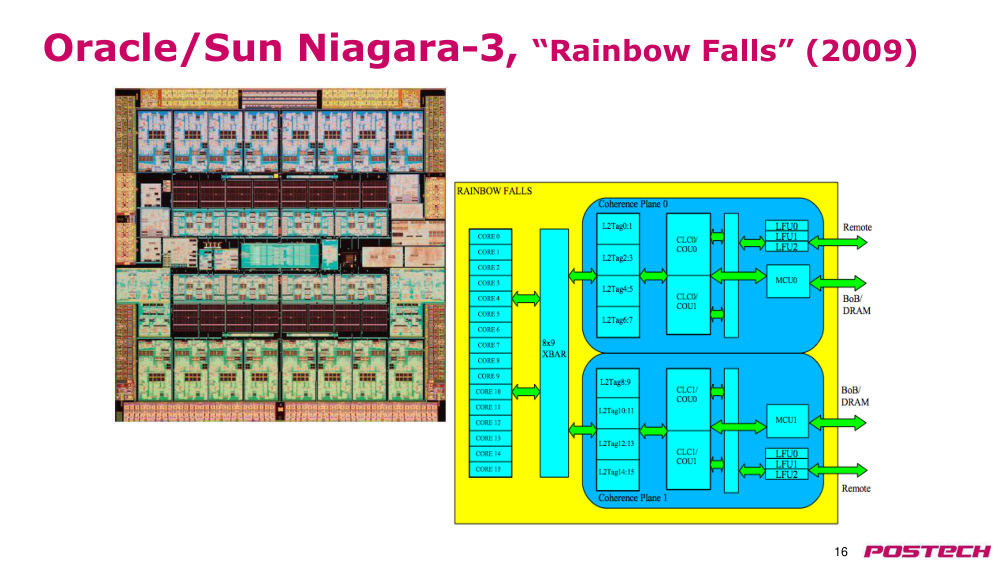
해결단순 core 여러 개 × core 당 여러 hardware thread. T3 는 16 core·128 thread(2010), M8 은 32 core·256 thread(2017). 뒤 세대는 out-of-order 와 큰 cache 를 더해 thread 수와 single-thread 속도의 균형을 잡았다.
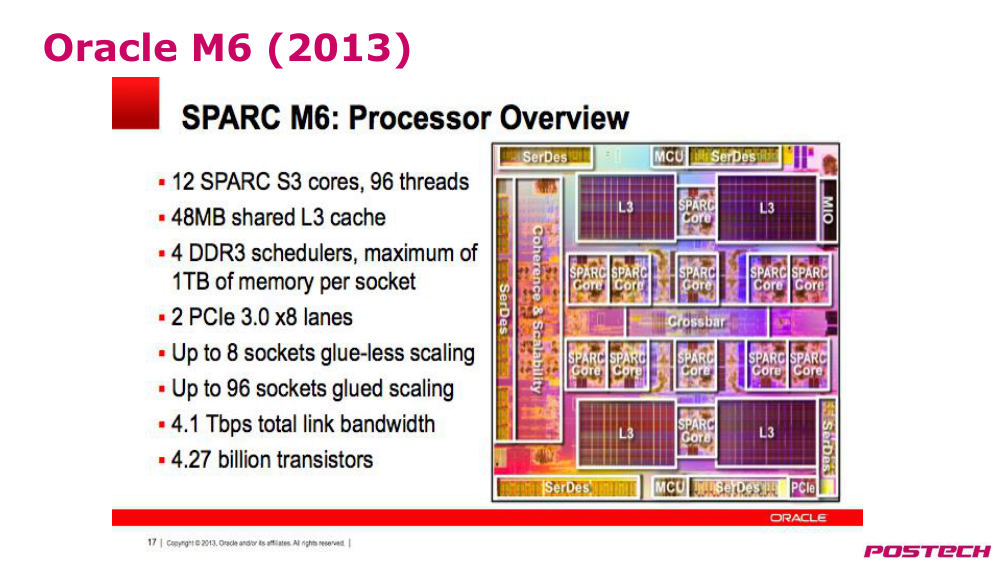
- M6(2013): 12 S3 core·96 thread, 48MB L3, glue-less 8 socket·glued 96 socket
- S3 core: dual-issue OoO, 1–8 strand dynamically threaded
- 강사가 Niagara-3 를 T2 로 추정했으나 Rainbow Falls 는 T3
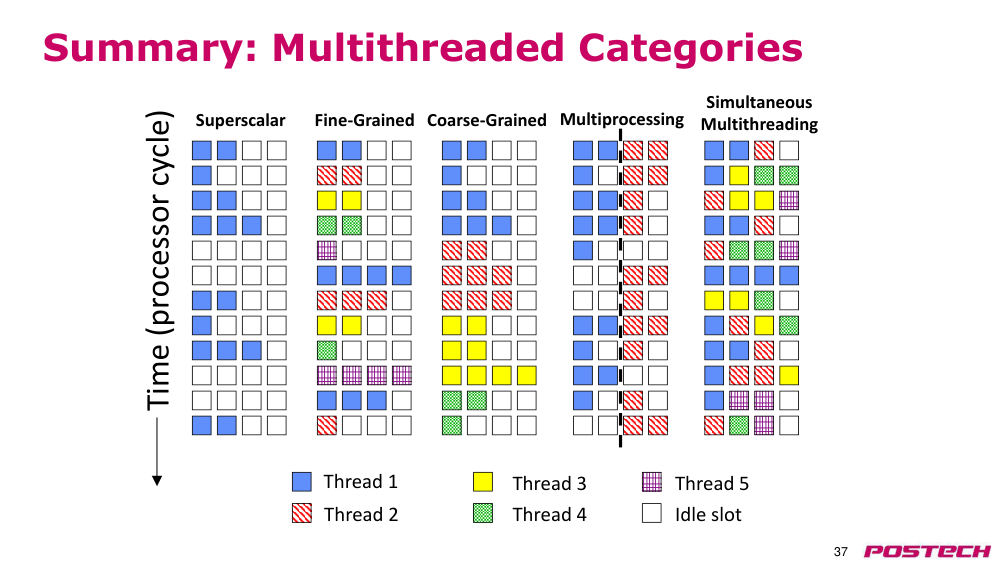
2.834:54–45:35SMT 개념: vertical·horizontal waste 와 CMP 비교
상황·문제지금까지는 vertical multithreading: 한 cycle 에 한 thread 의 instruction 만 발행.
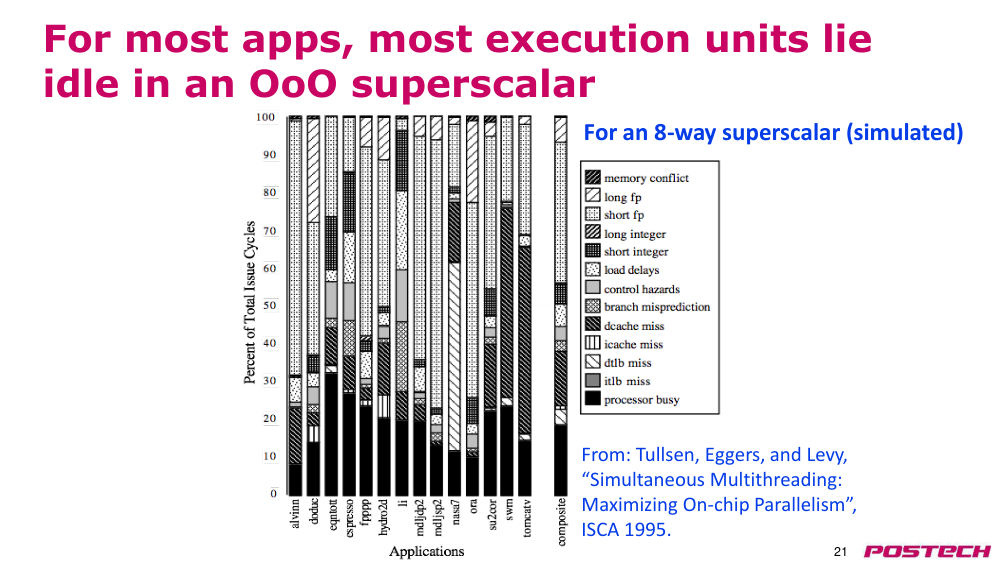
원인8-way superscalar 시뮬레이션에서 issue cycle 활용률은 최대 30% 남짓. 한 cycle 이 비는 vertical waste 와 일부만 차는 horizontal waste 가 있다.
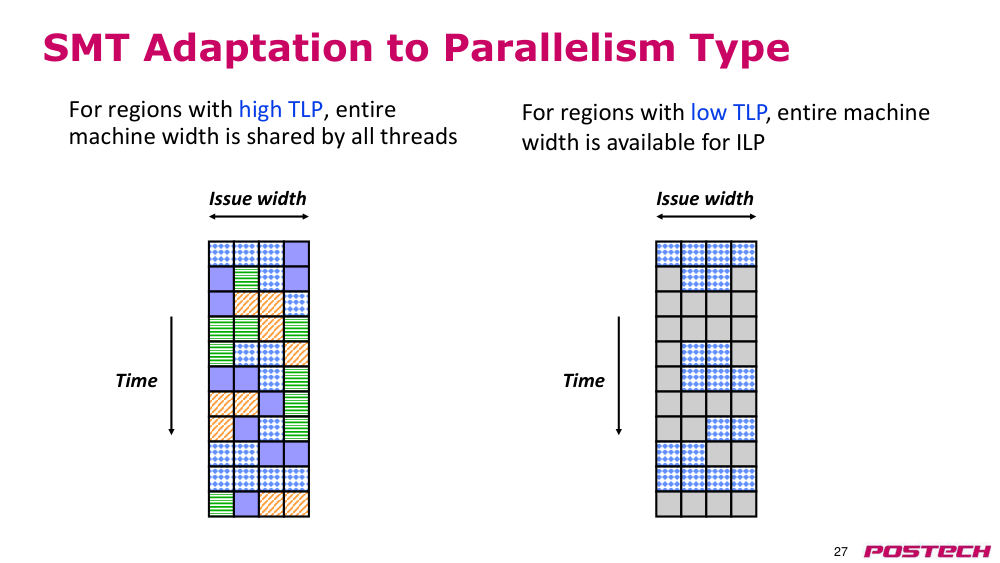
해결OoO superscalar 는 이미 instruction window 에서 ready instruction 을 고르는 회로가 있다. PC·GPR·fetch unit 만 늘려 여러 thread 를 같은 cycle 에 발행하는 SMT.
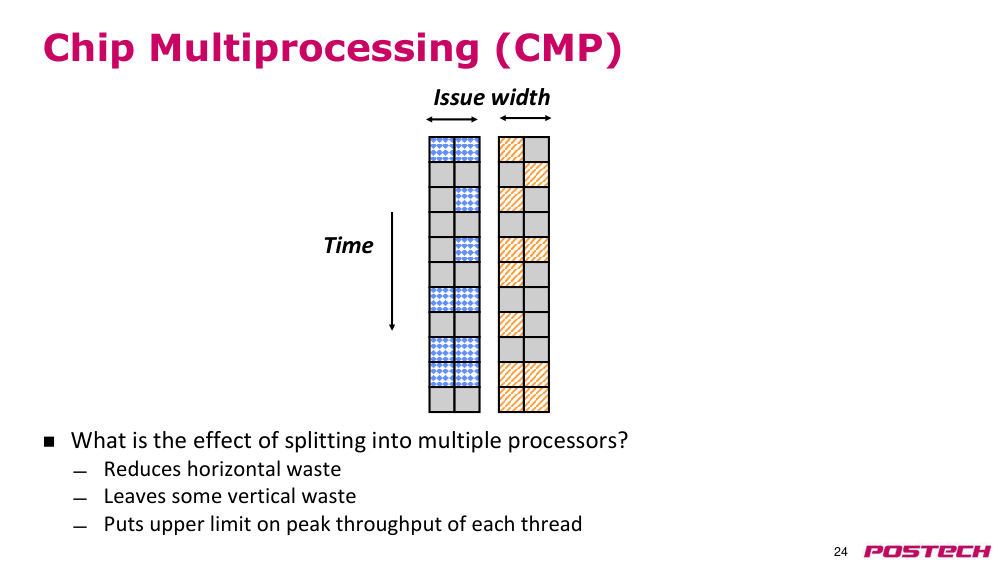
- vertical MT 는 vertical waste 만 제거, CMP 는 horizontal waste 를 줄이지만 thread 당 peak 가 issue width 로 제한
- SMT 는 high TLP 에서 전체 폭을 공유, low TLP 에서는 한 thread 가 전체 폭을 사용
- 2683s 부근에서 CMP 슬라이드(p24)로 잠시 돌아가 비교
2.8.r.1Tullsen, Eggers, Levy, Simultaneous Multithreading: Maximizing On-Chip Parallelism (ISCA 1995) ↗ · 8-way superscalar issue slot 낭비 분석과 SMT 제안 원 논문
2.8.r.2Tullsen et al., Exploiting Choice: Instruction Fetch and Issue on an Implementable SMT Processor (ISCA 1996) ↗ · OoO SMT 구현과 ICOUNT fetch policy 원 논문
2.945:36–49:09상용 SMT: Pentium 4 Hyper-Threading, IBM Power5
상황·문제SMT 가 실제 제품에 들어간 사례.
원인logical processor 는 cache·execution unit·branch predictor 를 공유. 한 thread 가 자원을 독점하면 다른 thread 가 starvation.
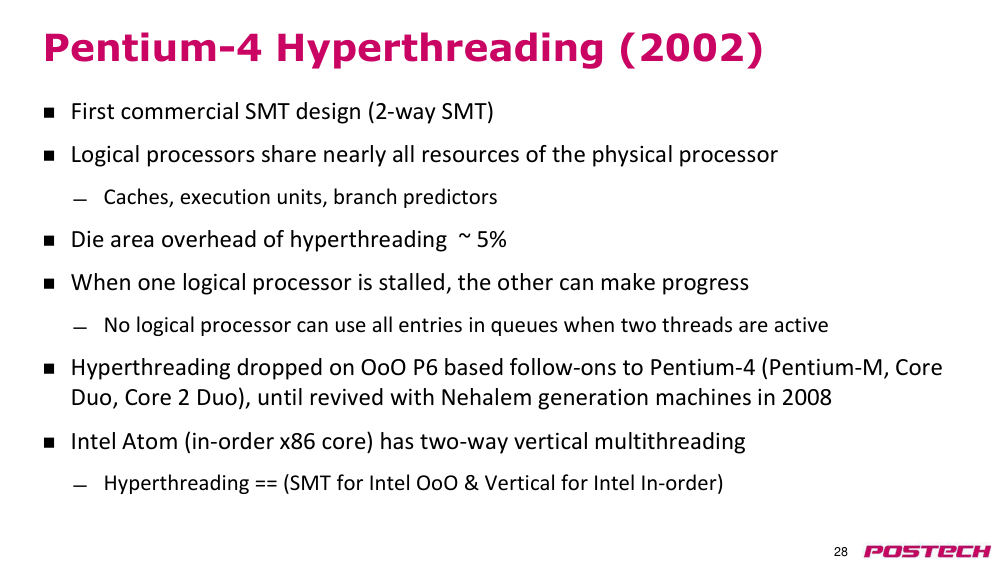
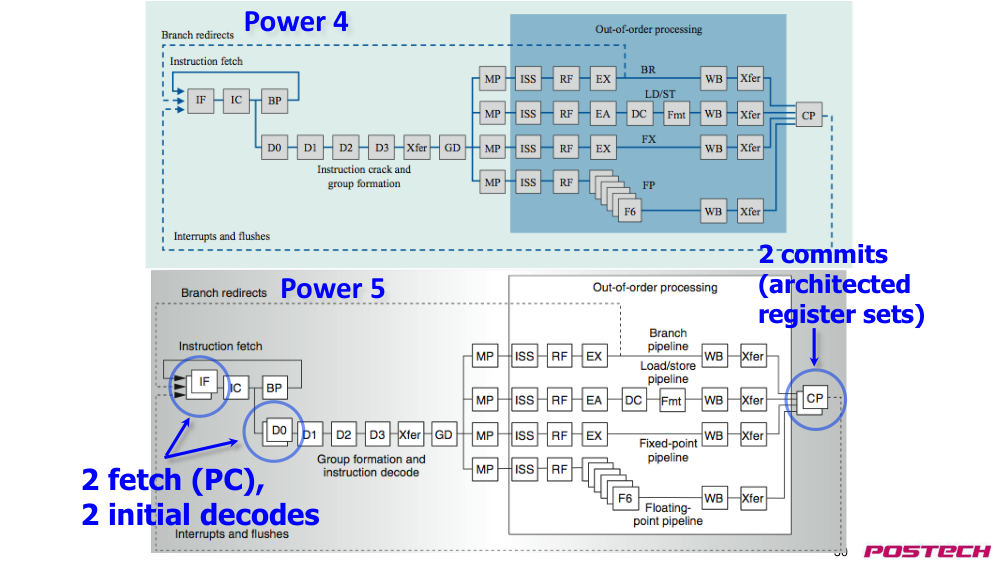
해결Pentium 4(2002) 는 2-way SMT, die area overhead 약 5%, 두 thread 활성 시 queue entry 를 전부 쓰지 못하게 하는 fairness. Power5 는 fetch(PC)·initial decode·commit 을 2벌로.
- Pentium-M·Core 계열에서 빠졌다가 Nehalem(2008) 에서 복귀
- Intel Atom(in-order) 의 'Hyper-Threading' 은 vertical MT, marketing 용어
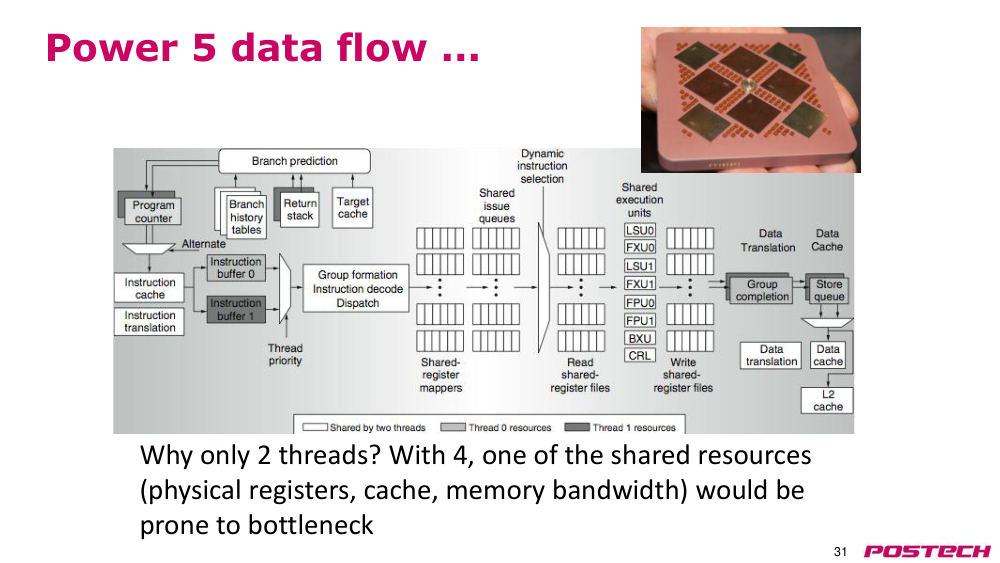
- Power5 가 2 thread 인 이유: 4개면 physical register·cache·memory bandwidth 가 병목
2.1049:10–57:18SMT 초기 성능과 application 간 간섭
상황·문제Pentium 4 SPECRate(같은 benchmark 두 copy) speedup 은 SPECint 1.01, SPECfp 1.07 에 그쳤다.
원인같은 program 두 개는 같은 자원을 다툰다. 26 개 benchmark 를 서로 짝지으면 0.90–1.58, 평균 1.20. integer 와 FP program 처럼 다양한 조합이 자원을 나눠 쓴다.
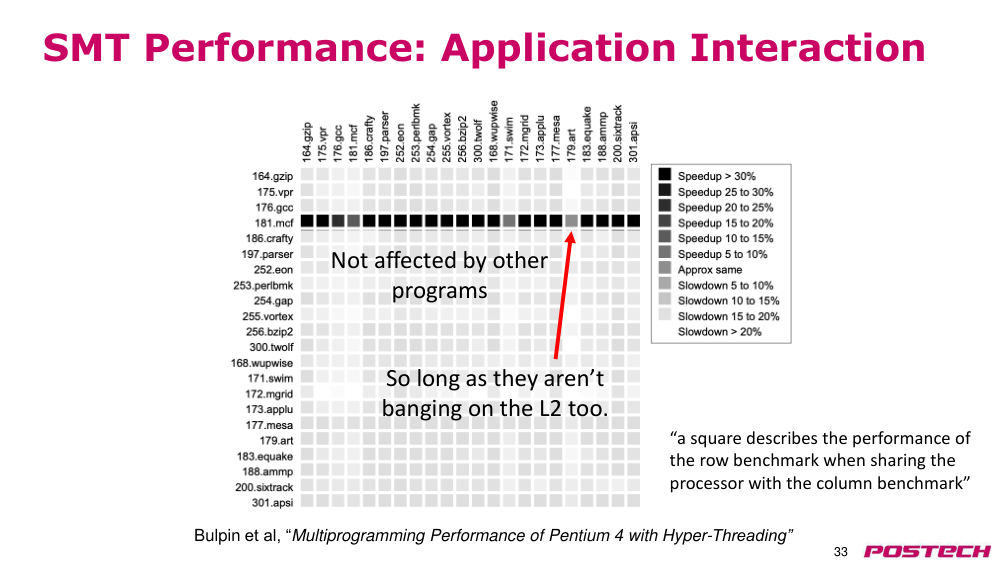
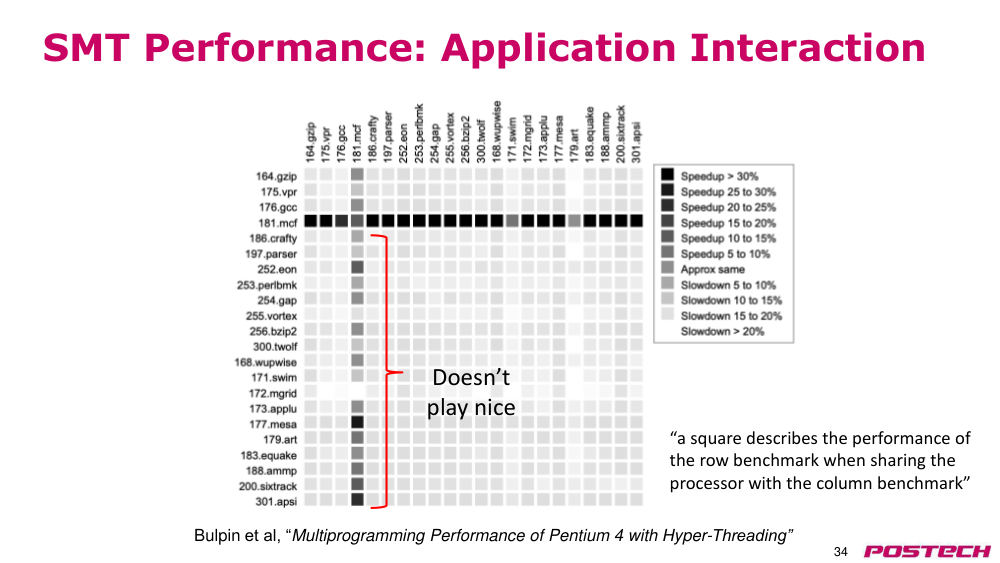
해결Power5 는 SPECint_rate 1.23x, SPECfp_rate 1.16x. Bulpin grid 에서 mcf 는 짝에 거의 무관하지만, mcf 와 짝지은 다른 program 은 cache thrashing 으로 느려진다.
- 성능은 application 조합에 따라 달라진다
- mcf 는 memory access 가 많아 L2 를 두드리는 program 과 짝지을 때만 손해
- p35: 두 번째 program 에 매우 민감한 benchmark 도 있다
2.10.r.1Bulpin & Pratt, Multiprogramming Performance of the Pentium 4 with Hyper-Threading (WDDD 2004) ↗ · SPEC CPU2000 쌍별 실행 결과 (mcf 행·열 grid) 원 논문
2.1157:19–1:02:59ICOUNT fetch policy 와 multithreading 분류 요약
상황·문제여러 thread 가 활성일 때 어느 thread 에서 fetch 할지.
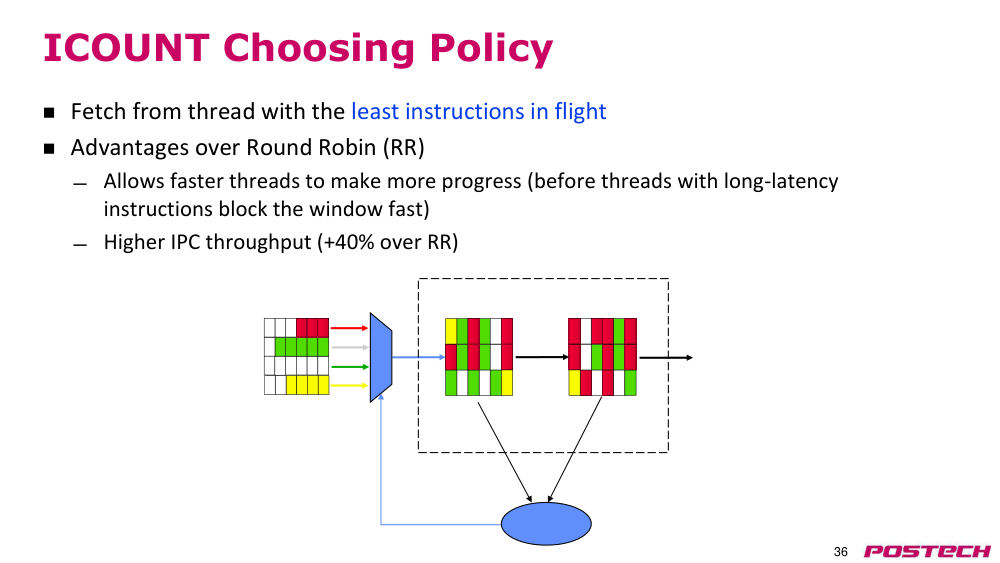
원인round-robin 은 cache miss 가 많은 thread 의 instruction 이 window 를 차지하고 long-latency load 를 기다리며 막는다.
해결ICOUNT: in-flight instruction 이 가장 적은 thread 에서 fetch. 빠른 thread 가 더 진행해 IPC throughput 이 RR 대비 최대 40% 높다.
- A(miss 많음)·B(compute) 예: A 성능은 조금 떨어지고 B 가 크게 오른다
- 요약도: superscalar·fine-grained·coarse-grained·multiprocessing·SMT 의 issue slot 사용 비교
2.11.r.1Tullsen et al., Exploiting Choice: Instruction Fetch and Issue on an Implementable SMT Processor (ISCA 1996) ↗ · OoO SMT 구현과 ICOUNT fetch policy 원 논문
2.121:03:00–1:05:44SMT 와 보안
상황·문제같은 core 를 공유하는 thread 는 서로의 timing 에 영향을 준다.
원인side channel 은 shared outer cache·DRAM row buffer 에도 있지만 SMT 는 TLB·L1·functional unit port 같은 private 자원에 high-bandwidth 접근을 준다.
해결TLBleed(2018.6), CacheBleed(2016), PortSmash(2018.11) 공격. OpenBSD 6.4 는 Intel HT 를 기본 비활성화. 통제된 환경(datacenter)에서는 SMT 가 비용을 낮춰 널리 쓰인다.
- branch predictor 까지 thread 간 공유
- 보안이 SMT 의 주요 단점
2.12.r.2Yarom, Genkin, Heninger, CacheBleed (IACR ePrint 2016/224) ↗ · L1 cache-bank conflict 로 OpenSSL RSA key 를 복구
2.12.r.3Aldaya et al., Port Contention for Fun and Profit (PortSmash, IACR ePrint 2018/1060) ↗ · SMT execution port contention side channel, CVE-2018-5407
2.131:05:45–1:07:42질의응답·시험 안내
상황·문제시험은 exam.net 사용, test exam 제공, Zoom 에 smartphone 연결 감독 예정. 세부 공지는 다음 날. 권장 읽기 Ch 3.11–3.14.
2.13.r.1Hennessy & Patterson, Computer Architecture: A Quantitative Approach 6th ed. (Elsevier) ↗ · 권장 읽기 3.11–3.14 (multithreading) 교과서
3핵심 개념
3.1thread-level parallelism(TLP, 스레드 수준 병렬성)
multiprogramming 또는 multithreaded application 에서 나오는 병렬성. multithreading 은 이를 이용해 단일 processor utilization 을 높인다.
3.1.r.1Multithreading (computer architecture) — Wikipedia ↗ · coarse-grained·fine-grained(interleaved)·SMT 분류와 복제해야 할 state
3.2fixed interleave(고정 인터리빙) / barrel processor
N thread 가 N cycle 마다 1 instruction. 같은 thread 의 앞 instruction 이 끝나 있어 bypass·interlock 불필요.
3.2.r.1Barrel processor — Wikipedia ↗ · cycle 마다 thread 를 돌리는 fixed interleave 구조, CDC 6000 PP·Tera MTA 예
3.3thread select(스레드 선택)
pipeline 을 따라 thread 번호를 전달해 각 stage 가 맞는 PC·register file 을 읽고 쓰게 한다.
3.4fine-grain multithreading(세립 다중 스레딩)
매 cycle thread 전환. latency 은닉에 강하지만 single-thread 성능이 낮다(MTA 12.4 MIPS).
3.4.r.1Multithreading (computer architecture) — Wikipedia ↗ · coarse-grained·fine-grained(interleaved)·SMT 분류와 복제해야 할 state
3.5lookahead field(미리보기 필드)
MTA instruction 의 3-bit 필드. 뒤따르는 독립 instruction 수(0–7) 를 알려 한 thread 에서 더 발행.
3.6coarse-grain multithreading(조립 다중 스레딩)
한 thread 를 계속 실행하다 cache miss 등 긴 stall 때만 전환. Alewife, RS64-IV.
3.6.r.1Multithreading (computer architecture) — Wikipedia ↗ · coarse-grained·fine-grained(interleaved)·SMT 분류와 복제해야 할 state
3.7vertical / horizontal waste(수직·수평 낭비)
vertical: 아무것도 발행 못한 cycle. horizontal: issue width 일부만 채운 cycle(IPC<4).
3.7.r.1Tullsen, Eggers, Levy, Simultaneous Multithreading: Maximizing On-Chip Parallelism (ISCA 1995) ↗ · 8-way superscalar issue slot 낭비 분석과 SMT 제안 원 논문
3.8simultaneous multithreading(SMT, 동시 다중 스레딩)
OoO superscalar 의 issue queue 로 여러 thread instruction 을 같은 cycle 에 발행. 필요하면 한 thread 가 전체 폭 사용.
3.8.r.2Tullsen et al., Exploiting Choice: Instruction Fetch and Issue on an Implementable SMT Processor (ISCA 1996) ↗ · OoO SMT 구현과 ICOUNT fetch policy 원 논문
3.9chip multiprocessing(CMP, 칩 멀티프로세싱)
자원을 여러 좁은 core 로 분할. horizontal waste 는 줄지만 thread 당 peak throughput 이 제한.
3.10Hyper-Threading(하이퍼스레딩)
Intel 의 SMT 이름(Pentium 4, 2002, die area ~5%). in-order Atom 에서는 vertical MT 를 뜻한다.
3.12ICOUNT policy
in-flight instruction 이 가장 적은 thread 에서 fetch. RR 대비 IPC 최대 +40%.
3.12.r.1Tullsen et al., Exploiting Choice: Instruction Fetch and Issue on an Implementable SMT Processor (ISCA 1996) ↗ · OoO SMT 구현과 ICOUNT fetch policy 원 논문
3.13side channel(부채널)
공유 자원의 timing 변화로 다른 thread 정보를 추론. SMT 는 TLB·L1·port 를 공유해 대역폭이 크다.
3.13.r.2Aldaya et al., Port Contention for Fun and Profit (PortSmash, IACR ePrint 2018/1060) ↗ · SMT execution port contention side channel, CVE-2018-5407
4스스로 확인
4.1non-bypassed pipeline 에서 4 thread fixed interleave 가 forwarding 없이 동작하는 이유는?
답
같은 thread 의 다음 instruction 이 4 cycle 뒤에 fetch 되어 register read 시점에 앞 instruction write-back 이 끝나 있다.
4.2hardware thread 마다 복제해야 하는 state 는?
답
user state(PC, GPR)와 privileged state(page-table-base register, exception-handling register).
4.3Tera MTA single thread 성능이 12.4 MIPS 인 이유는?
답
21-cycle pipeline 에서 한 thread 는 21 cycle 마다 1 instruction, 260 MHz/21 ≈ 12.4 MIPS.
4.4RS64-IV 가 L2 miss 때 pipeline flush 를 감당할 수 있었던 이유는?
답
in-order 5-stage 짧은 pipeline 이라 flush penalty 가 4 cycle 로 memory latency 보다 훨씬 작다.
4.5CMP 대비 SMT 의 장점은?
답
TLP 가 낮을 때 한 thread 가 전체 issue width 를 쓸 수 있어 single-thread peak 가 제한되지 않는다.
4.6Pentium 4 SPECRate 향상은 1.01/1.07 인데 서로 다른 benchmark 짝은 평균 1.20 인 이유는?
답
같은 program 두 copy 는 같은 자원을 다투고, 서로 다른 program(int vs FP)은 다른 자원을 써 utilization 이 오른다.
4.7ICOUNT 가 round-robin 보다 나은 이유는?
답
in-flight 가 적은 빠른 thread 를 우선 fetch 해 long-latency thread 가 window 를 막는 것을 줄인다(IPC 최대 +40%).
5참고 자료
5.1Hennessy & Patterson, Computer Architecture: A Quantitative Approach 6th ed. (Elsevier) ↗ · 권장 읽기 3.11–3.14 (multithreading) 교과서
5.2Multithreading (computer architecture) — Wikipedia ↗ · coarse-grained·fine-grained(interleaved)·SMT 분류와 복제해야 할 state
5.3Tullsen, Eggers, Levy, Simultaneous Multithreading: Maximizing On-Chip Parallelism (ISCA 1995) ↗ · 8-way superscalar issue slot 낭비 분석과 SMT 제안 원 논문
5.4Tullsen et al., Exploiting Choice: Instruction Fetch and Issue on an Implementable SMT Processor (ISCA 1996) ↗ · OoO SMT 구현과 ICOUNT fetch policy 원 논문
5.5Bulpin & Pratt, Multiprogramming Performance of the Pentium 4 with Hyper-Threading (WDDD 2004) ↗ · SPEC CPU2000 쌍별 실행 결과 (mcf 행·열 grid) 원 논문